2,020 posts tagged “llms”
Large Language Models (LLMs) are the class of technology behind generative text AI systems like OpenAI's ChatGPT, Google's Gemini and Anthropic's Claude.
2026
Introducing Our Smallest, Most Efficient Model: Muse Ember. Meta AI just launched their entry in the Claude Haiku/GPT Luna category: Muse Ember, which they describe as:
[...] our smallest and most efficient model designed for complex reasoning execution and the work agents repeat all day: tool calls, coding subtasks, routing, extraction, and long document parsing.
For shorter prompts it's priced the same as GPT-6 Luna and Claude Haiku 5.5 - both are $0.10/million input tokens and $0.50/million output. Today's other big model release, Claude Fable 5.2, is 80x that price at $8/$40.
The pricing is a little less straightforward as prompts get longer, though. Luna, Ember, and Haiku all support up to a million input tokens, but they also all have a threshold after which the price goes up. Taking that threshold into account Ember is priced between the two others:
| Model | Prompt size | Input ($/M) | Cached input | Output |
|---|---|---|---|---|
| GPT-6 Luna | ≤272k | $0.10 | $0.01 | $0.50 |
| >272k | $0.20 | $0.02 | $0.75 | |
| Muse Ember 1.0 | ≤200k | $0.10 | $0.004 | $0.50 |
| >200k | $0.30 | $0.012 | $1.50 | |
| Claude Haiku 5.5 | ≤100k | $0.10 | $0.01 | $0.50 |
| >100k | $0.50 | $0.05 | $2.50 |
But comparing price-per-token doesn't really make sense these days, when reasoning tokens mean that different models might use dramatically different numbers of tokens to solve the same problem.
For that, one measure that's useful is the Artificial Analysis.
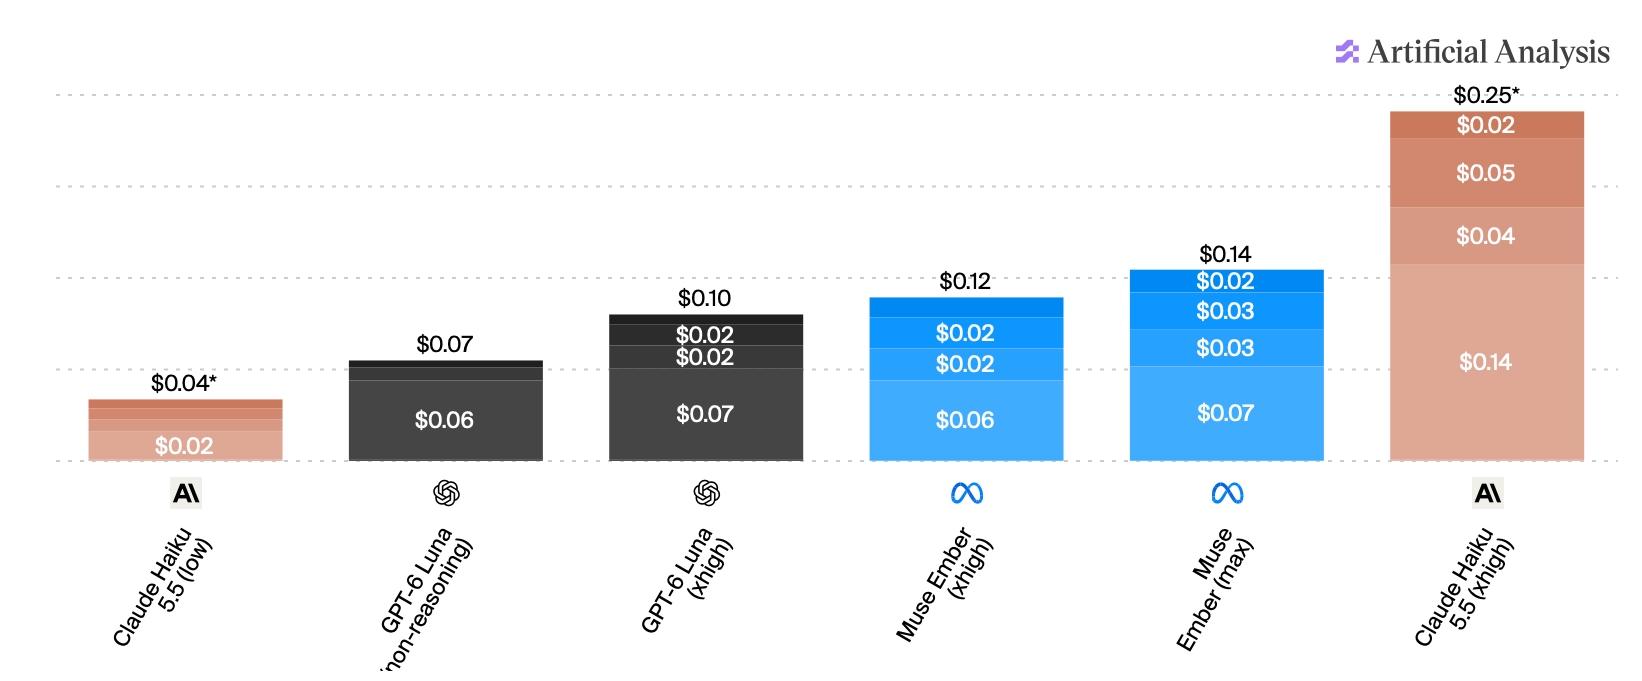
And even more useful than that is their Intelligence Index vs. Cost per Task chart, which shows the following for those three models:
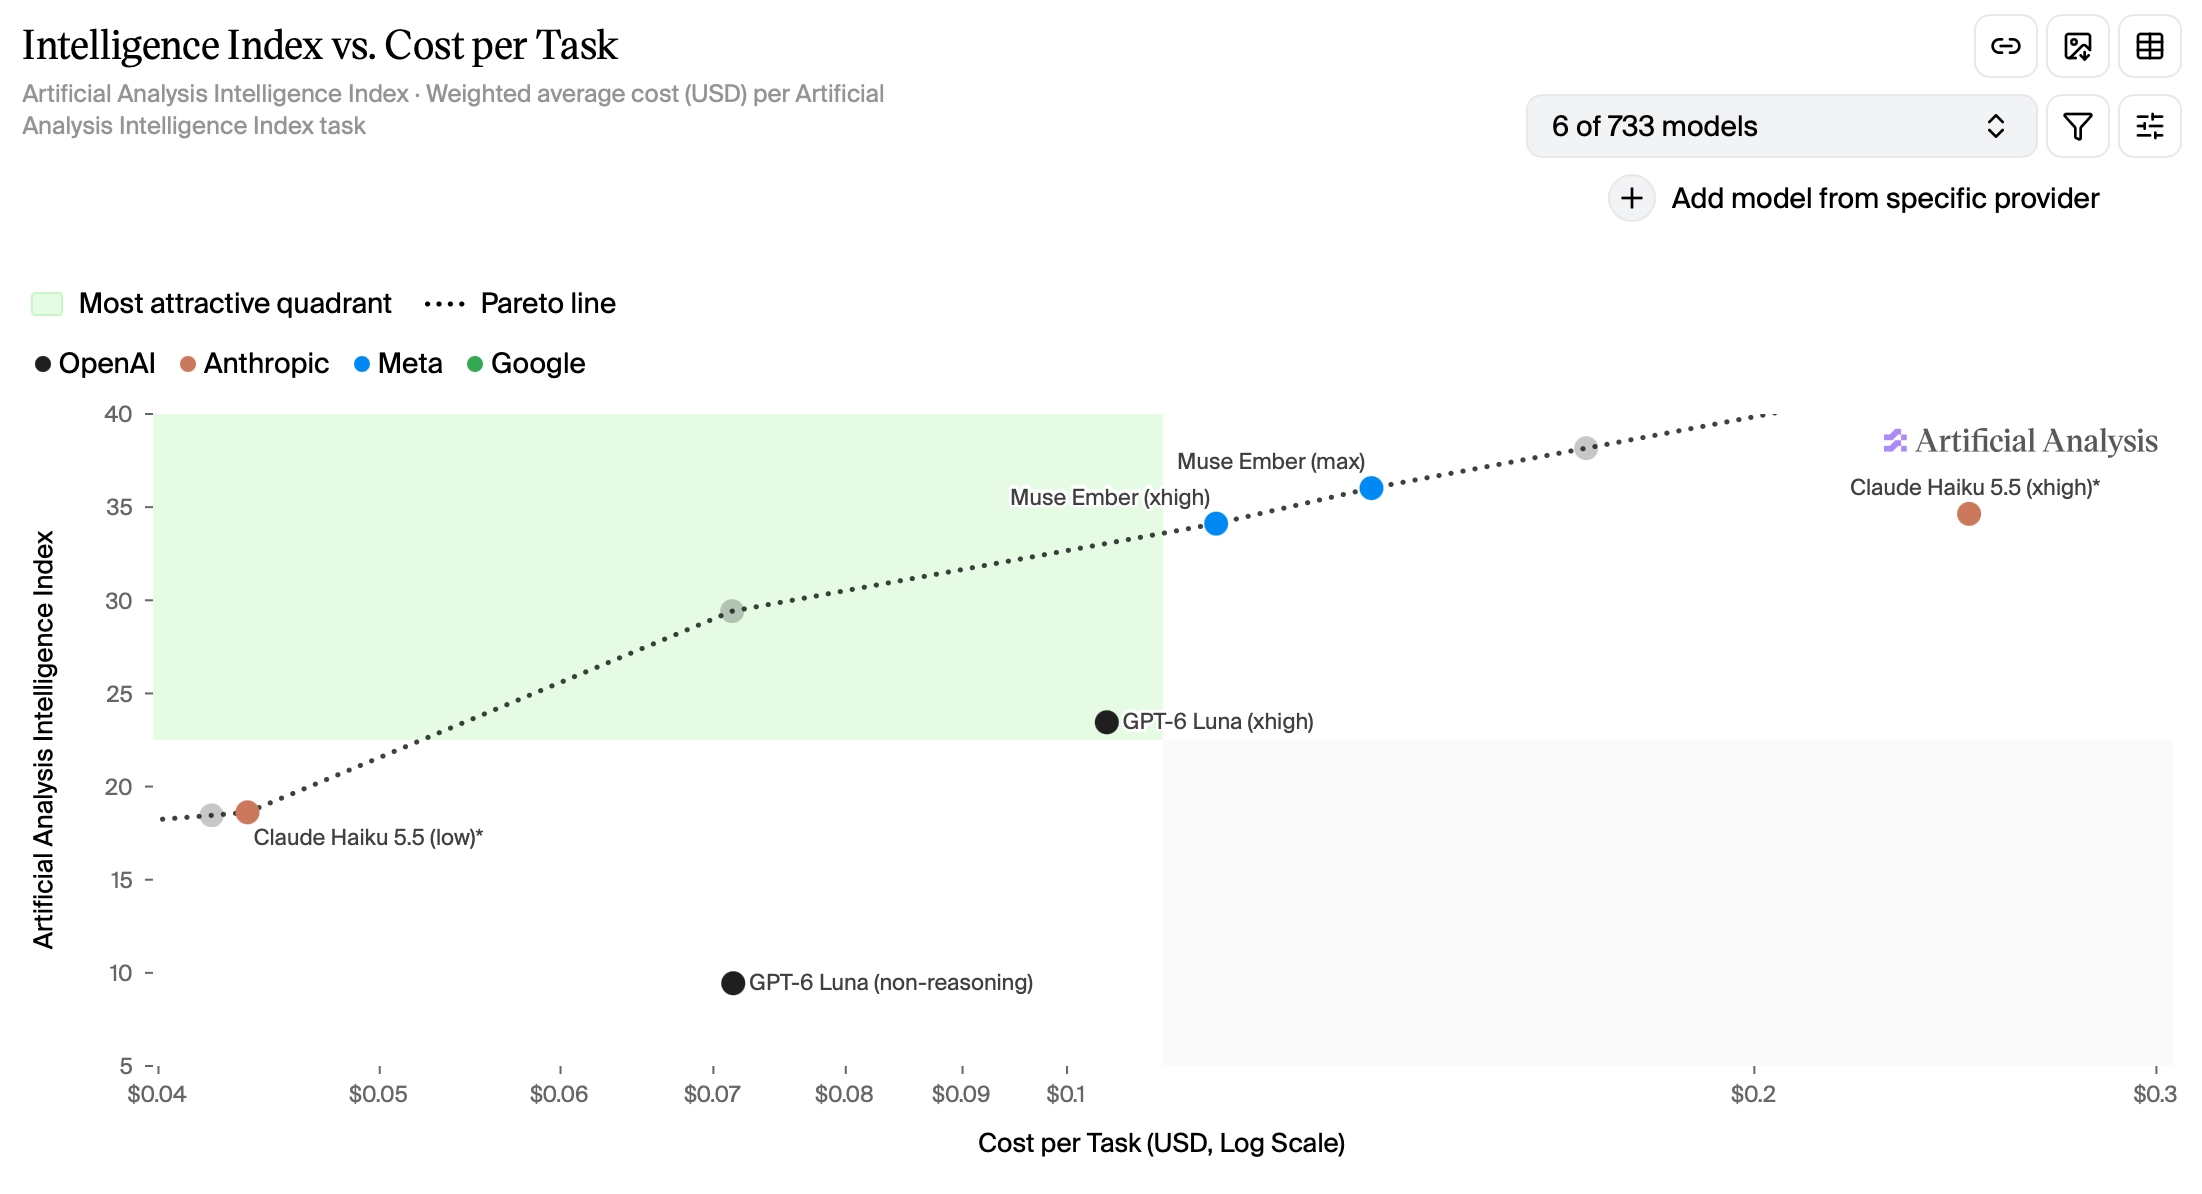
The Muse Ember models sit right on that Pareto line - the line at which you can only improve one dimension by giving up another. Meta call this out in their announcement:
It also sits on the efficiency frontier of the full Artificial Analysis leaderboard: no model scores higher for less per task.
(That grey dot on the Pareto line in the middle of the green area is GPT-6.1 Terra (low) - clearly I should be paying more attention to the Terra family!)
Muse Ember has six reasoning levels - minimal, low, medium, high, xhigh, and max - so I rendered six pelicans riding bicycles. The "high" reasoning level failed to return a full SVG, and the other SVGs were surprising in that the reasoning level didn't cleanly map to the visual quality of the response.
Here's the "max" one, but the others are worth a look too:
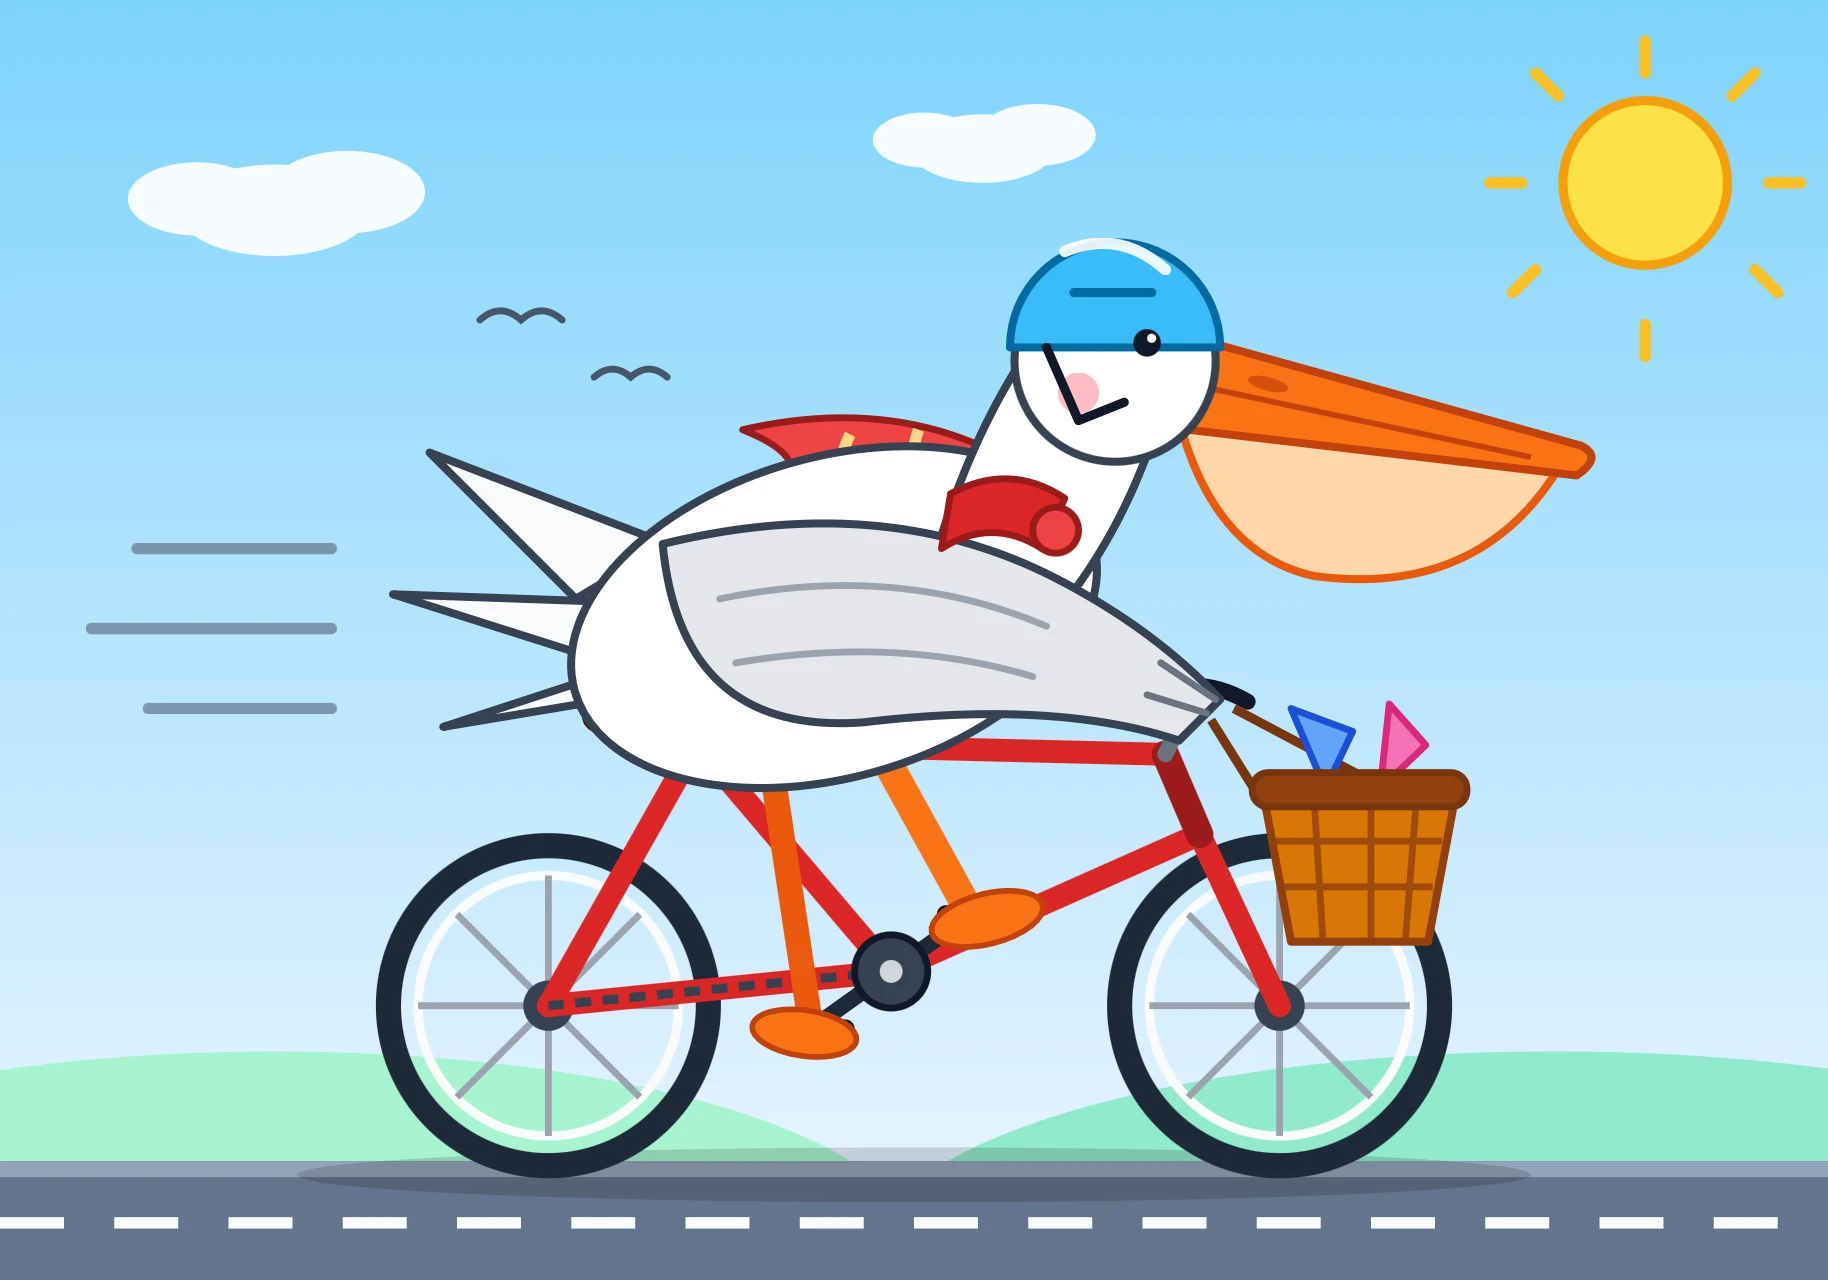
The Ember pelicans are comparable in quality to those I got from Muse Wonder, which is 40x the price of Muse Ember.
Claude Fable 5.2 responds closely to what the prompt says about who owns the code it works on. In Anthropic’s testing on small coding tasks, when a prompt said nothing about ownership or presented the code base as someone else’s, the model tended to add to the existing structure, even when that repeated existing code. [...]
If you want the model to improve the structure as it works, say that the code is its own:
This codebase is yours: what it's for and how it's built are your call, and you'll keep building on it.In Anthropic’s testing on small coding tasks, the model merged repeated code in about half of the tries with this sentence, and in under a tenth of the tries without it.
— Prompting Claude Fable 5.2, Anthropic documentation
I realized I didn't know where Yonkers was, so I looked it up on Google Maps and then, to help embed its location and shape in my head (and to try out Claude Fable 5.2's 3D modeling and animation skills), I prompted Fable 5.2 Medium to:
Make a three js animation where yonkers stands up as a big mech (cool stand up motion) and átomos around manhattan and queens and Brooklyn, use openstreetmap mapping data
It correctly deduced that "átomos" was a mobile keyboard typo for "stomps":
Anthropic released Fable 5.2 and Mythos 5.2 today. Fable 5.2 is currently ranked first on Artificial Analysis. Anthropic say it "solved two open problems in the physics of black holes", so clearly their internal benchmarks have become more ambitious!
I've added the new models to llm-anthropic, so you can now run prompts through Fable 5.2 like this:
uv tool install llm
llm install llm-anthropic
llm keys set anthropic
# paste key here
llm -m claude-fable-5.2 "Generate an SVG of a pelican riding a bicycle"
I ran pelicans at all five reasoning levels - low, medium, high, xhigh, and max. You can see them all here - here's the best result I got, from xhigh:
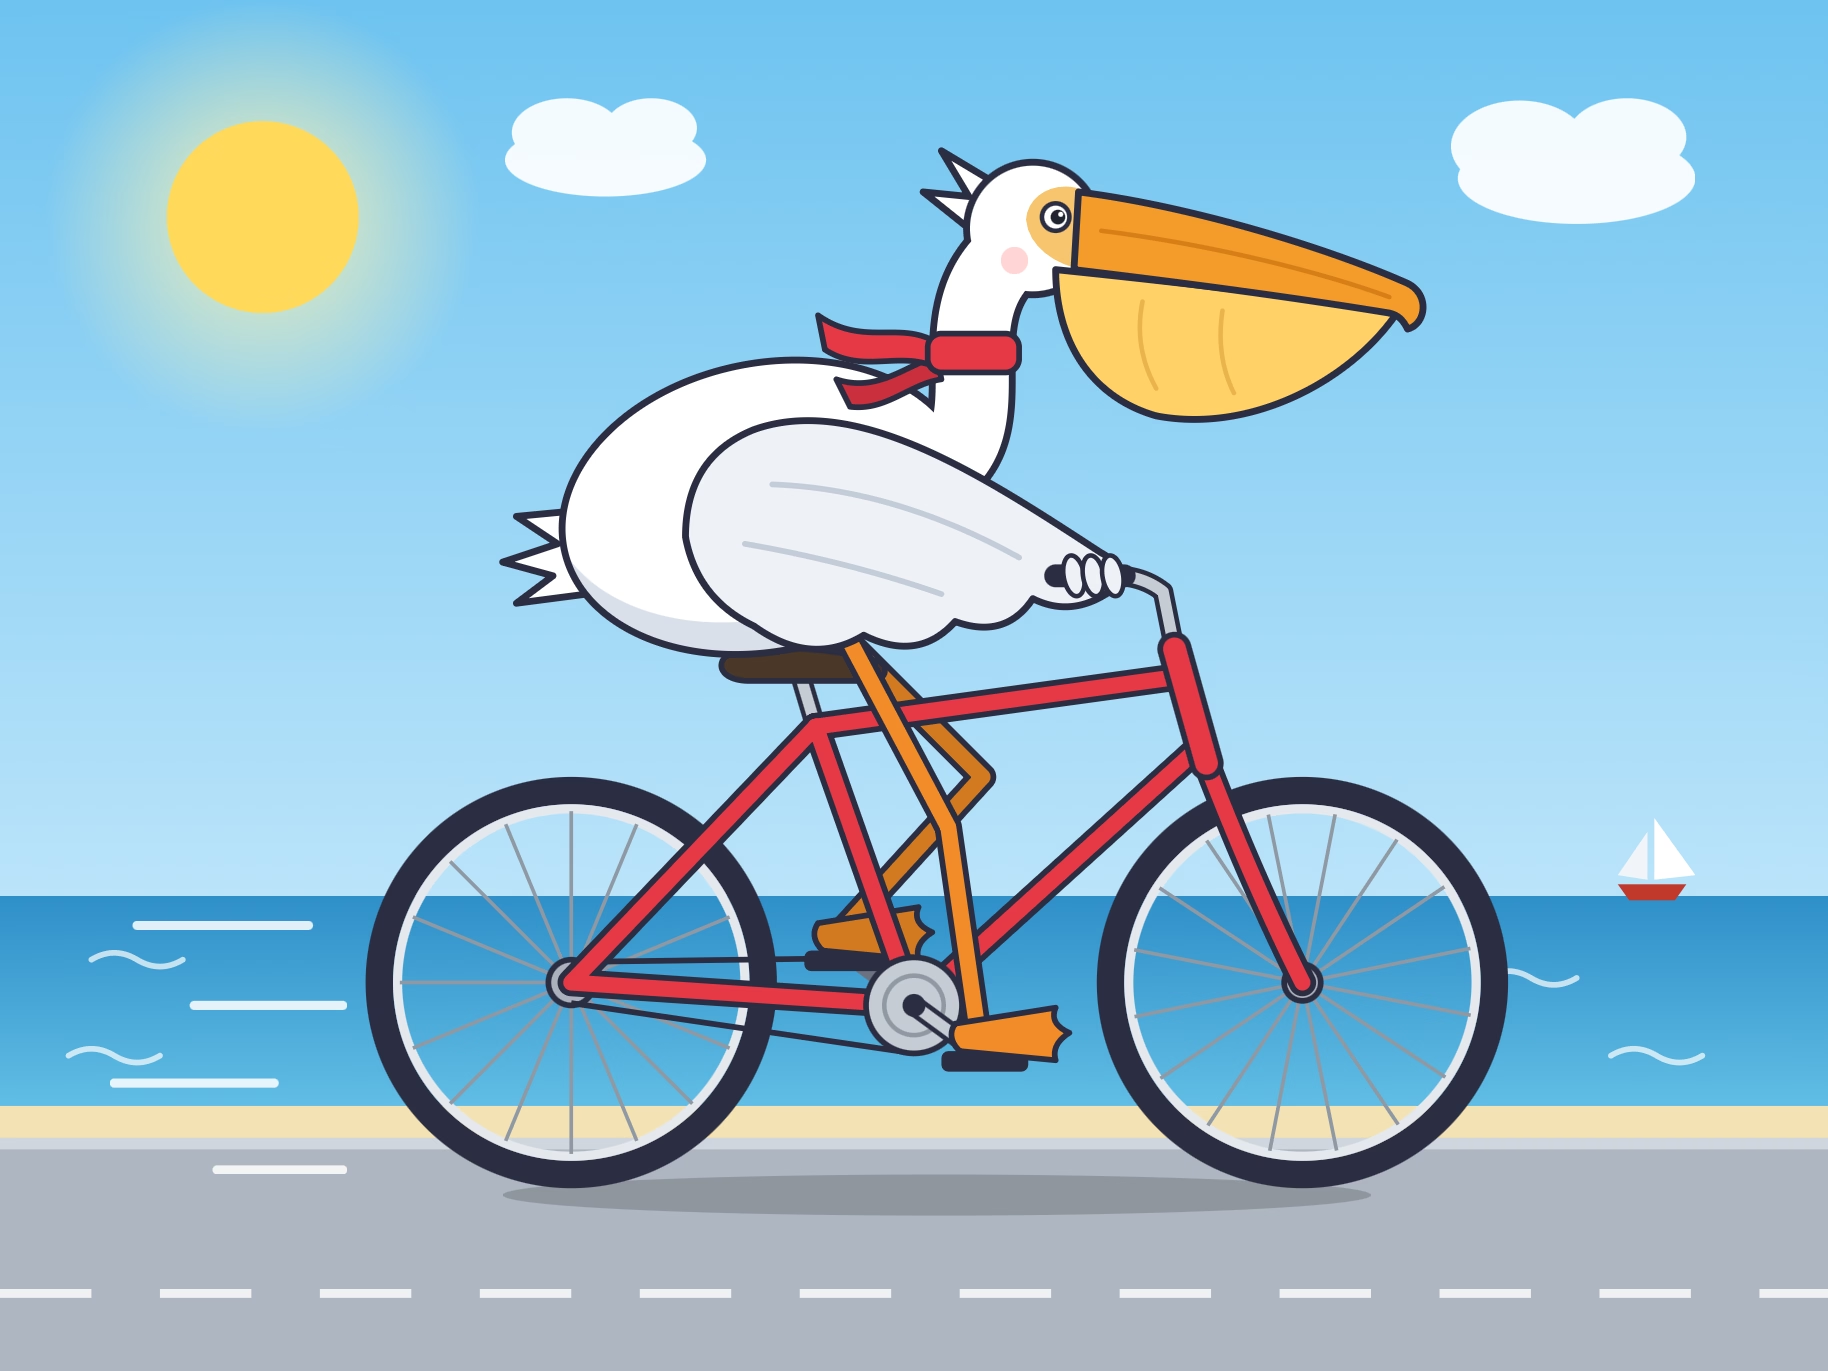
max failed to return an image at all, running out of tokens after spending 128,000 thinking about them. That's the same bug that I saw with Opus 5.5 - but it's new for the Fable series, both Fable 5 and Fable 5.1 returned max effort pelicans just fine.
It's priced at $8/million input and $40/million output, which is a 20% discount on the previous Fable 5.1 ($10/$50).
I also used Fable 5.2 to help identify the source of a mysterious beep.
Locating the source of a mysterious beep with Claude
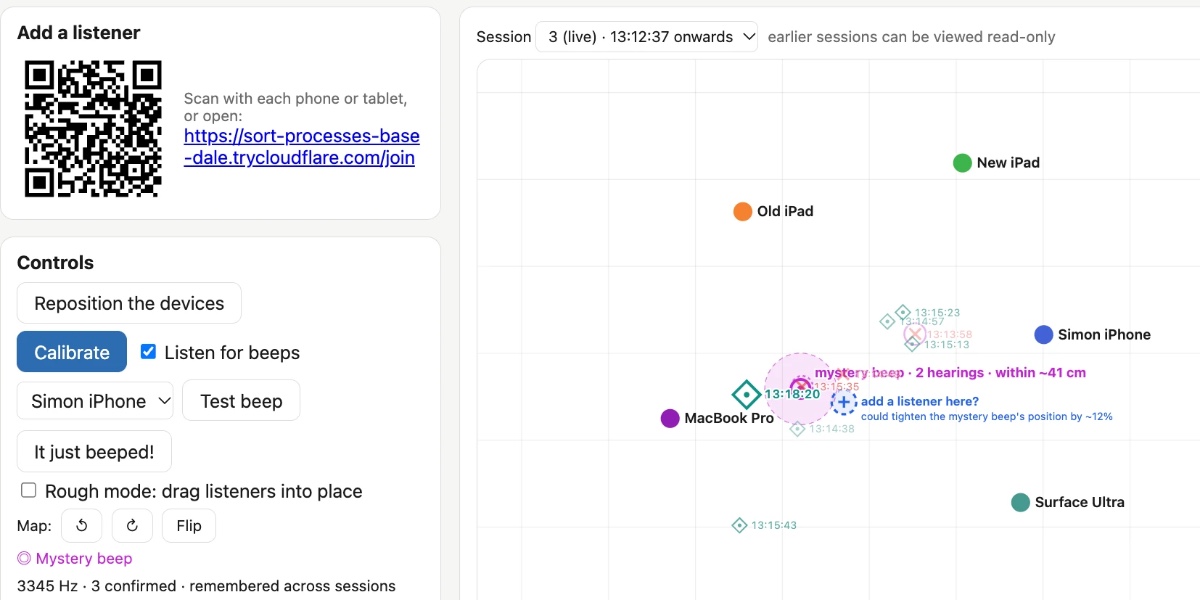
Our house has a box room, full of boxes that we still haven’t unpacked from our last move. A couple of weeks ago something in that room started intermittently beeping. The beeps were far enough apart that standing in the room and trying to determine the source of the noise was frustrating, and I really didn’t want to dig through every one of those boxes. So I had Claude Code build Beep Locator, a software system for triangulating the source of a mysterious beep using multiple devices scattered around the room.
[... 2,039 words]Hide your slop PR descriptions behind <details><summary>
Most of the changes I make to my projects these days come in the form of PRs opened for me by Claude Code or Codex. The PR is my unit of work—I use them to bundle commits together, iterating on them until a feature is complete, document decisions and then merge the finished result. Today’s coding agents are great at writing PR descriptions.
[... 987 words]Qwen 3.8 27B on my laptop can interpret model weights, too
Yesterday’s hot paper was Sparks of Weight-Space Programming: LLMs can natively read & write neural network weights by Rikiya Takehi, Jayden Teoh, Alex Zhang, and Omar Khattab. The paper (OK, the authors classify is as a “blog post”, but it’s paper-shaped) found that frontier models, in particular GPT-6 Astra, can both interpret and modify the raw weights of a machine learning model—literally a text description of the model containing a bunch of floating point numbers. I’ve been playing with one of the examples from the paper and I’m delighted to share that Qwen 3.8 27B running on my laptop can do this as well!
[... 1,211 words]There's a lot of stuff in this new release of my LLM CLI tool and Python library, representing around two months of accumulated features and fixes.
I added gpt-6.1-sol and gpt-6.1-terra, plus a new llm openai endpoint add command to make it easier to configure additional models that use OpenAI-compatible endpoints.
I switched the default model (if you have not set your own default) to gpt-6-luna - half the price of the previous default, gpt-5.6-luna.
LLM's support for embeddings now accepts that different binary content may have different content-type - necessary for models like Gemini Embedding 2, which can embed text, audio, images, and video.
A lot of open source maintainers complain about a flood of AI-assisted PRs. LLM is my project that has been most affected by this and, to be honest, I'm not finding it to be a problem. That's mainly because I have Opus 5.5 or GPT-6 Astra help me with triage to spot the most useful fixes!
This release includes fixes from 12 authors - almost all AI-assisted - and the burden of reviewing them wasn't nearly as great as I expected. I really see them as bug reports with attached examples - sometimes I land them, sometimes I implement my own fix.
So thanks to 0d00ciallo0721, ac1982, Allen Flux, Bian Yuhan, Bishop Kammeraad, Chen Yufeiyang, Christopher Krah, Ethan Stoner, Jiachen Xie, Olamide Faniyan, Sharat Chandra Sai Boddu, nosmile99 for helping out with (or spending tokens on) this release!
The U.S. Census Bureau and “Super Intelligence”
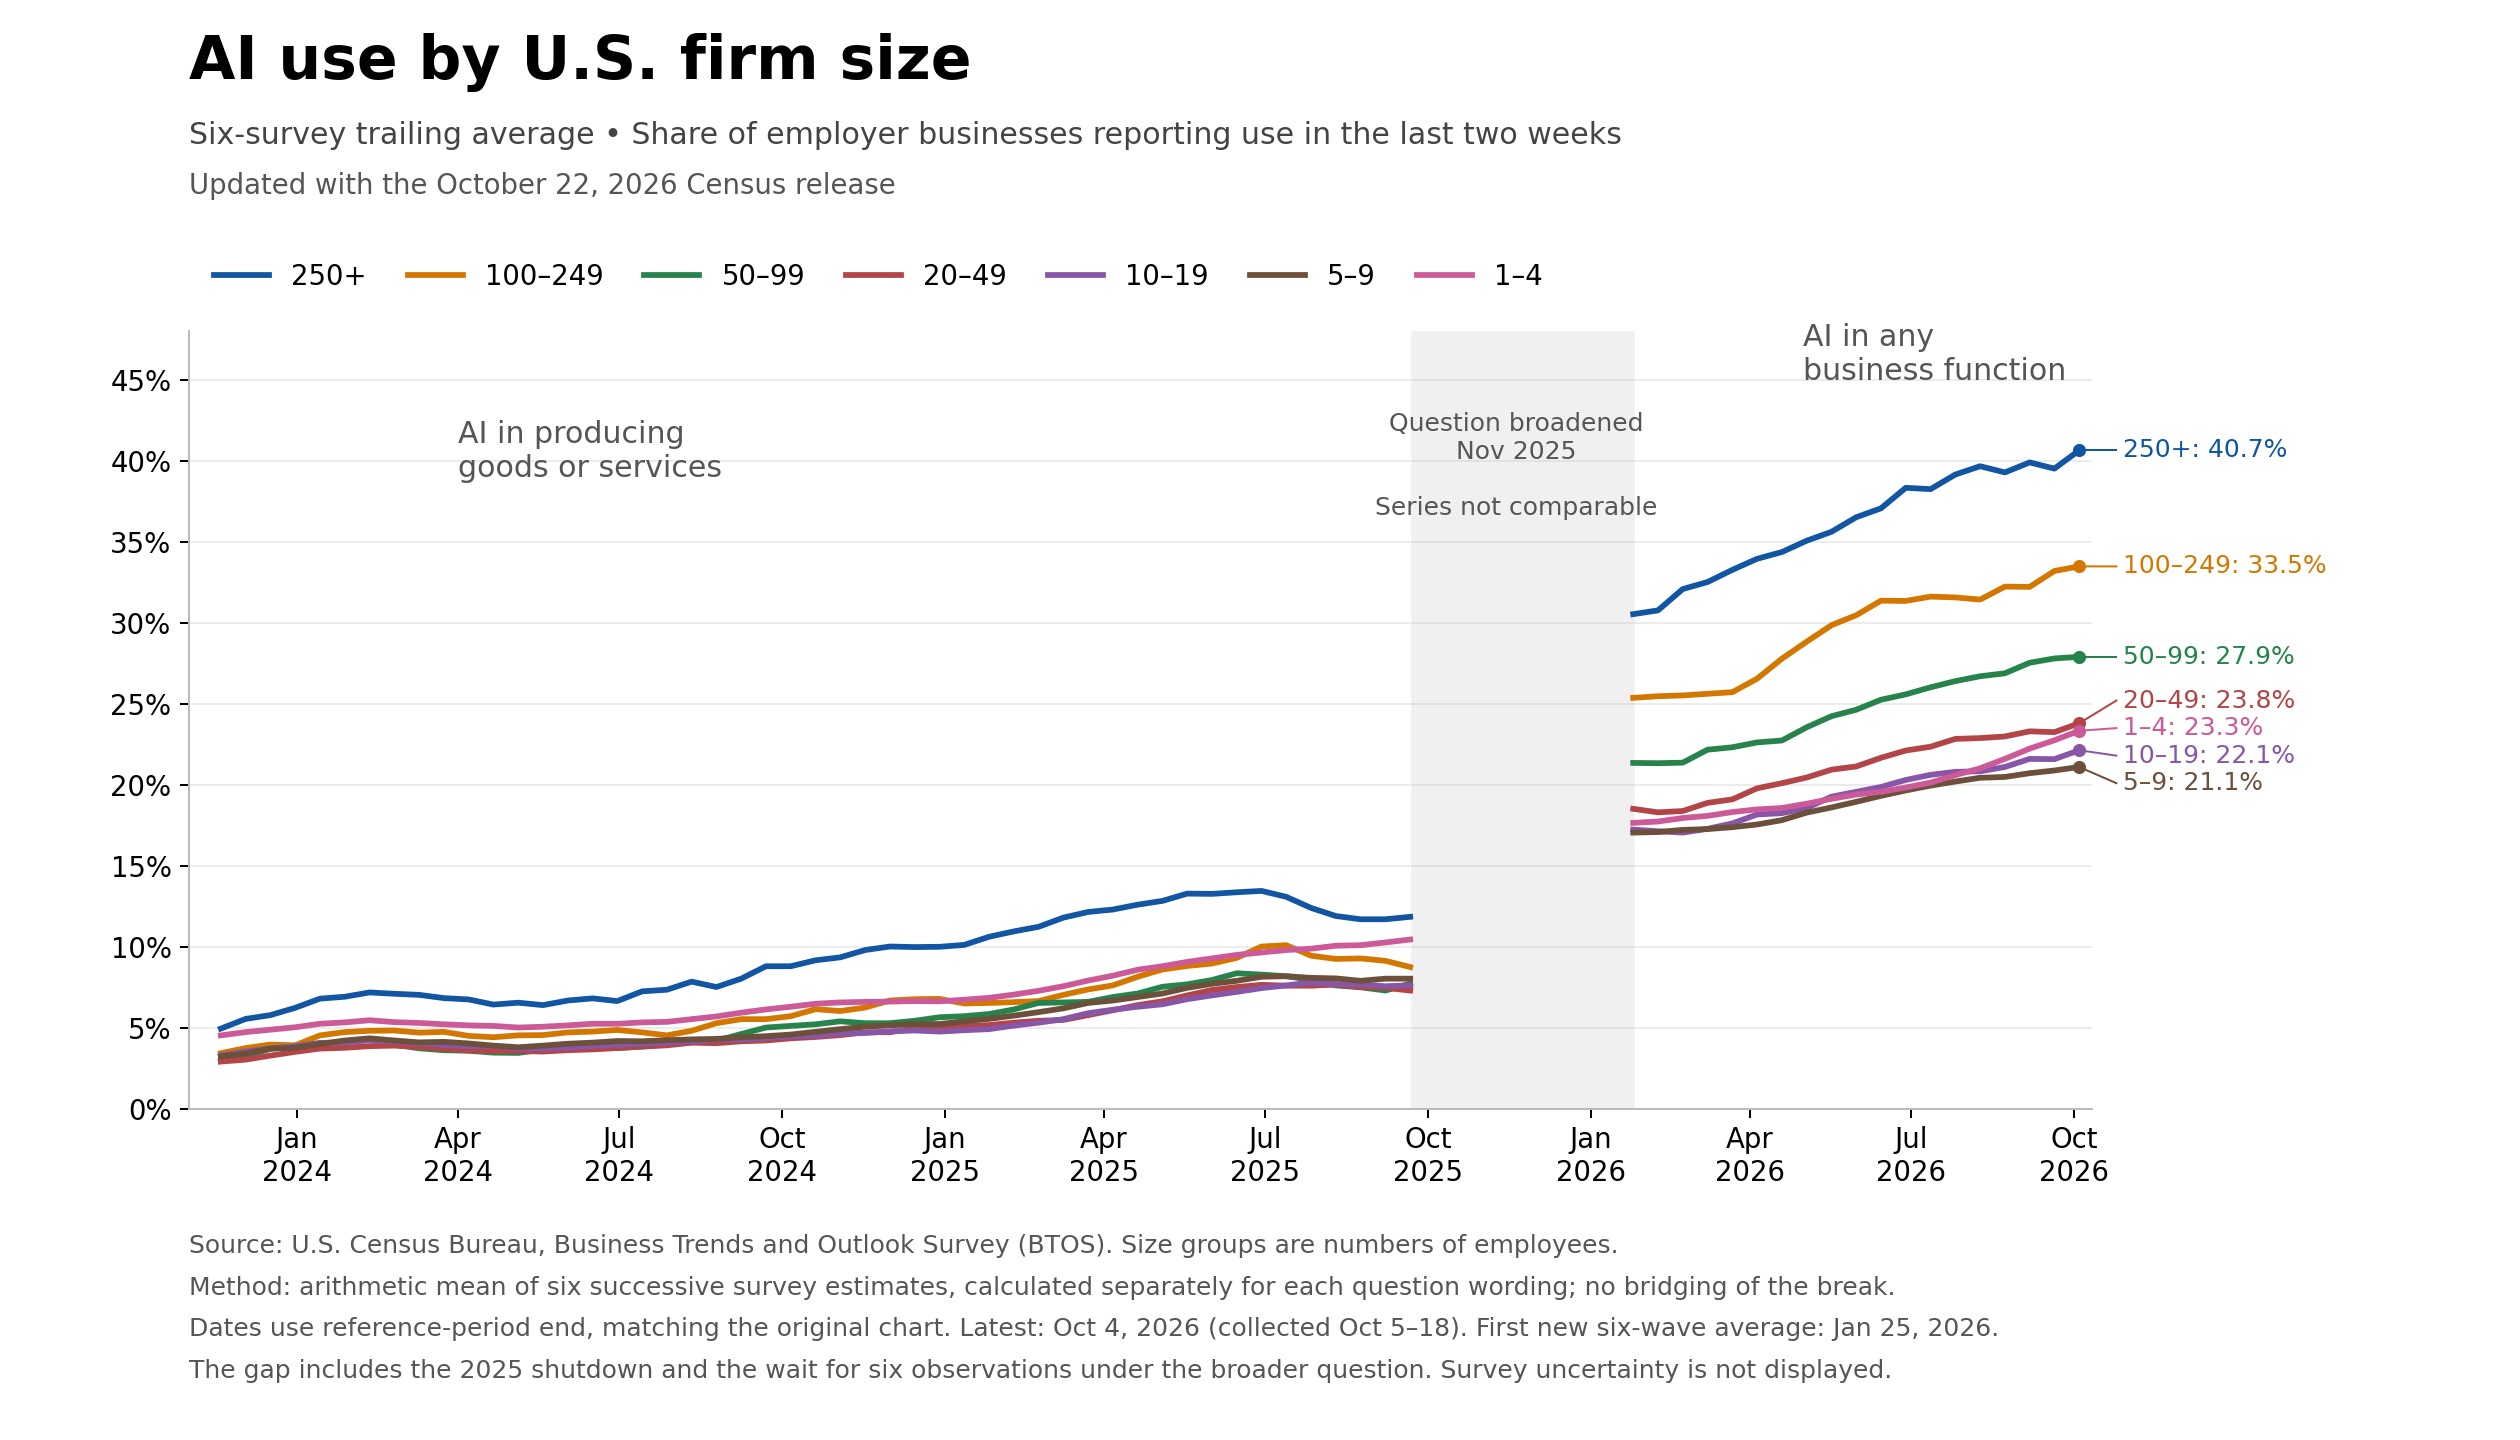
I was reminded today of AI Adoption Rate Trending Down for Large Companies, a chart produced by Apollo Global Management in September 2025, which appeared to show a slowdown in U.S. corporate AI adoption based on numbers collected by the U.S. Census Bureau. At the time I used that chart to demonstrate GPT-5 data analysis, and then to experiment with Claude’s new Code Interpreter. I decided to try running those numbers again to see what had changed over the past year, and in doing so learned that the Bureau has fallen foul of Executive Order 14434, aka the asinine Super Intelligence one.
[... 1,068 words]More broadly, the use of LLMs erodes trust in documentation, in software, and in the organizations which produce them. Perhaps engineers will begin to treat any new software project with suspicion—the signals we used to rely on as markers of a mature system are now easier to counterfeit. [...]
In the age of LLMs, what can maintainers do to ensure correct software and accurate documentation? Having done that work, how can they demonstrate its quality to users?
— Kyle Kingsbury, Jepsen results for ParticleDB 1.1.4
dbreunig/nesformer (via) Inspired by qwenputer by Divyansh Agrawal, Drew Breunig baked a working emulator for a Nintendo Entertainment System 6502 CPU into the weights of Qwen3.5-4B. You can now play NES ROMs such as Super Mario Bros (very slowly) running inside Qwen!
In a comment on Hacker News Drew reveals the Opus 5.5 prompts he used to build this system:
Read this article and any relevant source code: https://divagr.com/blog/qwenputer. Then explore if you could emulate the chip and ram in a Nintendo Entertainment System (as people do today with FPGAs in MISTRs) using this technique. If so, what size model would you have to build and if you could use smaller faster ones, could you get it to be at the standard clockspeed.
Followed by:
I think we should build it! Just for fun. It's okay if it's not fast. We want to be able to have the weights, and a cli to run them that we can point at a ROM.
Apparently Opus found and then used this collection of conformance tests for the NES CPU released 15 years ago by Christopher Pow.
API credits benefit for eligible ChatGPT subscriptions. Earlier this month Anthropic announced a generous new benefit for their Max and Team subscriptions: $100, $200, and $500 per month subscribers would get the equivalent quantity of (expiring) credits to use with the Anthropic API.
OpenAI have now launched pretty much exactly the same deal: if you have a $100, $200, or $500 subscription plan with them you now get that same quantity of credits to apply to one of your API organizations.
I maintain subscriptions with both companies, so this is great news for me! I may even ship some public-facing demos now that the credits are already covered by my existing subscriptions.
How I Built the Most AI-Pilled Company in the World. Don't be put off by the clickbait headline, this piece by Jacob Sansbury describing how they are building Spawn is a fascinating exploration of the bleeding edge of what's possible with agentic engineering against frontier models.
Spawn is a massively multiplayer gaming environment where players can use prompts (to the in-game agent, Savi) to modify the game world.
I fired it up on my phone for a few minutes and was able to prompt a castle into existence, then a dragon, then ride the dragon to fly around that castle.
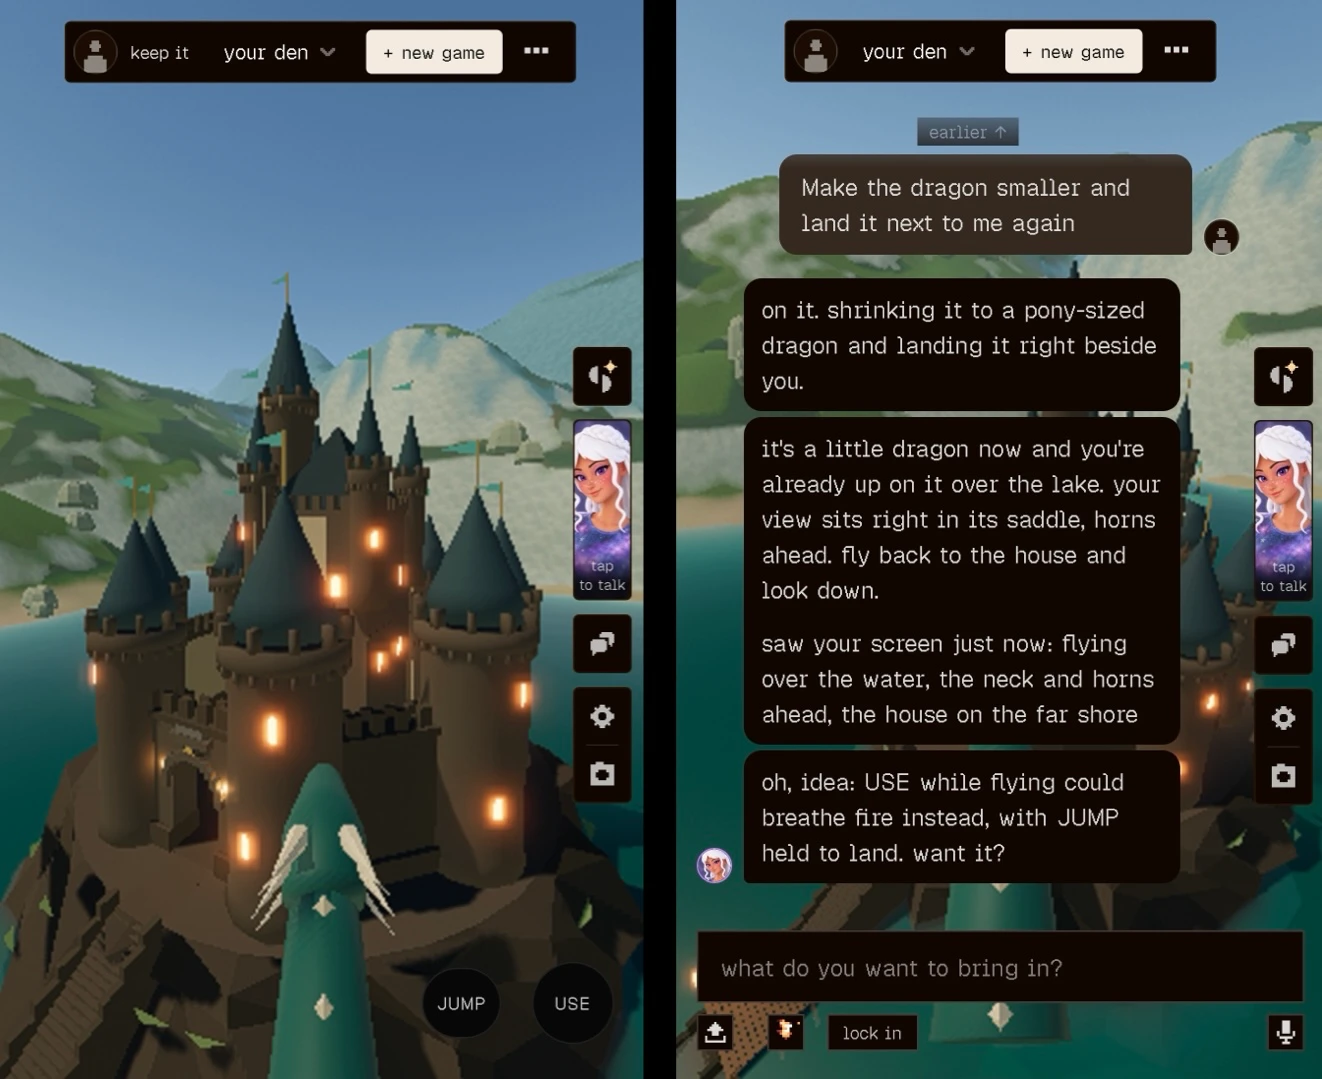
By Jacob's telling, Spawn is now being developed autonomously by a swarm of Fable-powered agents costing over $3 million in tokens per month ("we spend 30x payroll on AI tokens").
Our agents change the live code directly and ship to production hourly, so they read every error, bug report and metric themselves. About 60% of our work starts from a production error, a Savi bug report (Savi is the AI you build games with in Spawn), something odd in our logs, or a feature request.
Savi files bugs herself. When a user hits one, or Savi hits one in the product, she files it. It goes straight to an agent that decides whether it's a real bug to fix, something we won't fix, or intentional design that needs a decision. Usually it becomes a change, delivered to that user within an hour, with a message in the same chat.
This is continuous deployment turned up to 11:
A loop this tight only works if it never stops, so we treat an hour without a ship as a SEV-0, our most severe kind of incident. Unshipped changes pile up, and every problem already in production lasts longer. The feedback slows down too. An agent can only keep a few hours of work in its head, so shipping faster than that actually helps it stay coherent. [...]
We can roll back a broken change in 30 seconds, exactly where it's broken and nowhere else. When a monitor or a log alert fires, it starts or wakes an agent that owns the incident, and we break things on purpose to test that those recovery paths work.
My eyebrows raised at least a dozen times reading this. I have trouble imagining this style of development working on software with higher stakes for when something goes wrong, but for a game this appears to be working surprisingly well.
Jacob says that Fable 5 (and then 5.1) was the model that made this level of autonomy possible. Opus 5.5 doesn't quite hack it for them, and when they tried GPT-6 Astra to apply fixes from a security review everything stopped working:
Every feature had been disabled and marked to be turned on again once the security fixes were done. Astra had gone through our whole product and made the insecure things secure by turning them off.
These kinds of extreme experiments are why I'm excited about game development as a substrate for exploring the edges of what today's coding agents can do.
In general, LLM performance is incredibly multidimensional. There's no guarantee of a fixed ordering where the model that is best at math is also the model that's best at jokes. Despite that complexity, much of the variation in performance is explained by just a single variable: model size. In general, models that are bigger will (a) be more performant / reliable, (b) cost more per token, and (c) have better recall of esoteric facts. As you note, our models are ordered:
Luna < Terra < Sol < Astra
[...] These days, version number signifies a few things at once: the order of release, the relationship to other releases, and the magnitude of improvement. So something like 6.1 would indicate it was launched after 5.6, may share some similarities to other 6.1 models in terms of training data / personality (which is why it's not 5.7), and isn't a giant enough leap to merit the headlines and expectations that would come with a 7.
— Ted Sanders, explaining OpenAI's model naming conventions
GitHub Octoverse 2026. I'm at GitHub Universe today (GitHub gave me a free ticket through their "GitHub Stars" program). EVP Jay Parikh just announced this year's Octoverse report, and highlighted these numbers in particular:
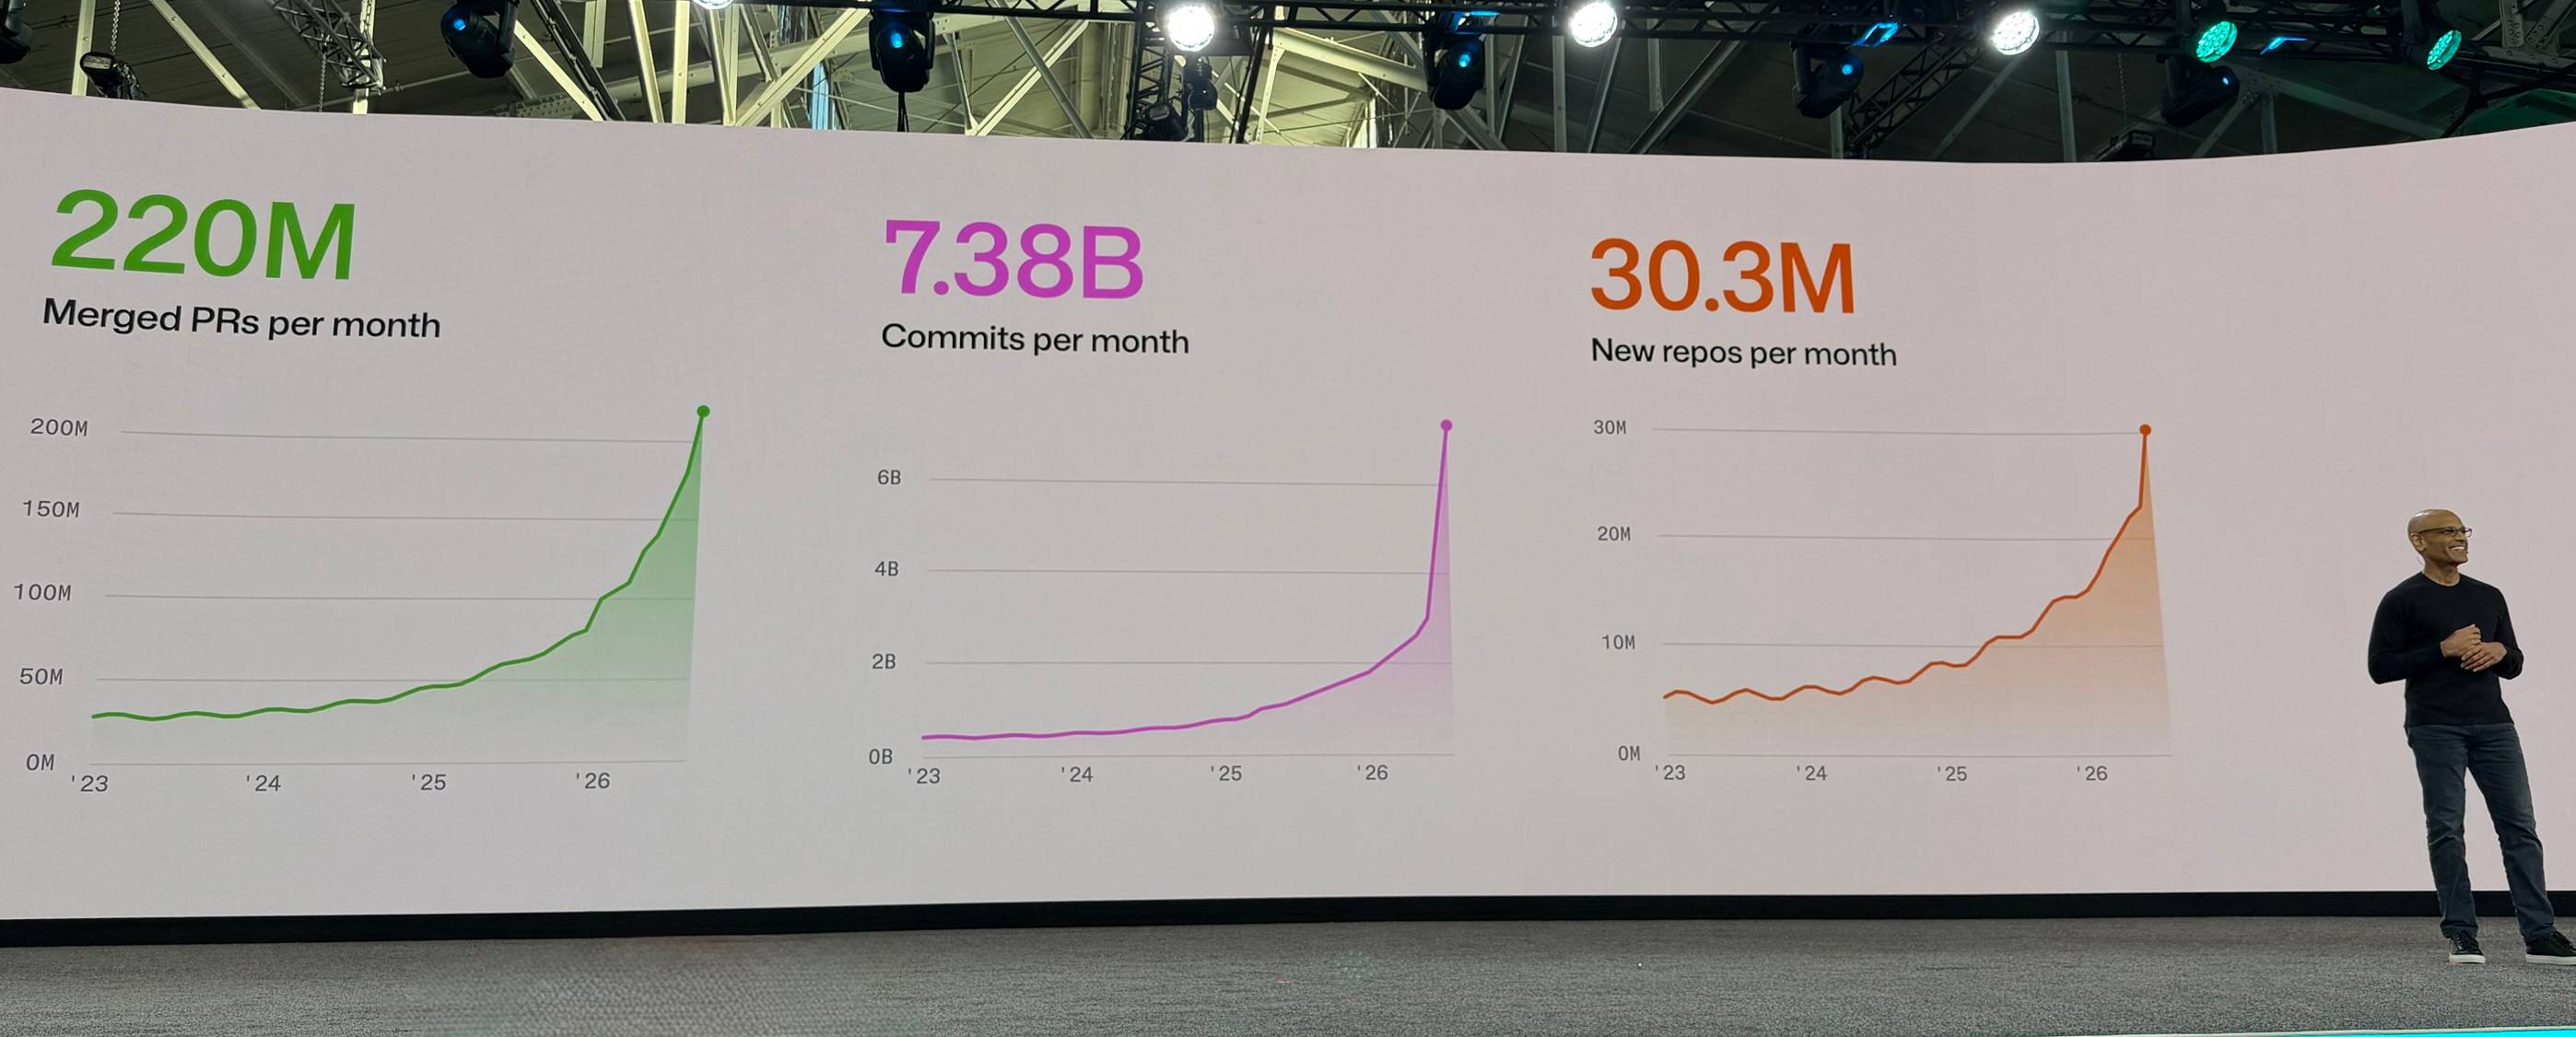
This is a pretty stark representation of the impact of agentic engineering on GitHub. In 2026, merged pull requests tripled in less than a year to 220 million per month. Commits more than tripled to 7.38 billion per month, with most of that increase in the second half of this year. New repository rate doubled this year, to 30.3 million per month.
The report includes new numbers by industry, and breaks out numbers for repositories that involve "interoperability or reverse engineering". The methodology section includes notes about how they did this:
Top countries by pushes to public repositories, adjusted by profile location. Pushes from each country were summed across the Octoverse year. To adjust for biases caused by VPN usage, LLM classification was used to extract the ISO 3166-1 alpha-2 code from the profiles of GitHub users who contributed pushes during this period [...]
Industry. Public repositories created 2022 to 2026 were sorted into NAICS sectors by a fine-tuned multilingual embedding model using name, description, topics, and README, from random samples per year. [...]
Interoperability. Counts public repositories created each year whose name, description, topics, or README mention interoperability or reverse engineering, or related terms, such as clean room implementation, drop-in replacement, or protocol re-implementation.
The October inflection point for vibe game development
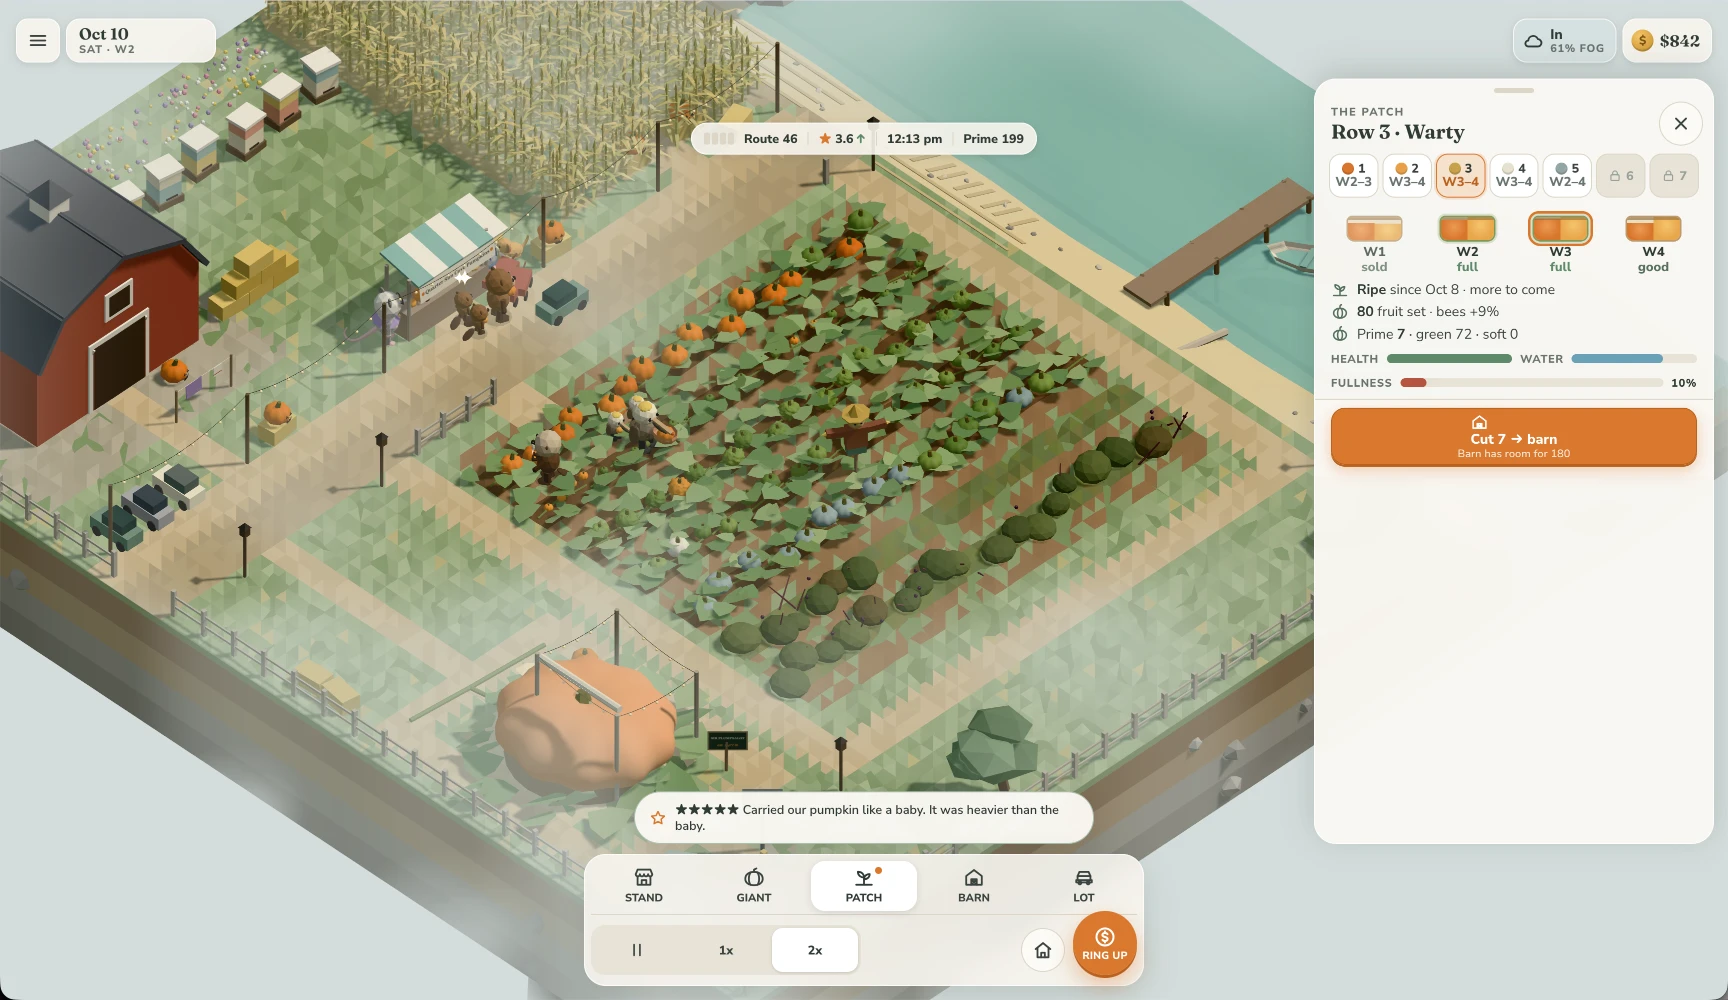
I’ve written before about how November 2025 was an inflection point for coding agents—the point where Opus 4.5 and GPT-5.1 crossed a tipping point that meant their respective coding agents became reliable daily drivers for software engineers. I think we’ve reached a new inflection point in October 2026, and this time it’s for vibe coding computer games.
[... 3,254 words]If your work does not benefit from current AI tooling, that is a finding, not a failing. Document why, share it with your community of peers, bring it to your manager, and work to find solutions. An engineer who can explain where AI does not yet help their work is demonstrating the judgement we are asking for.
— Terk Terkowitz, An update from Amazon engineering leadership on the role of the developer in the age of AI
Game Boy Color on My Conference Badge. I'm at GitHub Universe this week and, similar to last year, the conference badge is a full-blown color screen computer.
I've been hacking around with it again, and then I ran into with Steve Francia... who worked with Gemini to get a full NES emulator working on it, and then went a step further and deployed an emulator for both the Game Boy and the Game Boy Color.
Which means, if you can obtain the ROM, you can run The Legend of Zelda: Link's Awakening on your conference badge!
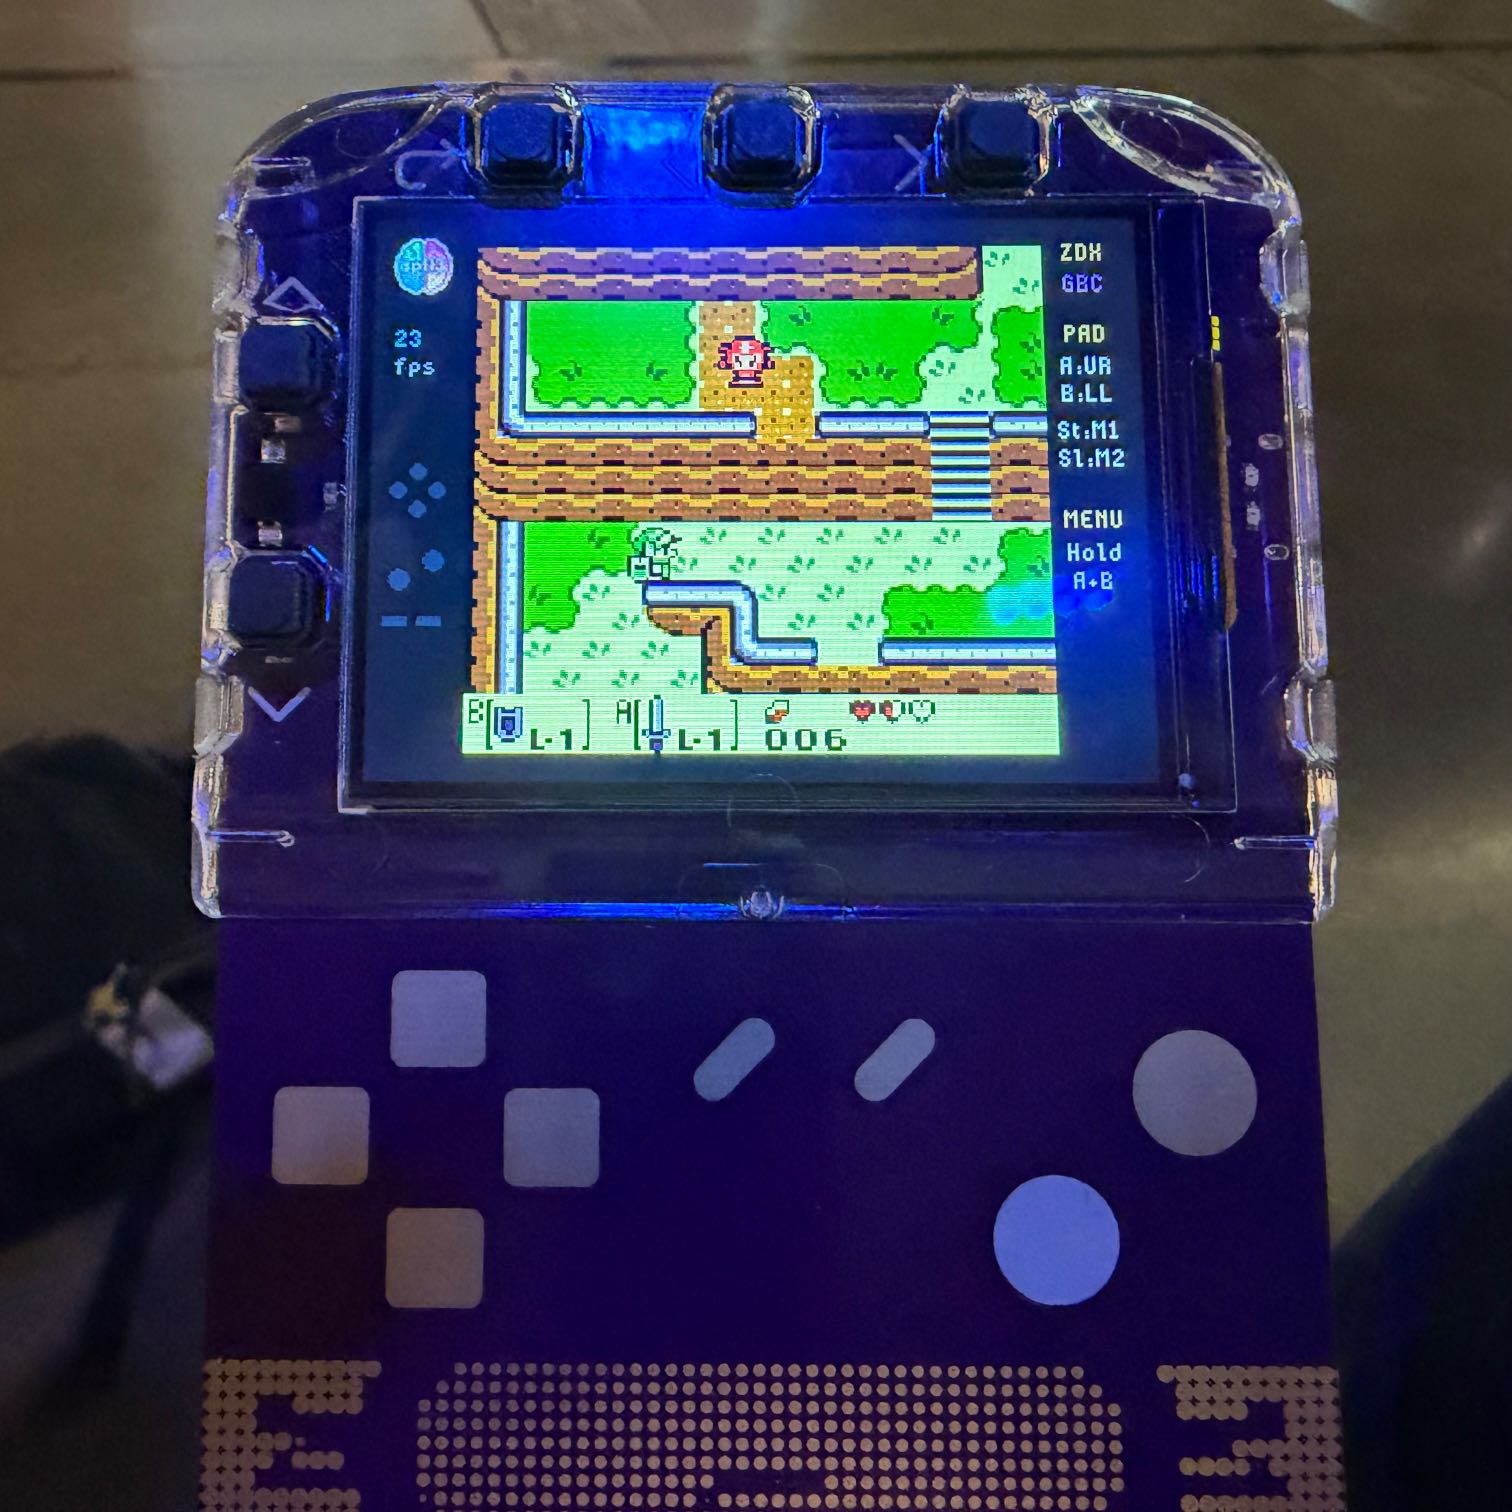
A neat feature of the badge is that you can turn it upside down and then use game controller touch buttons that are built into the badge body.
GPT-6.1 Terra (via) It's always interesting to note which aspects of a new model are emphasized in the release announcement.
In the case of GPT-6.1 Terra, OpenAI went with visual reasoning and computer use:
We’re introducing GPT-6.1 Terra, a fast, efficient model that combines detailed visual reasoning and precise computer use alongside clearer, more natural writing. A significant step up from GPT‑5.6 Terra, it excels at the communication and computer-based tasks that fill the workday, from drafting proposals and interpreting technical drawings to filling out forms and editing videos.
Terra sits in the same position as Sonnet in the Anthropic model collection - not the cheapest or the most expensive, making it harder to decide when to use it.
Computer use is a good example of a task that benefits from a less expensive model, since you might put it to work on automated, repetitive tasks.
OpenAI's Ted Sanders provided some useful advice in a comment on Hacker News:
In the case of GPT-6.1 Terra, I'd say Terra is probably better than Astra and Sol at technical communication, similar on vision and computer use (but much faster!), and a bit worse on most other things. For API developers, it's a nice midrange option if you want something cheaper than Sol but a lot smarter than Luna (especially for vision / computer use / communication). For subscribers, it's not a bombshell release - if you're hitting usage limits, maybe it helps you go a bit further, and if you want clearer communication or faster computer use, it can be a nice option to select.
Here are the pelicans for the different reasoning levels. This pelican for "max" cost 11.3161 cents and took 4 minutes and 11 seconds:
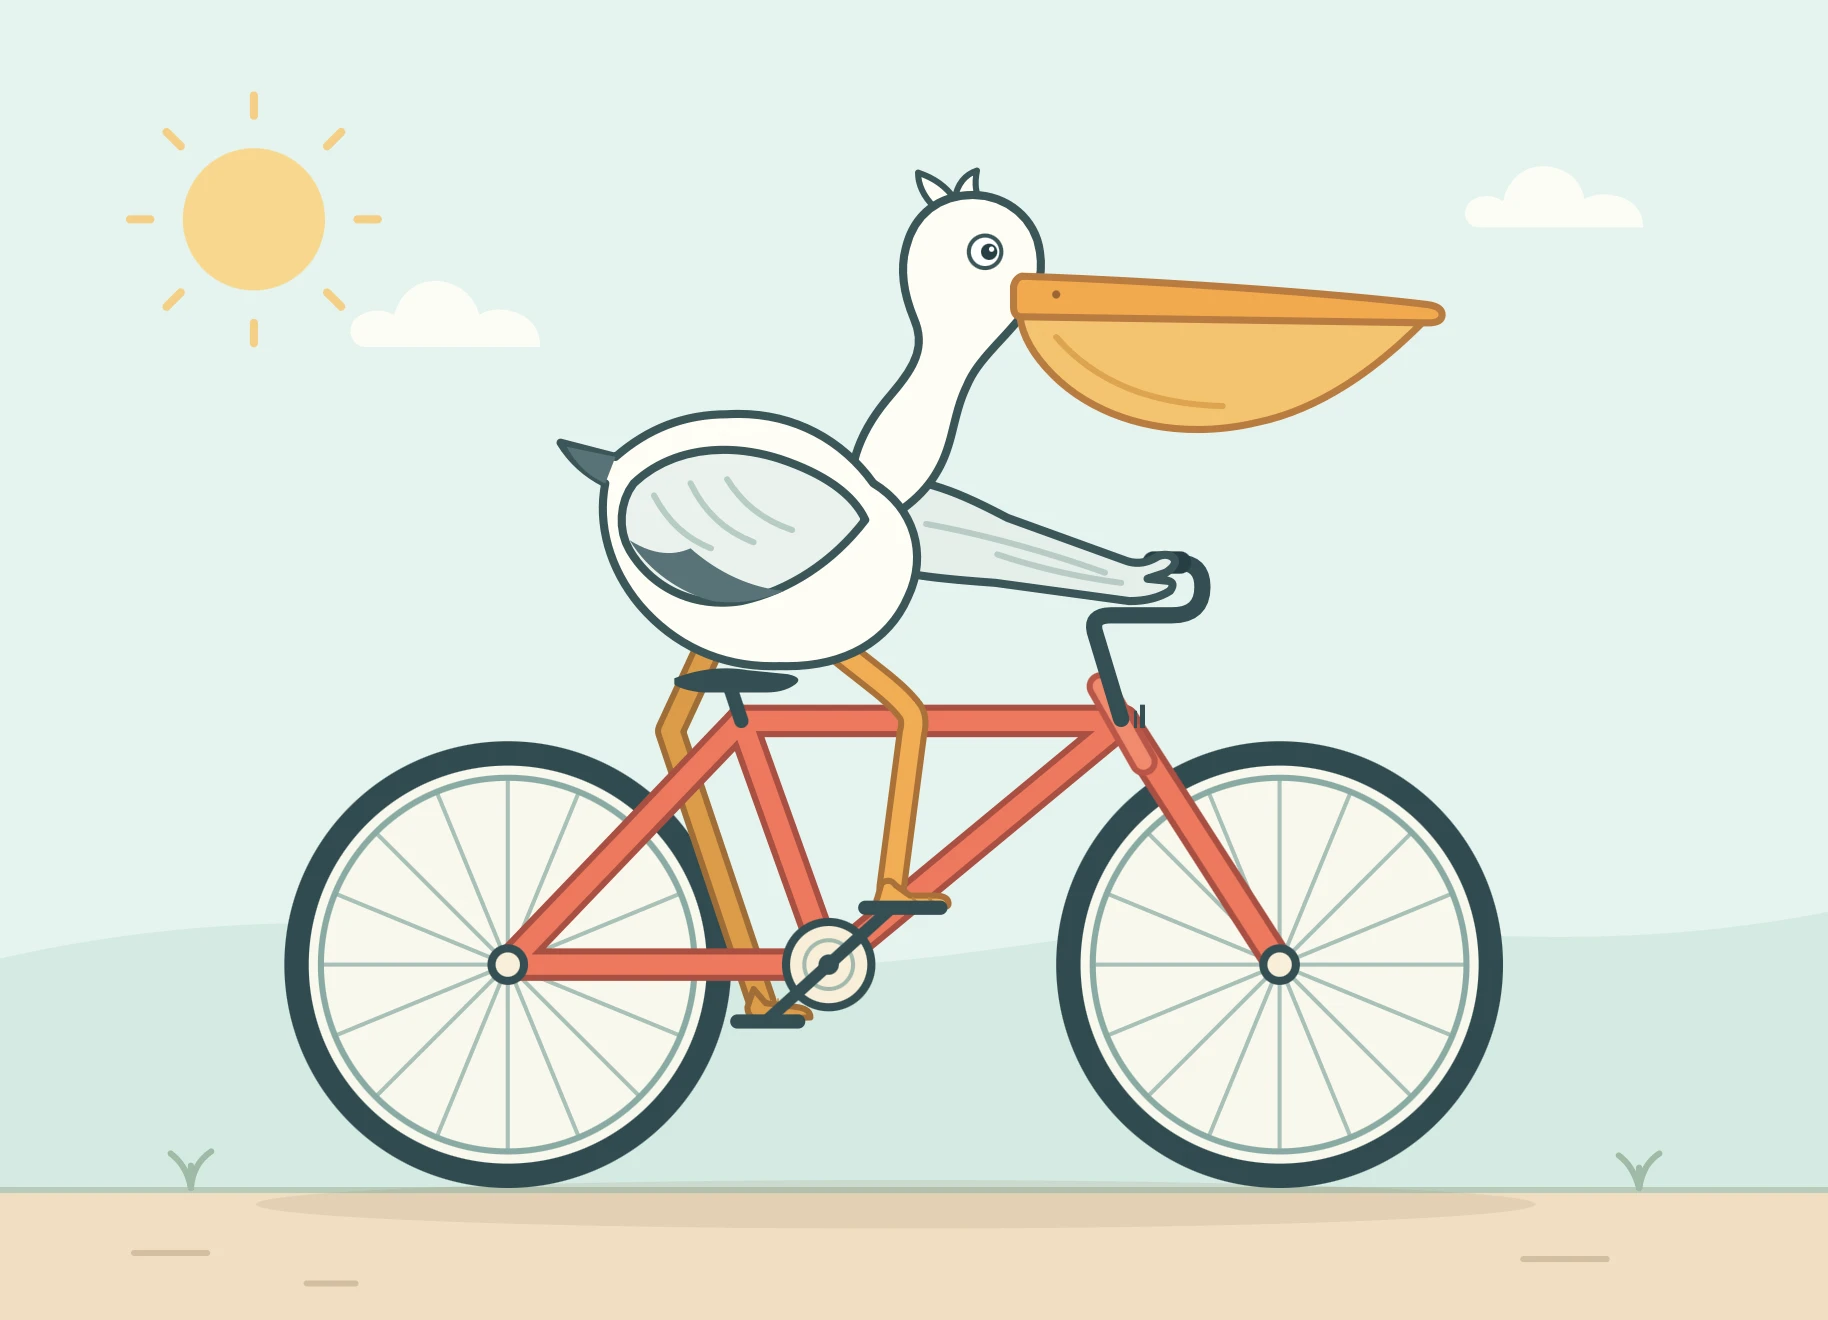
Here's a new comparison grid showing pelicans for every reasoning level of OpenAI's current frontier lineup: GPT-6 Astra, GPT-6.1 Sol, GPT-6.1 Terra, and GPT-6 Luna.
GPT-6.1 Terra is priced at $1/million input tokens and $5/million output - almost half the price of GPT-5.6 Terra and GPT-6.1 Sol, and around 10x the price of GPT-6 Luna.
Because big tech platforms essentially do not have customer support and make it impossible for their users to contact a human, many people experiencing run-of-the-mill tech problems have turned to ChatGPT. And, increasingly, ChatGPT is telling people that have normal tech support problems that they have discovered something journalistically notable and that 404 Media, specifically, can help them.
— Jason Koebler, ChatGPT Keeps Telling People 404 Media Can Solve Their Tech Support Problems
Introducing Kimi K3.1 Pro (via) Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise "Full model weights will be released by Nov 4, 2026".
They're also offering a "Highspeed" version that's 2-3x faster, at twice the price (except for input token cache hits, which are priced the same).
The US dollar pricing is $2.00/million tokens for input and $10/million for output - the same as GPT-6.1 Sol and half the price of Claude Opus 5.5.
Moonshot's own benchmarks show Kimi as approximately level with Opus 5.5 and GPT-6 Astra - beating them on a few benchmarks, coming close on others.
Artificial Analysis scored Kimi at 55 - ahead of Claude Fable 5.1, GPT-6 Astra, and Gemini 4 Argon (all at 53) and behind only Claude Opus 5.5 (58).
This is the first time a (soon-to-be) open weight model has scored this highly against the frontier.
I tried it out via the Moonshot API using the llm openai endpoint command I added to LLM 0.32 back in August:
llm openai endpoint \
  https://api.moonshot.ai/v1 \
  --key kimi \
  -m kimi-k3.1-pro \
  "Generate an SVG of a pelican riding a bicycle" \
  --responses \
  -o reasoning_effort low \
  > kimi-k3.1-pro-pelican-low.stdout.txt \
  2> kimi-k3.1-pro-pelican-low.stderr.txt
llm openai endpoint can run prompts against any OpenAI-compatible endpoint but doesn't log the results, hence the extra options to save stdout and stderr (the reasoning trace).
Here are the pelicans I got for Kimi K3.1 Pro on the three reasoning levels it supports - low, medium, and max. This is max:
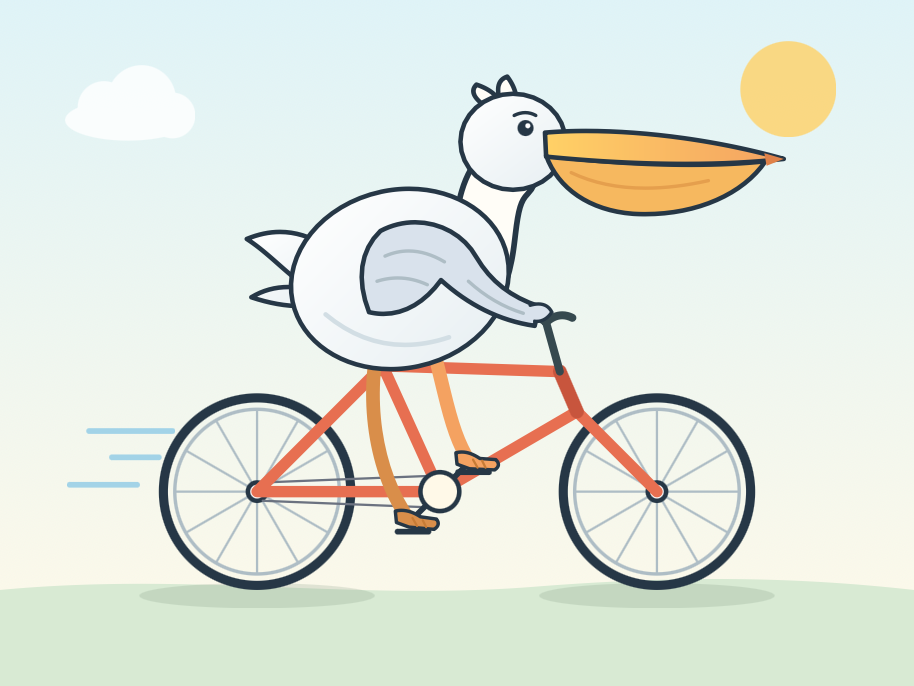
For comparison, I ran fresh pelicans against Kimi K3 on those three reasoning levels.
Donating Agent Skills to the Agentic AI Foundation. News today from Anthropic:
We’re committed to keeping Agent Skills open, community-driven, and vendor-neutral. Today, we are donating the standard to the Agentic AI Foundation (AAIF) under the Linux Foundation, which we co-founded with Block and OpenAI last year, and to which we donated the Model Context Protocol (MCP).
I'm pleased to note I called this one last December, when Anthropic first declared skills to be an "open standard":
I wouldn't be surprised to see this end up in the AAIF, recently the new home of the MCP specification.
Fun side note: since my blog content is available to Claude via the datasette-mcp
plugin I found that post by prompting Claude to "Use simonwillison.net MCP to find if I ever talked about how I want skills to be donated to a standards body".
As fun as AI is, we built so much bad software over the last 30 years, and now the universe is punishing us for our sins.
Battle Drones—a vibe coded RTS with audio-based multiplayer
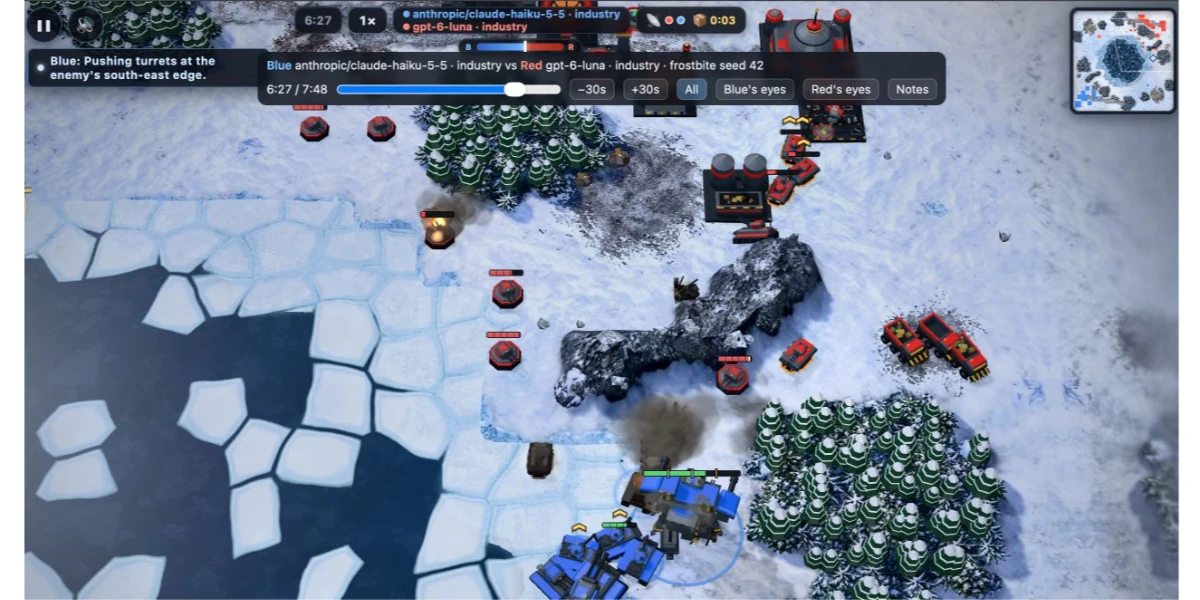
My latest vibe coded game experiment is a Command & Conquer style RTS (Real Time Strategy) game called Battle Drones (play it here). Unlike my previous experiments, this one is actually fun to play. I’m somewhat embarrassed to admit that I got there by telling Claude to “Make it a LOT more fun”. It also supports multiplayer between nearby devices using audio to synchronize game state! Here’s what I’ve built so far, and some of the things I learned along the way.
[... 4,288 words]My obituary for programming (via) Jeremy Scheff poignantly captures the key loss caused by coding agents for career programmers who enjoyed the puzzle of developing code:
Programming turned into one of the greatest jobs you could imagine. You got paid to work on tricky little logic puzzles. The trickier the puzzle, the more you got paid. But even pretty simple puzzles were worth a lot of money because regular people just couldn't do it! No, they needed us. They would give us a problem and we would solve it the way we wanted. We set the strategy, we made the timeline, we defined what was and was not possible.
If you're a programmer who thrives on building working systems and doesn't care too deeply about the problems solved along the way, LLMs are the gift that keeps on giving.
If directly solving those problems was a big part of your enjoyment, the loss is very real.
We think "did a human read the code?" is an imprecise proxy for "what could go wrong with this change, and which check—automated or human—is the right one to catch it?"
Asking that question also changed when review happens. Before, review was a gate at the end of the road: write the code, open a PR, wait for your colleague.
Now, review runs continuously, more like spellcheck while you write. Most changes have been reviewed and fixed by Claude at least once before a human is asked to look. This catches most routine mistakes, and saves team attention for higher-level questions and scrutiny.
— Addy Osmani, Morgan Westlee Lunt, and Qing Wang, How the Claude Code team does code review
This research task is really an experiment in running Claude Code for web in "Ultracode" mode, as described in Orchestrate subagents at scale with dynamic workflows in the Claude Code documentation.
With Ultracode turned on, Claude Code makes aggressive use of dynamic workflows - it generates JavaScript that defines and coordinates a network of subagents to take on complex problems.
My initial prompt was this - I meant "hit the rows directly", the word "delete" was an accidental typo on my phone:
Write a SQLite extension in Rust that implants SPARQL and runs really fast because it can hit the delete rows directly
This caused Claude Code for web to churn for over 12 hours. I checked in on its progress the next day and sent a single follow-up prompt when I noticed how many Rust crates it had built:
Every folder in the crates/ directory needs a README
Include a tutorial.md teaching users how to install the extension and how to run it in the SQLite CLI and then teaching them SPARQL in addition to how to use the SQLite extension
Include a script with the tutorial for populating a SQLite database with useful and realistic example data for that tutorial
This project feels like next-level vibe coding - it's not remotely feasible to review the code that was produced here, and even following the documentation is a significant investment in work. I'm not entirely sure what to do with this - I appear to have a full SPARQL implementation in Rust inside SQLite now, but how valuable is that if I created it on a whim and can't (or won't) invest the necessary time to understand what it can do?
Another game experiment - I wanted to see if it was feasible to have a two player game on two separate phones running in static HTML where the networking code uses chirps sent via the microphone. It seems to work!
Build a two player competitive pong like game where two players use their phones close to each other and the game state is sent via audio noises which the web microphone API can interpret - but add graphical and gameplay twists to make it a lot more fun and intertwine than pong
Claude Opus 5.5 Extra in Claude Code.
Anthropic tells investors quarterly revenue up nearly 50% to $16.8bn ahead of IPO. The phrase "told investors" appears four times in this FT article, which reports on Anthropic's day of hosting investors on Wednesday. Lots of details in here from "people with knowledge of the matter".
Key things I learned from the article:
- Q1 revenue (Jan/Feb/Mar) was "about $4.8bn"
- Q2 (Apr/May/Jun) was $11.5bn
- Q3 (Jul/Aug/Sep) was $16.8bn
- In Q3: $1.70 in revenue for every $1 spent on "computing power"
- Adjusted operating margins (excluding stock-based compensation) were 11%
This point about distillation is worth quoting in full (highlight mine):
The start-up has also clamped down on “distillation” — a controversial practice whereby rival AI labs train their models on the outputs of more advanced ones.
When rival companies “distil” their models from Anthropic’s models, that involves heavy usage and spending.
Anthropic told investors on Wednesday distillation accounted for 5 per cent to 7 per cent of revenue and that they had cut it back “materially” in the third quarter of the year, said four people with direct knowledge of the matter.
Napkin maths says that if distillation was 5% of their Q2 revenue (before they cut it back in Q3) then unnamed "other labs" spent over half a billion dollars distilling Anthropic's models in that quarter!
Also notable: Anthropic appear to no longer be leaning on "annualized run-rate revenue" (previously) in these communications to their investors.
Comment My comment on The Web Is More Than Enough, by Paul Ford — Hacker News
OK, this comment convinced me to give that a shot.
Here's a thing I made in Three.js this morning - a Nudibranch themed Faberge Egg: https://static.simonwillison.net/static/2026/Hidden-Reef-Egg... (77KB)
I just asked Claude (Opus 5.5 Medium running in regular Claude Chat) to port that to Vanilla JS, in the same thread where it had built it, and got this: https://static.simonwillison.net/static/2026/Hidden-Reef-Egg... (98KB)
They aren't identical - you can see what Claude said about that in the transcript (I don't fully understand why it differed): https://claude.ai/share/e56d163e-2793-4677-aa11-191d5058b414
But yeah, it turns out Claude Opus 5.5 is perfectly capable of 3D modeling in Vanilla JS + WebGL without Three.js.
In eyeballing the code I find the Three.js slightly easier to understand myself, but I rarely look at the code for these 3D projects so that isn't a particularly big deal.
# 9th November 2026, 4:32 am / hacker-news, javascript, ai, generative-ai, llms, claude, three-js