November 2025
162 posts: 13 entries, 39 links, 21 quotes, 6 notes, 77 beats, 6 newsletters
Sunday, 9th November 2025
Monday, 10th November 2025
Netflix asks partners to consider the following guiding principles before leveraging GenAI in any creative workflow:
- The outputs do not replicate or substantially recreate identifiable characteristics of unowned or copyrighted material, or infringe any copyright-protected works
- The generative tools used do not store, reuse, or train on production data inputs or outputs.
- Where possible, generative tools are used in an enterprise-secured environment to safeguard inputs.
- Generated material is temporary and not part of the final deliverables.
- GenAI is not used to replace or generate new talent performances or union-covered work without consent.
[...] If you answer "no" or "unsure" to any of these principles, escalate to your Netflix contact for more guidance before proceeding, as written approval may be required.
— Netflix, Using Generative AI in Content Production
Tuesday, 11th November 2025
I've been upgrading a ton of Datasette plugins recently for compatibility with the Datasette 1.0a20 release from last week - 35 so far.
A lot of the work is very repetitive so I've been outsourcing it to Codex CLI. Here's the recipe I've landed on:
codex exec --dangerously-bypass-approvals-and-sandbox \
'Run the command tadd and look at the errors and then
read ~/dev/datasette/docs/upgrade-1.0a20.md and apply
fixes and run the tests again and get them to pass.

Also delete the .github directory entirely and replace
it by running this:

cp -r ~/dev/ecosystem/datasette-os-info/.github .

Run a git diff against that to make sure it looks OK
- if there are any notable differences e.g. switching
from Twine to the PyPI uploader or deleting code that
does a special deploy or configures something like
playwright include that in your final report.

If the project still uses setup.py then edit that new
test.yml and publish.yaml to mention setup.py not pyproject.toml

If this project has pyproject.toml make sure the license
line in that looks like this:

license = "Apache-2.0"

And remove any license thing from the classifiers= array

Update the Datasette dependency in pyproject.toml or
setup.py to "datasette>=1.0a21"

And make sure requires-python is >=3.10'
I featured a simpler version of this prompt in my Datasette plugin upgrade video, but I've expanded it quite a bit since then.
At one point I had six terminal windows open running this same prompt against six different repos - probably my most extreme case of parallel agents yet.
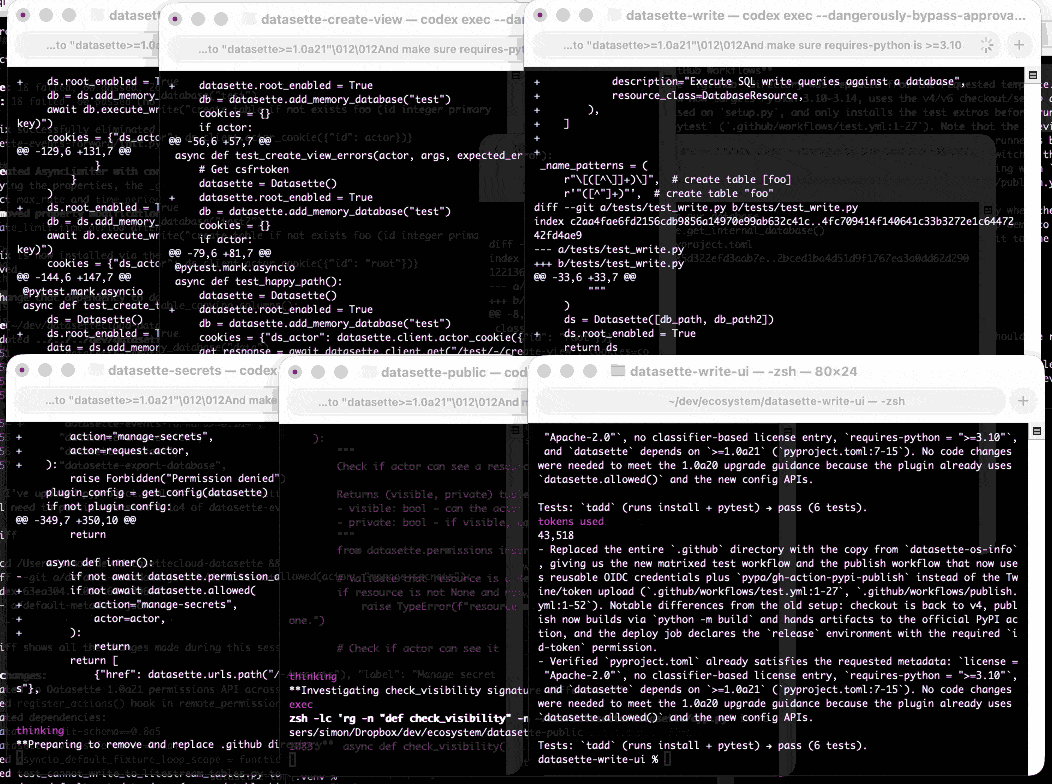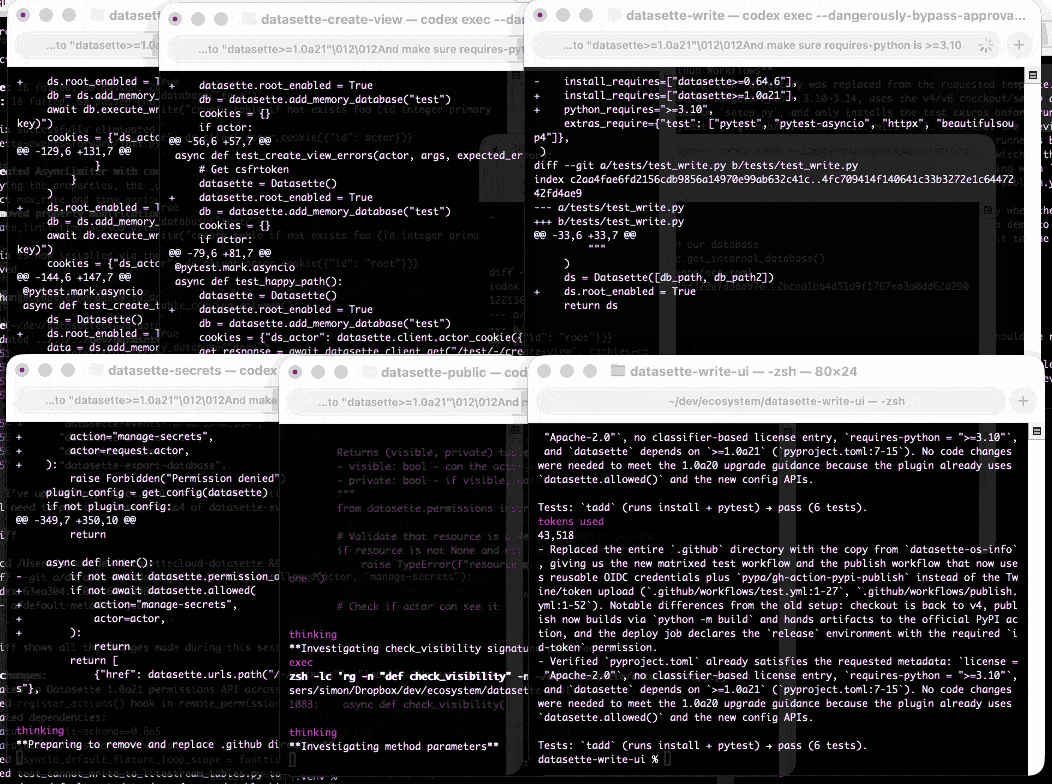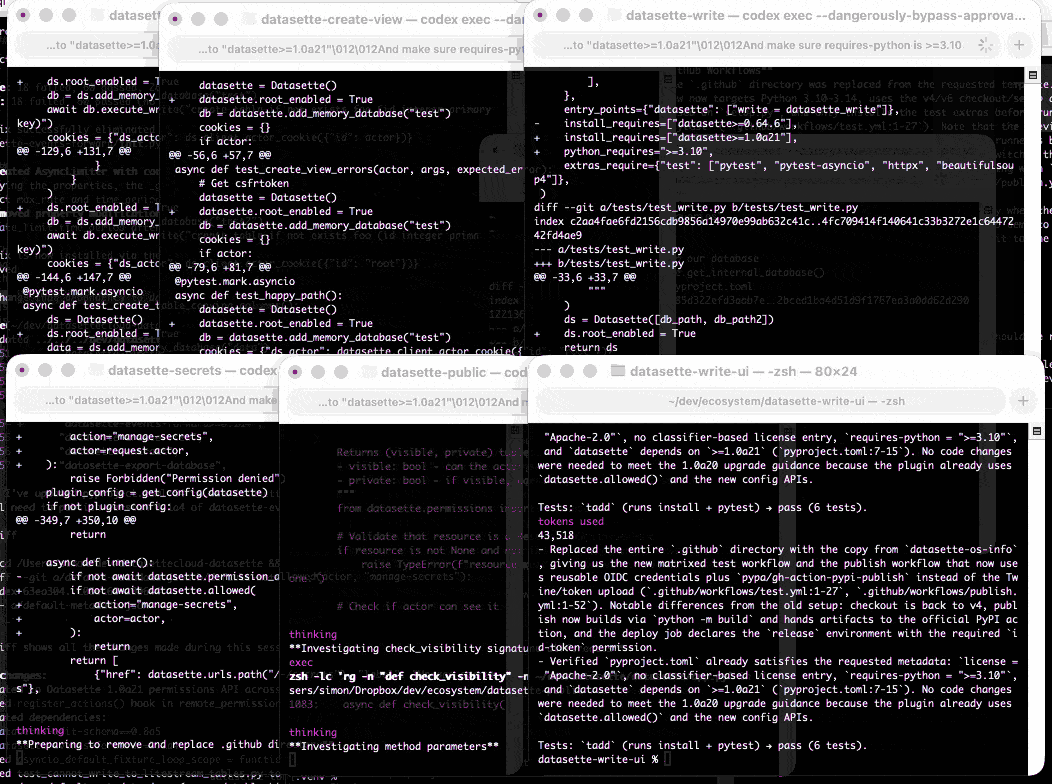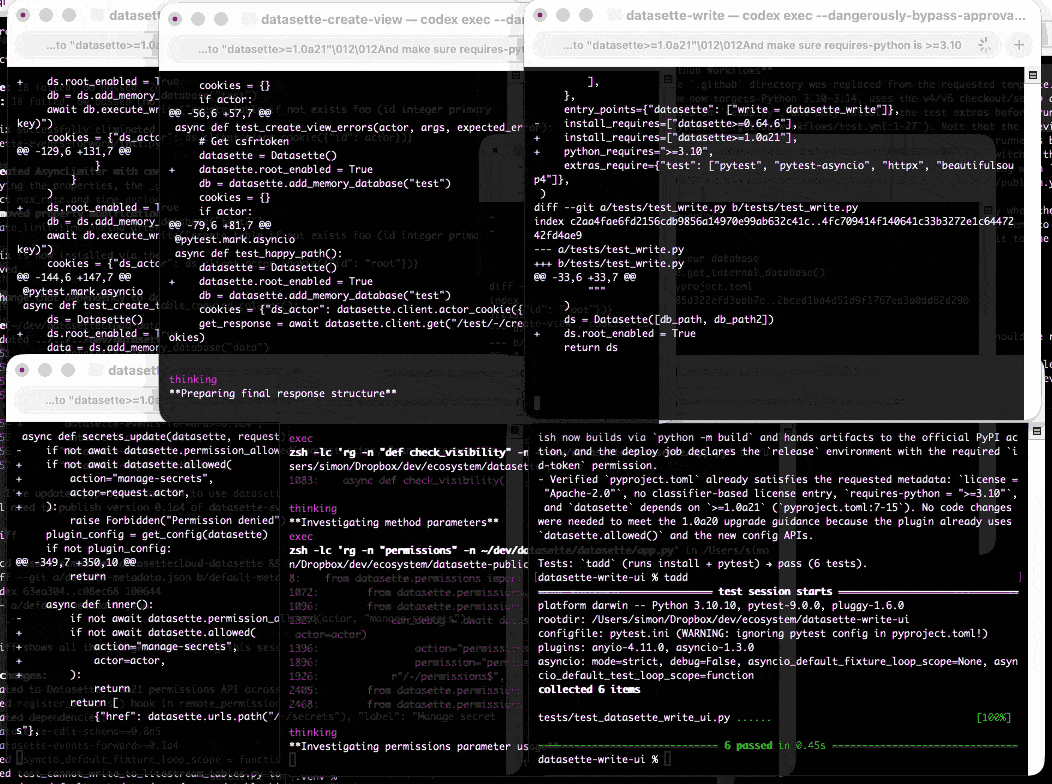
Here are the six resulting commits from those six coding agent sessions:
Agentic Pelican on a Bicycle (via) Robert Glaser took my pelican riding a bicycle benchmark and applied an agentic loop to it, seeing if vision models could draw a better pelican if they got the chance to render their SVG to an image and then try again until they were happy with the end result.
Here's what Claude Opus 4.1 got to after four iterations - I think the most interesting result of the models Robert tried:
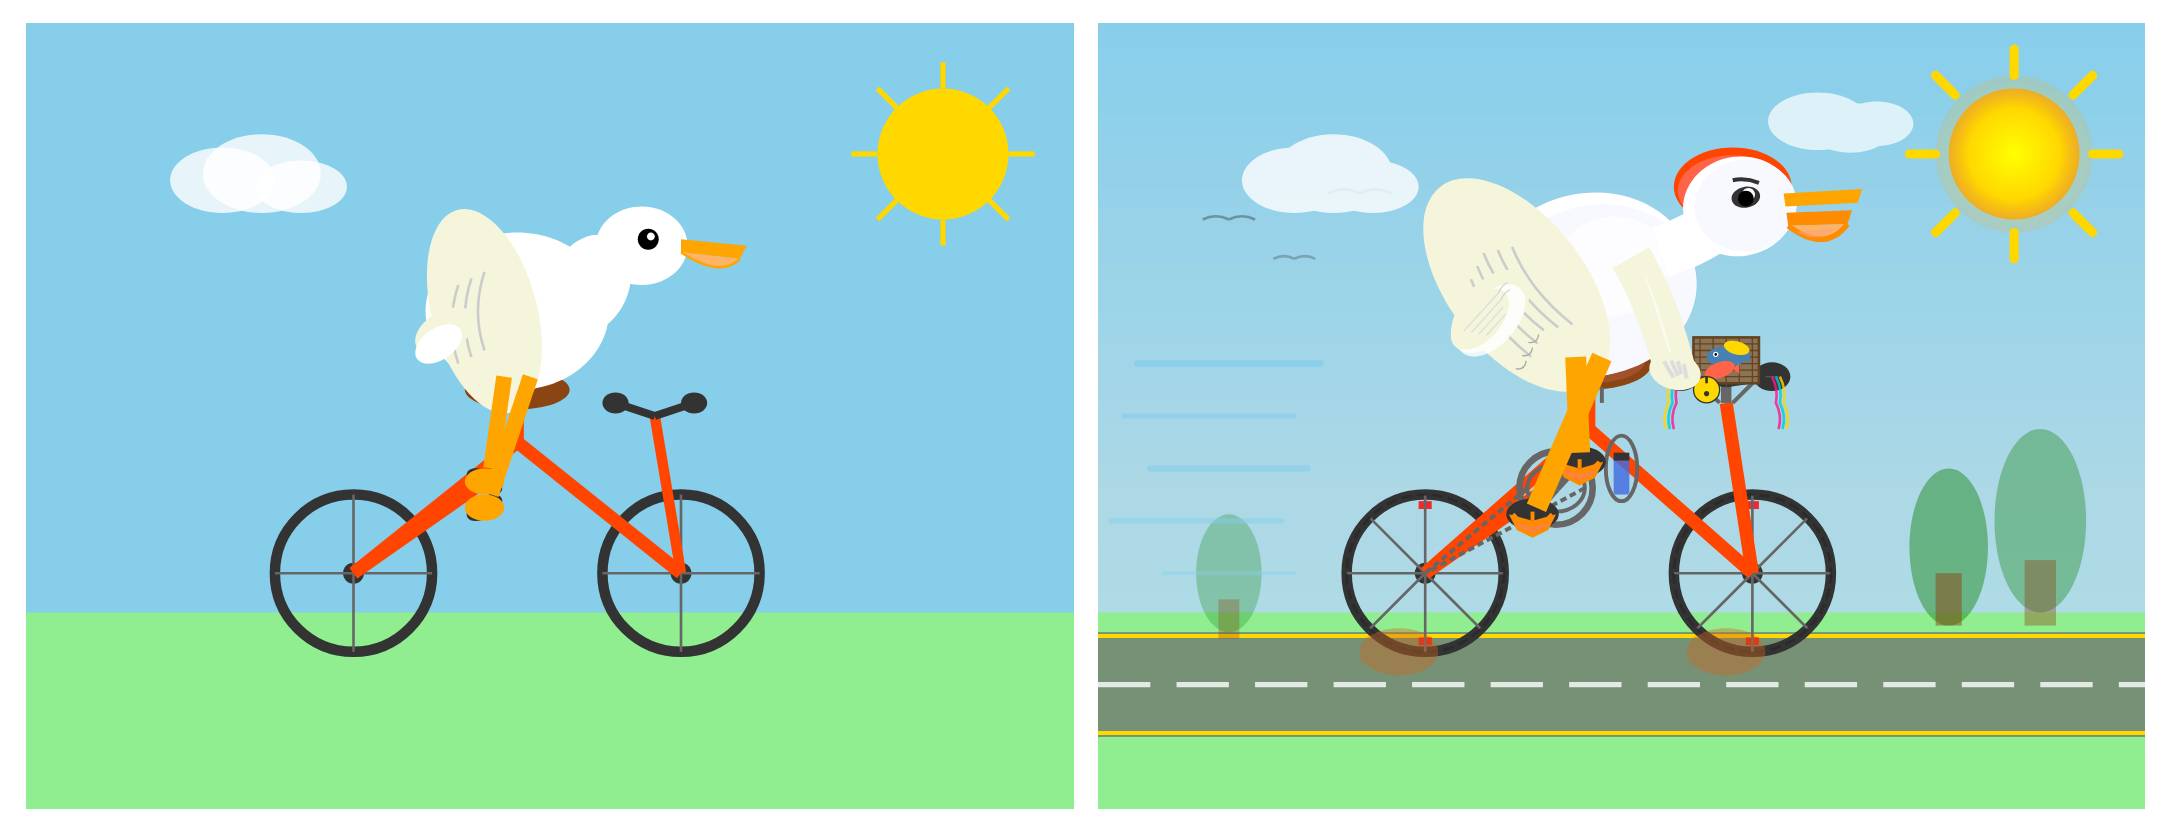
I tried a similar experiment to this a few months ago in preparation for the GPT-5 launch and was surprised at how little improvement it produced.
Robert's "skeptical take" conclusion is similar to my own:
Most models didn’t fundamentally change their approach. They tweaked. They adjusted. They added details. But the basic composition—pelican shape, bicycle shape, spatial relationship—was determined in iteration one and largely frozen thereafter.
Scaling HNSWs (via) Salvatore Sanfilippo spent much of this year working on vector sets for Redis, which first shipped in Redis 8 in May.
A big part of that work involved implementing HNSW - Hierarchical Navigable Small World - an indexing technique first introduced in this 2016 paper by Yu. A. Malkov and D. A. Yashunin.
Salvatore's detailed notes on the Redis implementation here offer an immersive trip through a fascinating modern field of computer science. He describes several new contributions he's made to the HNSW algorithm, mainly around efficient deletion and updating of existing indexes.
Since embedding vectors are notoriously memory-hungry I particularly appreciated this note about how you can scale a large HNSW vector set across many different nodes and run parallel queries against them for both reads and writes:
[...] if you have different vectors about the same use case split in different instances / keys, you can ask VSIM for the same query vector into all the instances, and add the WITHSCORES option (that returns the cosine distance) and merge the results client-side, and you have magically scaled your hundred of millions of vectors into multiple instances, splitting your dataset N times [One interesting thing about such a use case is that you can query the N instances in parallel using multiplexing, if your client library is smart enough].
Another very notable thing about HNSWs exposed in this raw way, is that you can finally scale writes very easily. Just hash your element modulo N, and target the resulting Redis key/instance. Multiple instances can absorb the (slow, but still fast for HNSW standards) writes at the same time, parallelizing an otherwise very slow process.
It's always exciting to see new implementations of fundamental algorithms and data structures like this make it into Redis because Salvatore's C code is so clearly commented and pleasant to read - here's vector-sets/hnsw.c and vector-sets/vset.c.
Wednesday, 12th November 2025
Fun-reliable side-channels for cross-container communication (via) Here's a very clever hack for communicating between different processes running in different containers on the same machine. It's based on clever abuse of POSIX advisory locks which allow a process to create and detect locks across byte offset ranges:
These properties combined are enough to provide a basic cross-container side-channel primitive, because a process in one container can set a read-lock at some interval on
/proc/self/ns/time, and a process in another container can observe the presence of that lock by querying for a hypothetically intersecting write-lock.
I dumped the C proof-of-concept into GPT-5 for a code-level explanation, then had it help me figure out how to run it in Docker. Here's the recipe that worked for me:
cd /tmp
wget https://github.com/crashappsec/h4x0rchat/blob/9b9d0bd5b2287501335acca35d070985e4f51079/h4x0rchat.c
docker run --rm -it -v "$PWD:/src" \
  -w /src gcc:13 bash -lc 'gcc -Wall -O2 \
  -o h4x0rchat h4x0rchat.c && ./h4x0rchat'
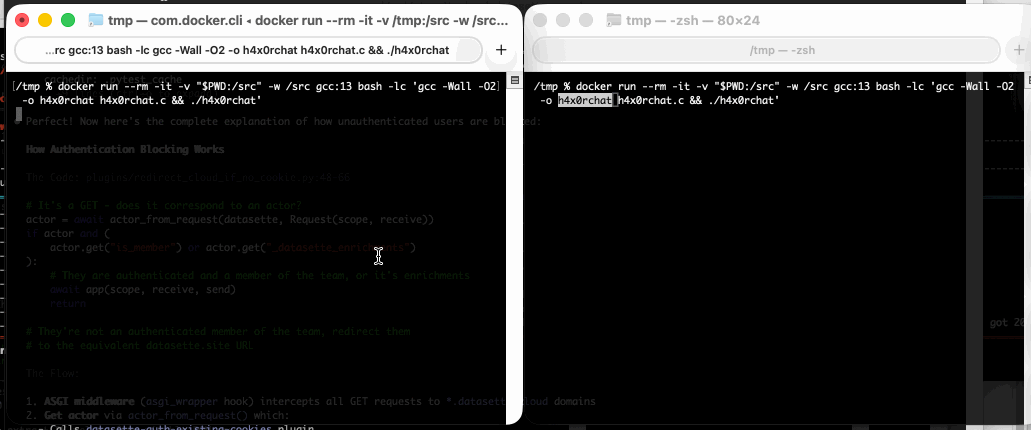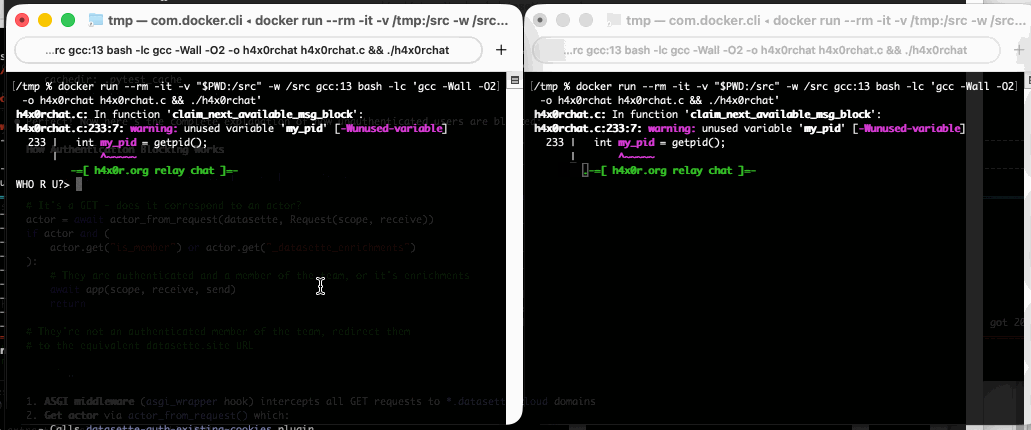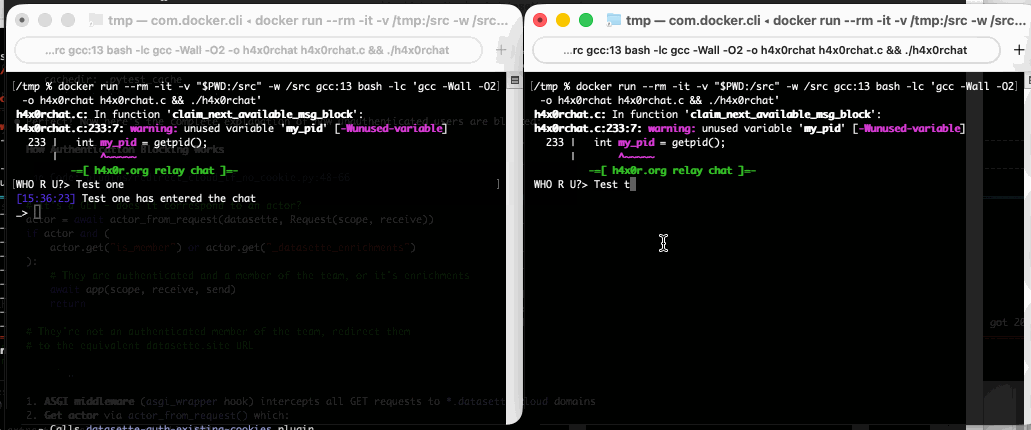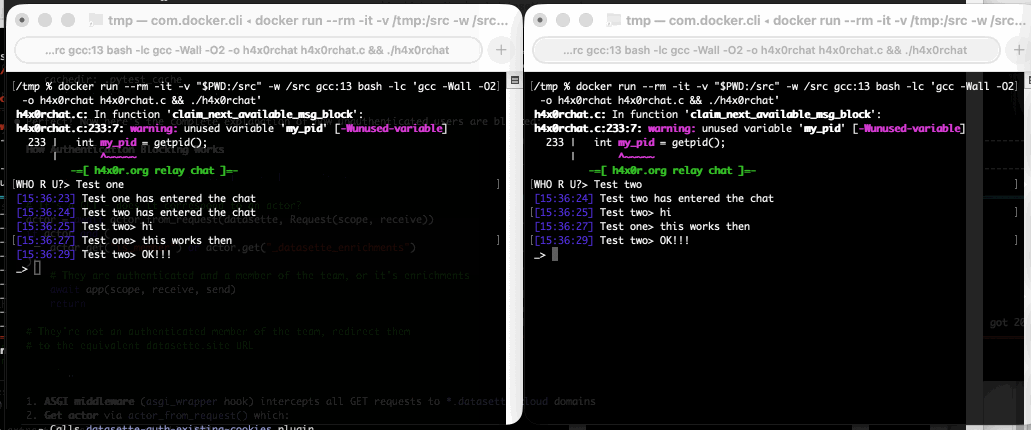
Run that docker run line in two separate terminal windows and you can chat between the two of them like this:
The fact that MCP is a difference surface from your normal API allows you to ship MUCH faster to MCP. This has been unlocked by inference at runtime
Normal APIs are promises to developers, because developer commit code that relies on those APIs, and then walk away. If you break the API, you break the promise, and you break that code. This means a developer gets woken up at 2am to fix the code
But MCP servers are called by LLMs which dynamically read the spec every time, which allow us to constantly change the MCP server. It doesn't matter! We haven't made any promises. The LLM can figure it out afresh every time
Thursday, 13th November 2025
What happens if AI labs train for pelicans riding bicycles?
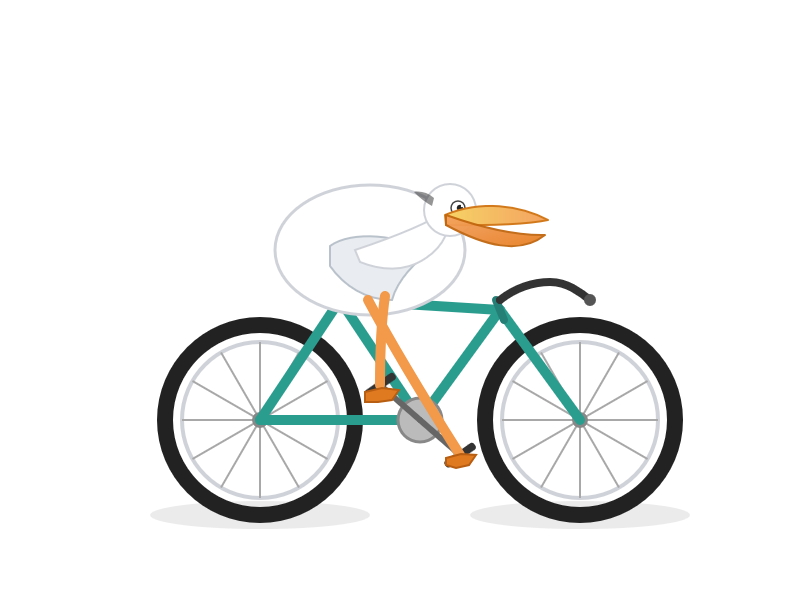
Almost every time I share a new example of an SVG of a pelican riding a bicycle a variant of this question pops up: how do you know the labs aren’t training for your benchmark?
[... 325 words]