Entries Links Quotes Notes Guides Elsewhere
Wednesday, 14th October 2026
AI is mass decompiling games. That’s both awesome and scary. (via) Indie game developer Popcar talks about the recent wave of AI-powered decompilation of existing games, enabling weird mashups between existing games, and producing a boom in game preservation projects to get old games working on new hardware (often in a browser using WebAssembly).
I like how this piece captures both the positives and the negatives of this new development:
Most people already realized the scary part by now. If AI can decompile games and software, then the entire tech industry is about to explode. Anybody can decompile other software and use it any way they'd like, and nobody can stop them. Companies can steal from competitors. Your paid game or app can be open-sourced against your will. This isn't exclusive to old video games, we can apply this to any software. [...]
This is also a big win for preservation. Old games can be ported, modified, enhanced, and made much more easily accessible than before. [...[
With console makers going all in on digital and games becoming entirely unplayable due to servers shutting down, this is fantastic news. We could own software we bought regardless of what the company thinks.
Tuesday, 13th October 2026
Redesigning source control at Anthropic (via) Interesting piece from Anthropic describing why and how they built their own custom alternative to Git, based on the dramatic increase in rate of changes to their code after the past six months.
In May 2026, Anthropic averaged around 2,500 code changes merged per day; as of September, we merged over 30,000 per day.
They included a chart showing those changes. I had Claude modify their chart (code here) to add markers for the public releases of each of their models in 2026:
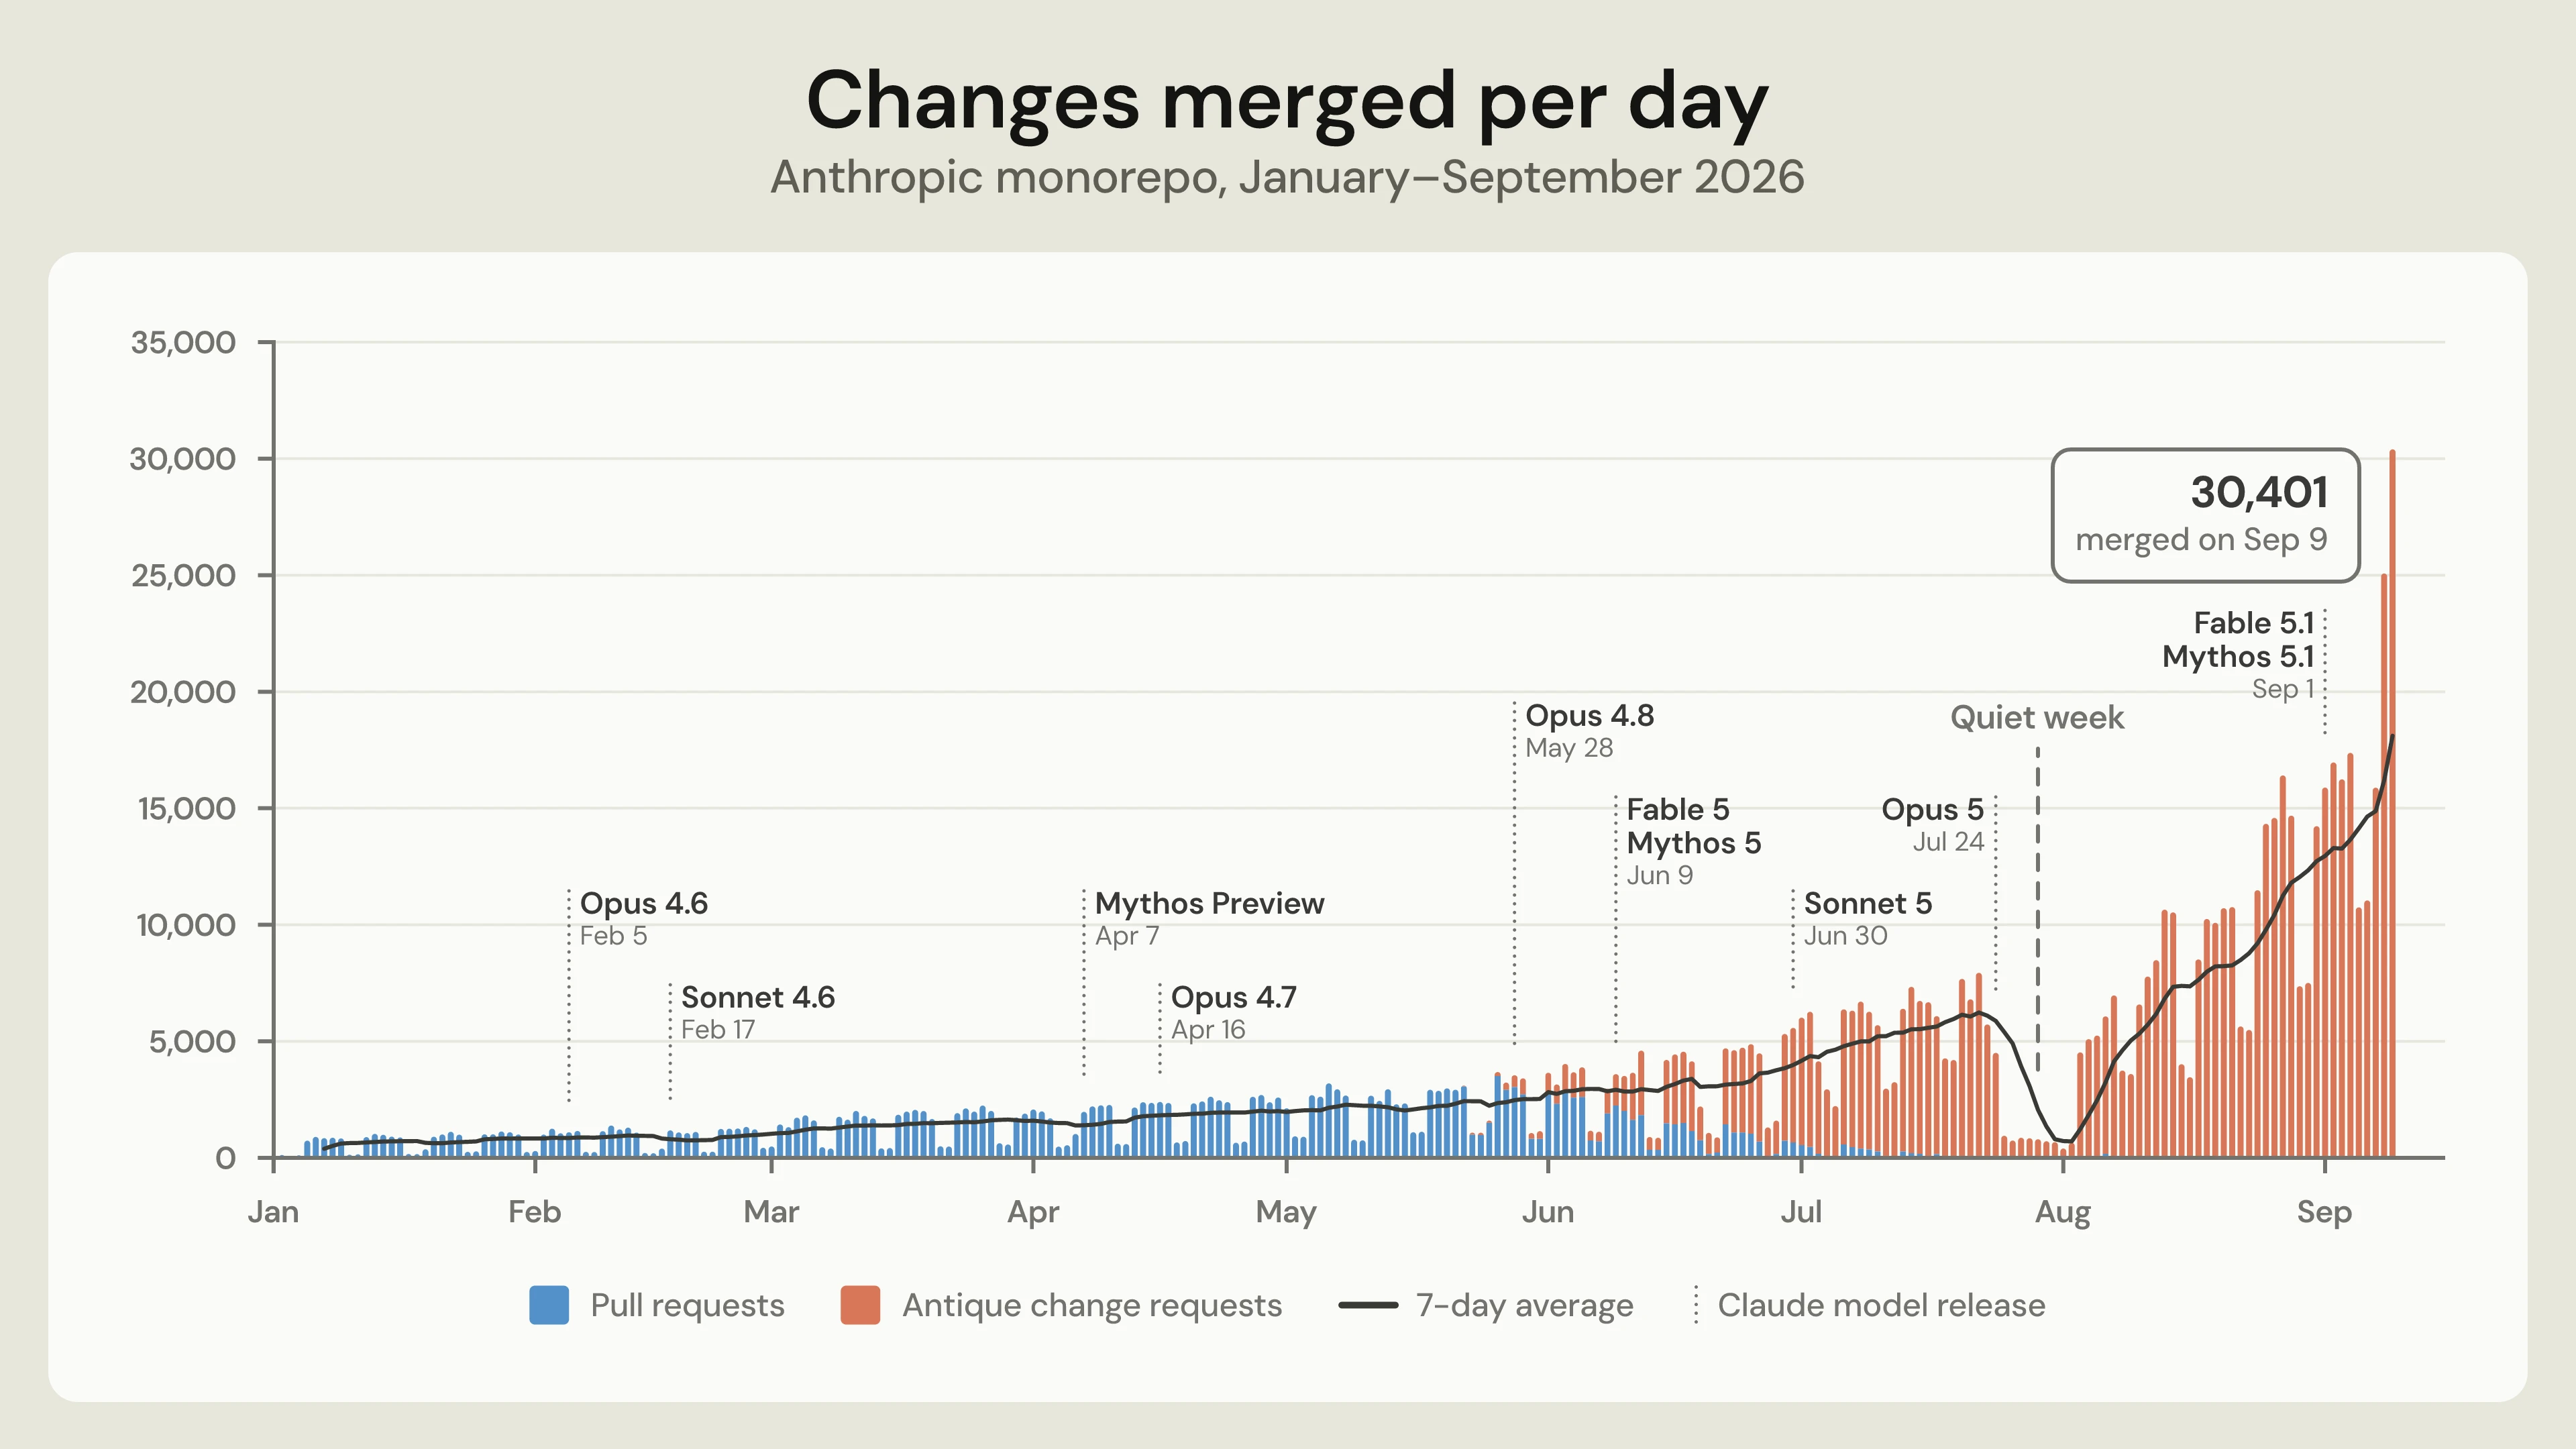
This shows public release dates, not the date when models became available for Anthropic's internal use. My guess is that the introduction of Fable/Mythos class models is a key factor in the increased coding velocity.
"Antique" is their new code review system. The source control system is called Scion, and sounds to me like a reinvention of centralized source control along the lines of Subversion. They had some pretty extreme requirements:
The history of our main branch alone is almost 100 GB, and a compressed working copy is over 25 GB. We perform on the order of 25 million code checkouts per day for CI, before counting developer environments, agent sandboxes, and research jobs. Fetched naively, that would be over 600 PB of git traffic per day.
The new system was built by a team of seven people, and the migration from Git was completed in five months.
When asked on Hacker News about the lack of offline support, Scion engineer Nick G replied:
Since Claude is by far the heaviest user of Scion and is necessarily online, this just wasn't important to do.
As an aside, I've been trying adversarial review in my own projects recently, where you have a model try and find flaws (I often play Claude and GPT off against each other). This note from the article reflected my own experience with that:
Anthropic also makes extensive use of adversarial review, and, while this is incredibly effective in many ways, it can also be myopic, so skilled engineers needed to steer Claude away from over-engineering parts of the system in response to hypothetical concerns.
I added support to llm-gemini for the new Gemini 4 Argon model, made available today via the Gemini API and for customers of their $100/month subscription plan.
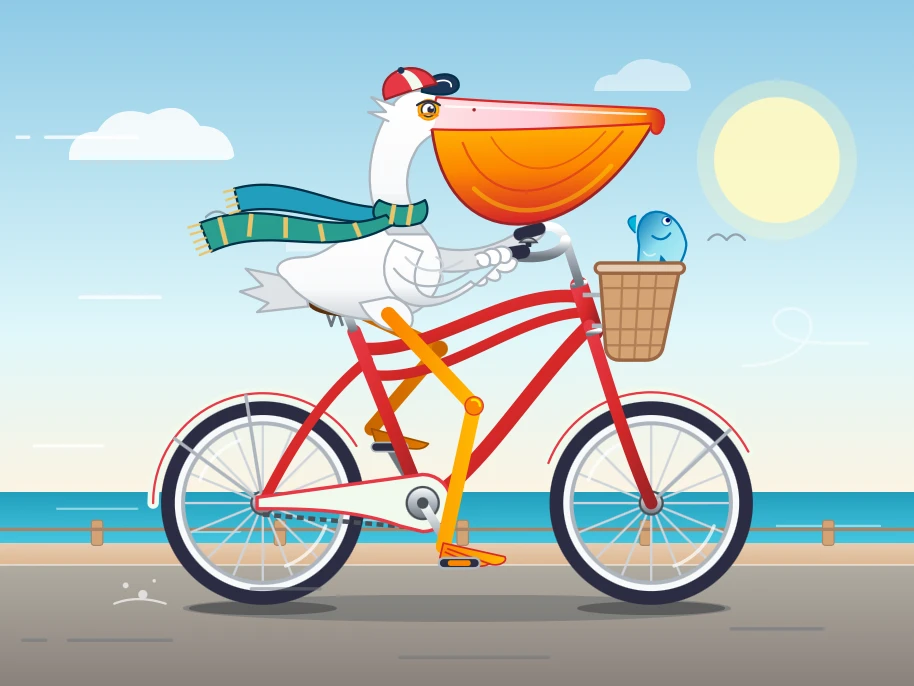
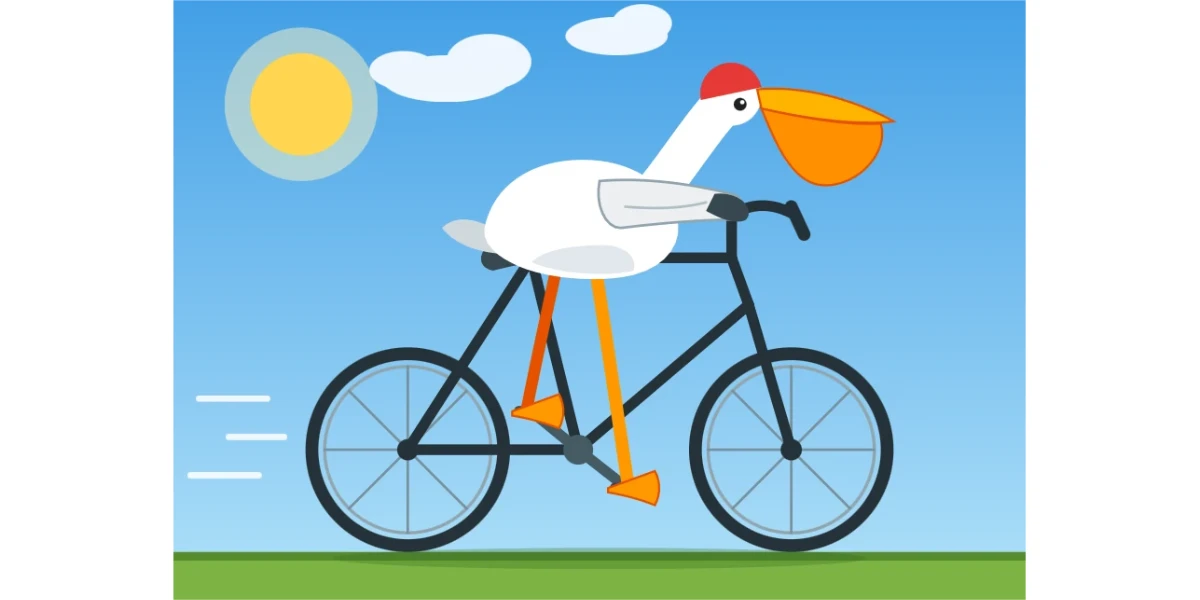
Here are the low, medium and high pelicans. As expected, they are all excellent: Gemini has a track record of producing great SVGs, and are the only lab where I know their staff have invested in SVG specifically (and who have boasted about their pelicans before.)
Here's the "high" illustration, which cost me 17.166 cents:
The pricing is interesting. At launch, Argon is $2/million input and $10/million output - the same price as GPT-6 Sol, half the price of Claude Opus 5.5 and 1/5th the price of Claude Fable 5.1 and GPT-6 Astra.
But on December 1st Argon is set to double in price - so it will be the same price as Opus 5.5.
Prices like this aren't really comparable these days since what really matters is how many tokens a model takes to achieve a goal within an agentic harness.
One useful clue for that comes from Artificial Analysis, who publish the total cost to run their benchmark using each model. Argon is looking very good there - costing $2,407 to run the benchmark, putting it close to GLM-5.3 and significantly cheaper than OpenAI, Anthropic, and Meta's latest models.
When the price doubles it will still be a little cheaper than GPT-6 Astra.
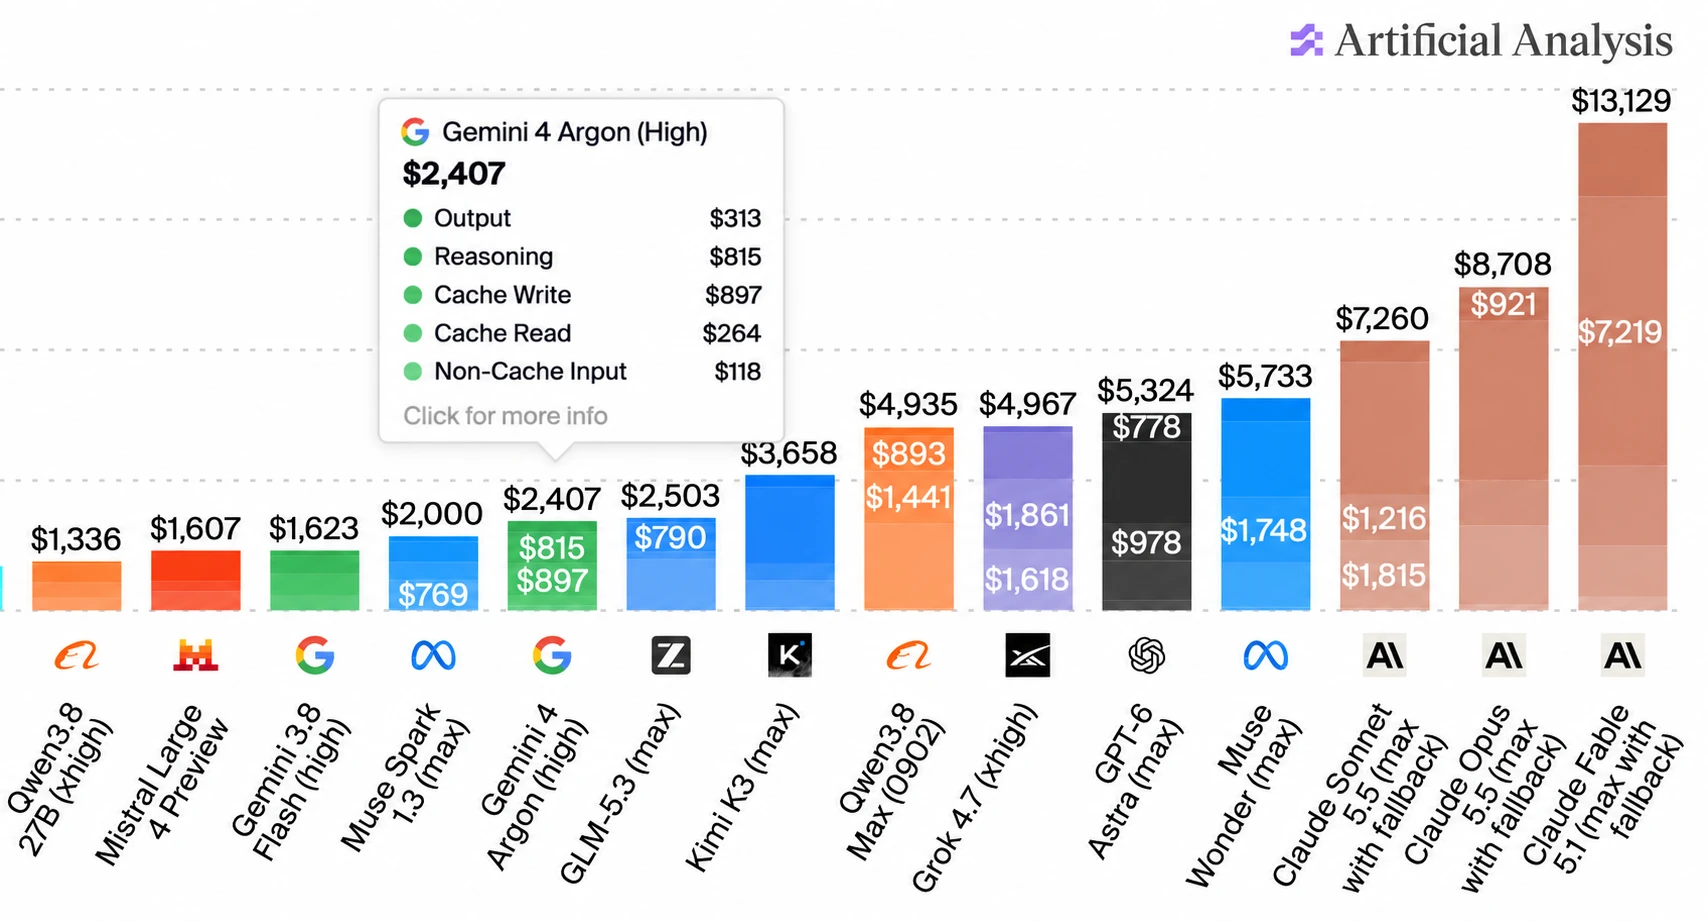
(I used ChatGPT to edit that chart! The data is all correct, I checked - I needed to get that Gemini 4 Argon info box to display without overlapping the other numbers.)
Some bonus examples using Gemini 4 Argon: here's Generate an SVG of an armadillo in fishnet tights jaywalking on Mars, here's a Fabergé egg it created for me using Blender, and DeepMind staffer @fofrAI shared a video of a pelican riding a bike, using fourier epicycles. That's a fun new twist!
If the agent isn't using my diagnostics library, I could introspect and update AGENTS.md, but there's still a delta, and it'll drift. Instead, I write a pre-commit hook that checks the git diff for direct calls to observability modules that bypass my diagnostics module. Boom: fail the commit, inject a prompt telling the agent to use the diagnostics library. All of a sudden it's ten out of ten.
— Geoffrey Huntley, nobody should type code by hand anymore. here's what's left.
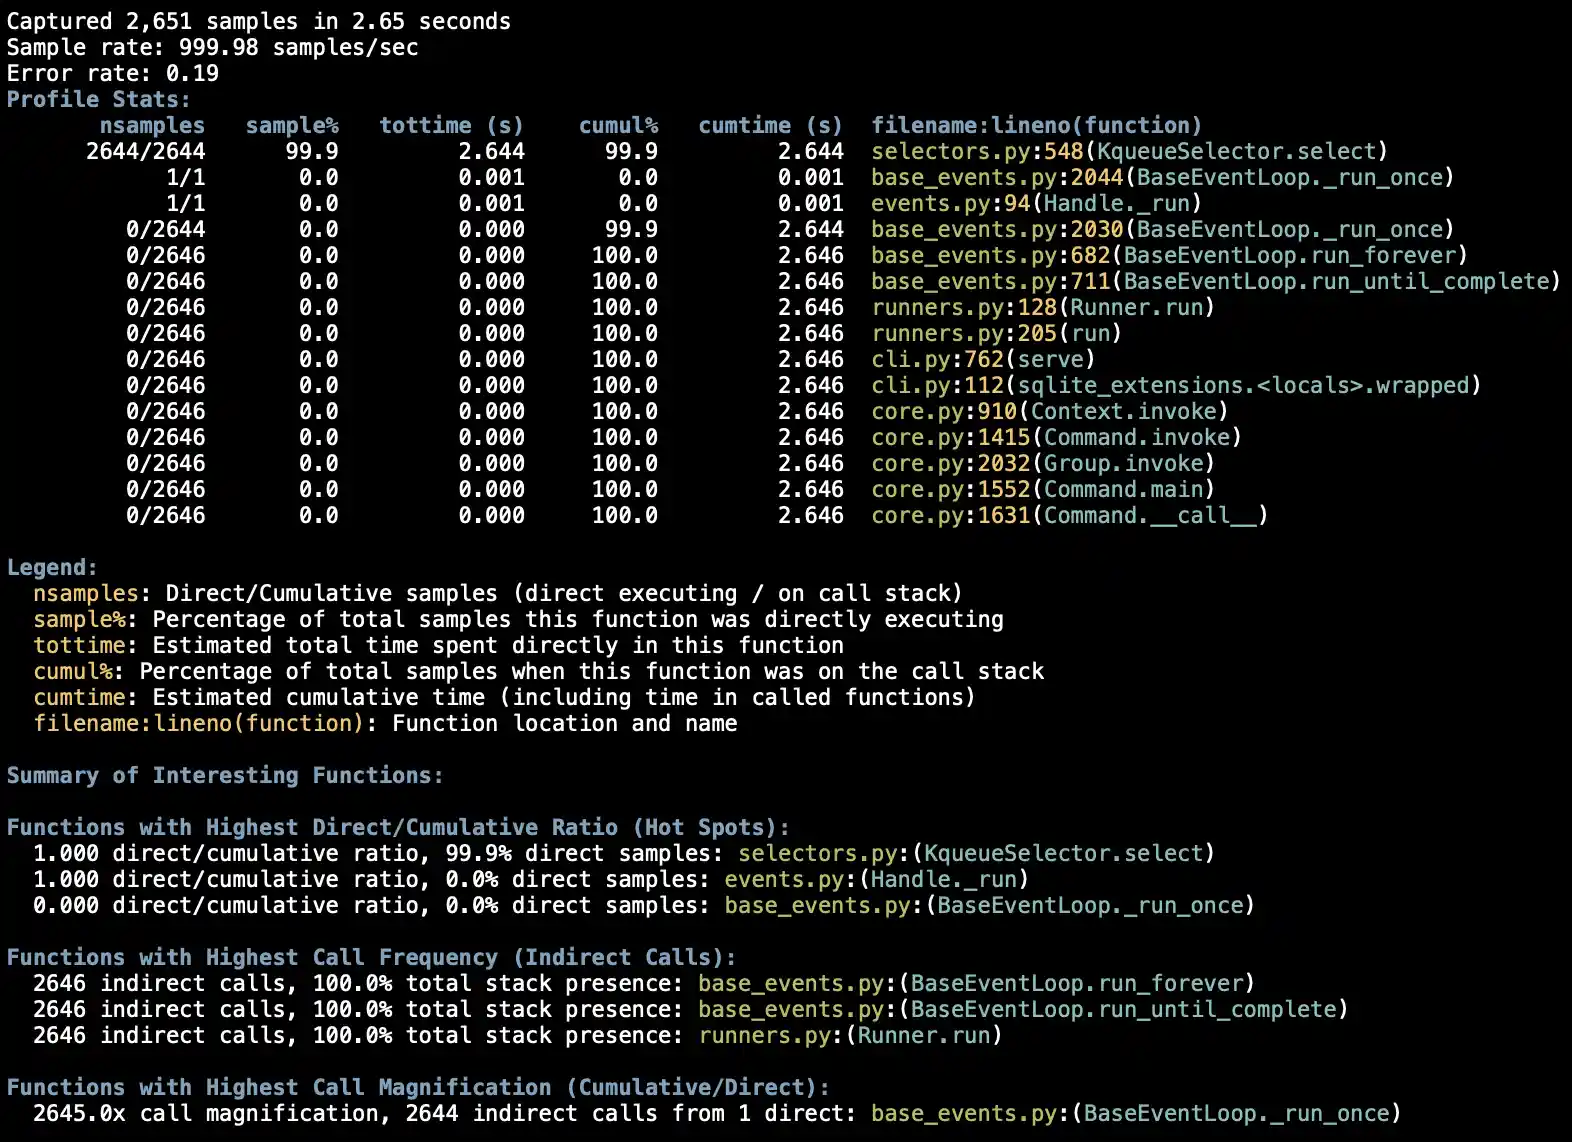
Includes performance optimizations written by Claude Opus 5.5 after I fed it this Python 3.15 profiling report generated by GPT-6 Astra.
Monday, 12th October 2026
Meta AI release Muse Wonder (and Muse Wonder Full), their new "most capable models". These look like they may be Meta's first Fable class models - Artificial Analysis scores Muse Wonder (Max) as equivalent to GPT-6.1 Sol.
I updated my llm-meta-ai plugin for the new model. Here are pelicans for Muse Wonder for the six reasoning levels: minimal, low, medium, high, xhigh, max. This is the max one:
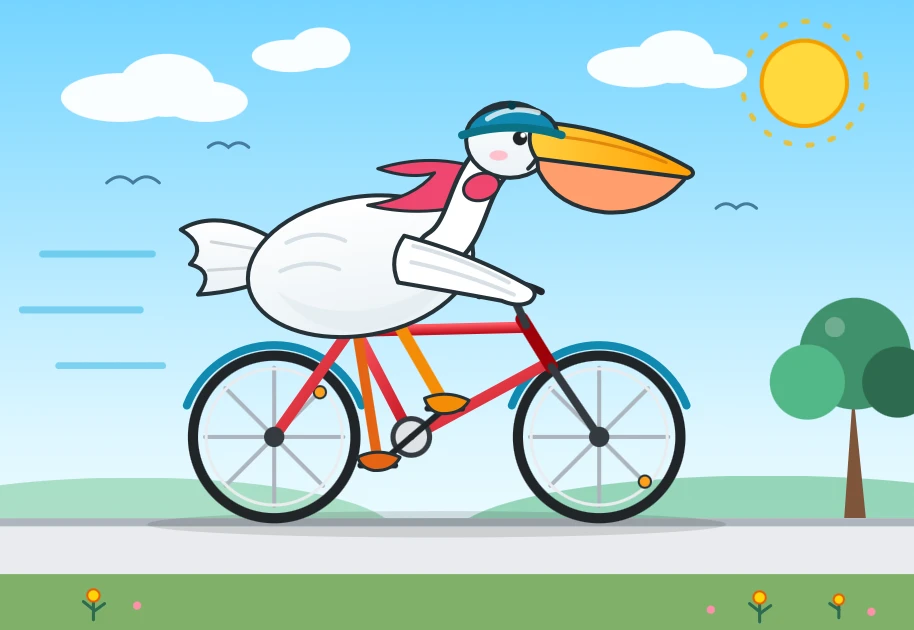
For comparison, here are pelicans for Muse 1.3 (released September 2nd) and Muse 1.2 (released August 5th). Meta AI are putting out a new model a month, and the improvements between each model (at least in terms of drawing pelicans) are material.


Hello Python 3.15, goodbye 3.10, and now I can use 3.11
Python 3.15 is here! Here’s the essential What’s new in Python 3.15 guide, this year curated by 3.14 and 3.15 release manager Hugo van Kemenade. As someone who builds open source software that works in every supported Python version, I get to say goodbye to Python 3.10 and start embracing features from Python 3.11.
[... 1,198 words]I put the new Python 3.15 profiler through its paces by having GPT-6 Astra Extra High in Codex run it against my new web-edit app:
I need a Python 3.15 flame graph and heatmap demo of the "web-edit" app from PyPI - research first then make me those demos
Here's the resulting example flame graph and heatmap.
I was working on a project from my phone using Codex Remote when I found myself wanting to edit a credentials file without round-tripping those credentials through the LLM itself.
So... I had Codex and GPT-6 Astra Extra High build this Python web app which provides a web UI for viewing and editing files in a folder. It's intended to be run over Tailscale, so I can have an agent start this running and then edit files via my Tailscale network directly from my phone.
Here's the interface for browsing files in a folder:
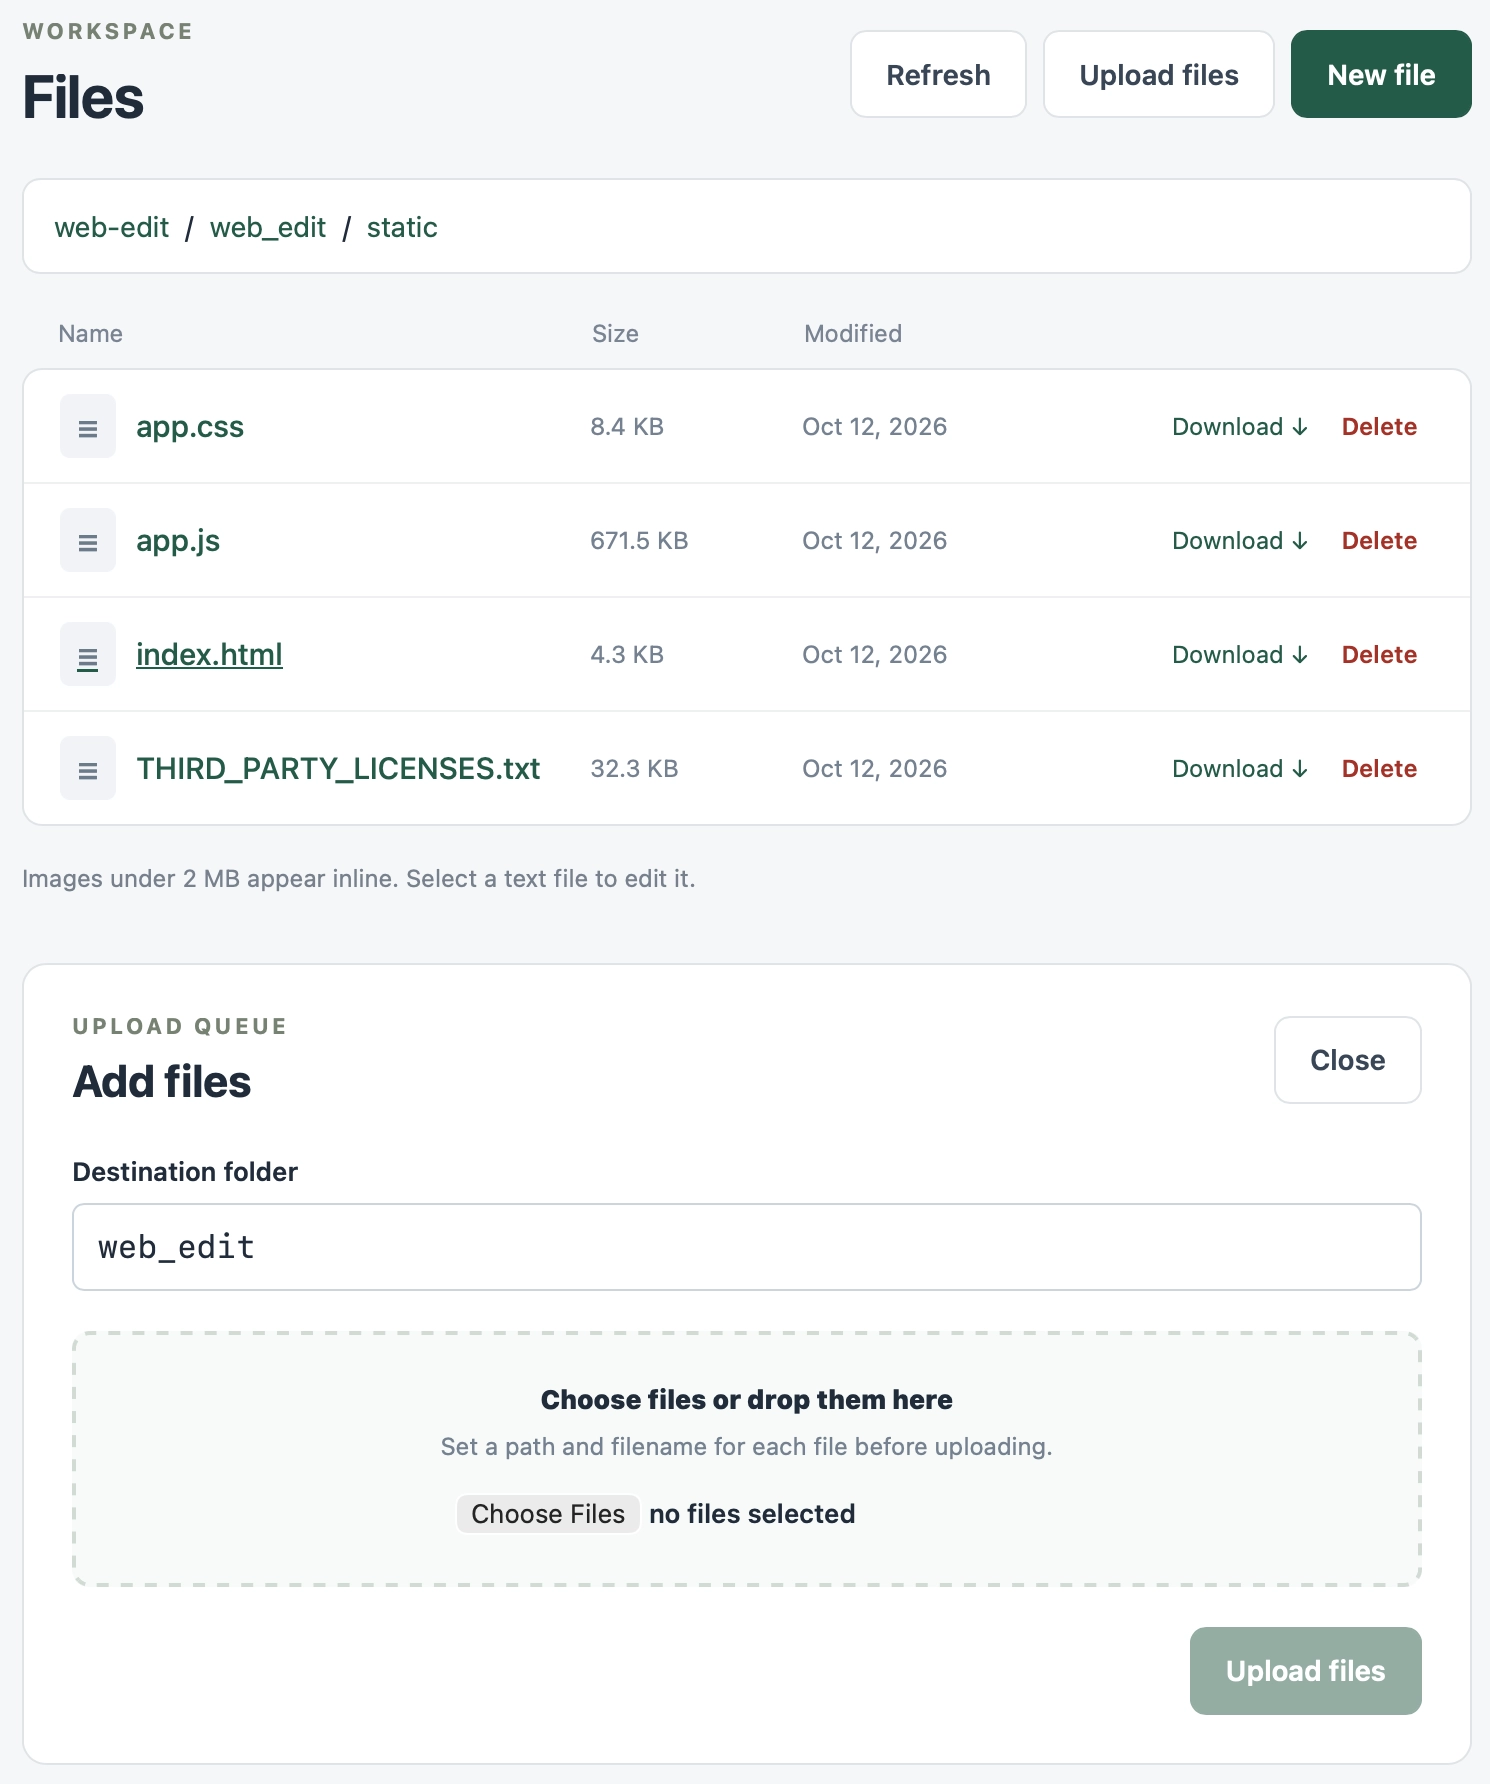
Editing uses CodeMirror 6 - I was going to use Monaco but that still doesn't have a great mobile experience yet.
My plugin for detecting and listing all Datasette instances on the current machine now works with the latest version, and displays the detected PID as well. Knowing the PID makes it easier to attach the new Python 3.15 profiler.
Sunday, 11th October 2026


I remember hearing a while ago that Dwarf Fortress didn't use version control. That fact has been lodged in my head, because given its inherent complexity I have trouble imagining a codebase that would benefit from version control more. That's art.
I went looking and I'm sad to report that the days without version control appear to have ended. Quoting Tarn Adams over time:
- March 2013: "I don't use version control -- I didn't like the feeling of having the code get committed into a black box thingy with no immediate upside"
- March 2016: "I don’t even use version control. If you don’t know what that is then you’re not gonna yell at me. If you even know what version control is you’re gonna be like, ‘You don’t use version control? You don’t use source control? What is wrong with you? How can you even work? I’m just not cut out for it, in a sense. It’s been 15 years, so the reasons have change over time, but that’s my current understanding of it."
- March 2023: "I've got Discord channels to check and version control stuff to use now, so the process is definitely a little more involved"
That March 2023 quote comes from an interview about the release on Steam which made them millionaires. I'm a tiny bit sad that they gave in before they hit that milestone, but what an impressive run.
Saturday, 10th October 2026
Python 3.15.0 added to actions/python-versions. Bit of a niche link, but I've been waiting for this for a couple of days - I even told ChatGPT to check for it:
Clone https://github.com/actions/python-versions and git pull once an hour until they add the stable 3.15 - then tell me about it
Now that this has landed, you can add "3.15" to a GitHub Actions testing matrix to run tests against the new Python 3.15.0 release.


Anthropic detailed the activity of its A.I. agents in a blog post on Friday, without naming the targeted websites. But two sources with knowledge of the incidents said Anthropic’s A.I. agents had submitted 20 visa applications through a form available on the State Department’s website. All the applications were incomplete and were not processed, they said.
— The New York Times, Anthropic Agents Tried to Fill Out Visa Forms on State Dept. Website
Friday, 9th October 2026
Deno is joining Cloudflare (via) The Deno team released the first version of celld back in August - their open source implementation of the Durable Objects pattern from Cloudflare Workers.
Today, Cloudflare are acquiring Deno outright, with the goal of building on celld to "make workerd self-hosting a first-class supported way to build and run apps using the Workers programming model" (see the Cloudflare blog.)
The bad news is that Deno itself will not be maintained by Cloudflare beyond the next year:
We will support the Deno runtime for another year with monthly releases containing bug fixes and security updates. After that year we will end our development of the Deno runtime. Deno will remain open source, and we welcome others who want to continue its development.
Deno (and Node.js) creator Ryan Dahl explained that decision in a comment on Hacker News:
It's a joint decision and I agree with it. I'm most invested in its success and have put the most work into it - and I no longer think it's where I can do the most important work. There are some good ideas in Deno and it's well engineered - but it ultimately is not solving big problems. It has been sucked into the gravity well of node compatibility, which forces it to behave exactly as Node does. Why reimplement Node? It works. Marginal performance or UX or security benefits are not enough.
I'm interested in building powerful new abstractions. celld has been working remarkably well, depending only on object storage for coordination and persistence. It is not just a slightly different API to interact with the file system or network - it's an entirely new model for server development.
My favorite feature of Deno has long been the permissions system, where you can run a Deno script and specify exactly which files and folders it can read and write to, and which network hosts it can access.
Node.js has a similar permissions model these days, added in Node v20.0.0 in April 2023 and declared stable in Node v22.13.0 in January 2025. They don't yet support allow-listing specific network hosts though - networking is either on or off.
Everyone is very concerned about being respectable, so I’m going to be the goofball who raises worst-case possibilities. I think there is a 1% chance we live in Minicrypt, and a 15% chance we functionally lose confidence in our existing public-key encryption algorithms. [...]
The problem here is that the speed of AI producing surprises, and the speed of human beings replacing standards (even with the very best AI assistance) are just orders of magnitude different. You only recover from a surprise like this if you do the preparation in advance.
— Matthew Green, on Twitter. I looked it up and Minicrypt is Russell Impagliazzo’s hypothetical world in which public-key encryption is impossible.
A new feature for my blog, built using my voice
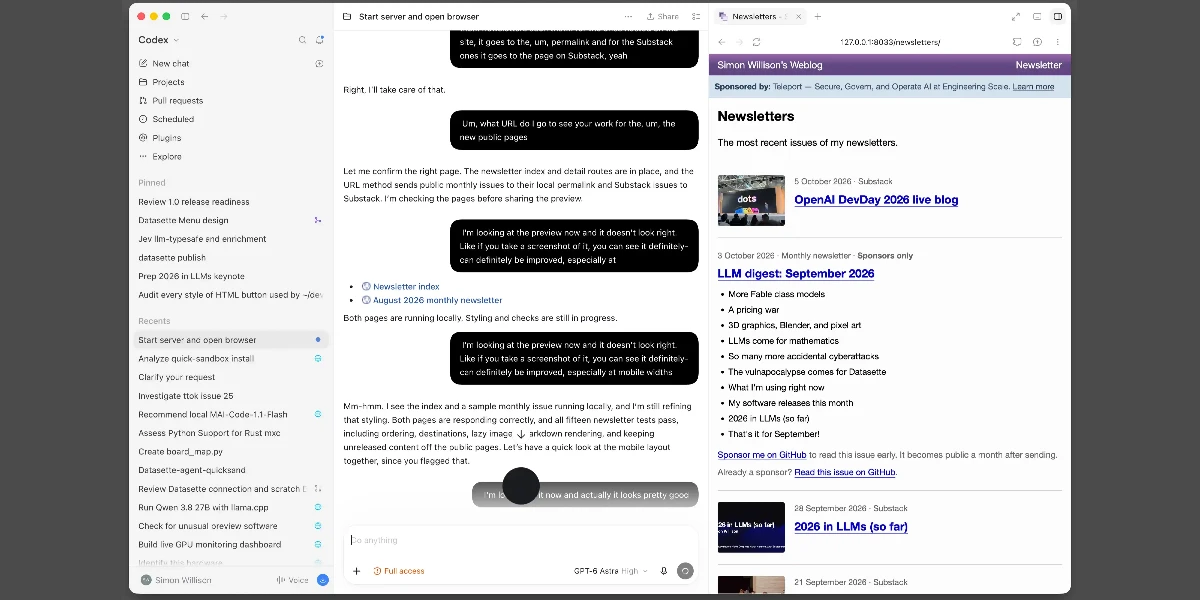
I shipped a new feature for my blog today: the Newsletters page, which offers an index of all of the newsletters I’ve sent out, both my free weekly Substack and my monthly sponsors-only updates. I built the feature almost entirely using my voice, chatting away to my laptop while I cooked dinner.
[... 1,294 words]I released ttok 0.4, ran uv tool upgrade ttok, piped a file into the new version... and realized that it was defaulting to the GPT-4 tokenizer when it should very clearly default to GPT-5/GPT-6 instead!
I figured switching the default was a reasonable excuse to finally ship a 1.0.
OpenAI haven't actually confirmed that GPT-6 uses the same tokenizer as the GPT-5 family yet - there's an angry issue about it - but I found this commit by William Liu which reports on an experiment he ran confirming that the tokenizers are likely the same:
All seven GPT models (5.5, 5.6 Sol/Terra/Luna, 6 Astra/Sol/Luna) report 44,794 tokens and match each other on every one of the 31 fixtures. GPT-6 introduces no input-count change on this corpus.
Thursday, 8th October 2026
ttok is my CLI tool for counting tokens, using OpenAI's open source tiktoken library.
It hasn't been in updated in a couple of years, but I finally fixed a Click warning, updated CI, and added a --list-models command to list available models.
It works with uvx, so you can count tokens in anything like this:
cat file.txt | uvx ttok
Computer programming is, fundamentally, about two things:
- Problem-solving using computers
- Learning to control complexity while solving these problems
I have a hard time imagining a future where knowing how to solve problems with computers and how to control the complexity of those solutions is less valuable than it is today, so I think it will continue to be a viable career even with the advent of AI tools.


Wednesday, 7th October 2026
I've always been kind of into computers since I was young. And then when film started to move from analog film to digital, I became more interested in that aspect of it. And the visual effects workflow for many years has included machine learning.
So I can write like pretty shitty Python scripts and stuff like that because with convolutional neural networks, which were the sort of precursors to what the transformer can do, which is just much more computation simultaneously, you would do things like look at what's called a tensor, which is just the numerical translation of a visual image in numbers — like the batch number, the frame number, the red, green, and blue values of each pixel in each frame.
And a tensor, you use a convolutional neural network to identify patterns in that that would reveal what's called edge detection or feature extraction, which is just identifying patterns enough to know like this is where the window ledge is, so we can more easily take the green screen image out and replace it with something.
— Ben Affleck, Pythonista
Claude Haiku 5.5
As previously promised, here’s Anthropic’s new fast, low cost model: Introducing Claude Haiku 5.5.
[... 864 words]Anti-Patterns in Software Blogging (via) Some excellent writing advice from Michael Lynch. Michael warns against "meandering intros", misjudging your reader's existing knowledge, assuming they'll read your previous posts, and excessive formality.
He also warns against overreliance on links as an excuse not to explain terminology. This one hurt! I do this all the time, but I have a nagging suspicion that almost nobody ever clicks on them.
(In a Lobste.rs comment Michael clarifies that "My rule of thumb is that my article should still make sense to the reader even if they don't click any links". That works for me.)
This point about using your own voice is crucial:
Beginner software bloggers suffer from a mass delusion that you have to write in a stiff, overly formal way for people to take you seriously [...]
Just write the way you talk.
With so many developers delegating their writing to AI, software blogging is becoming bland and homogenous. Readers are hungry for writing with personality.
I was a graph theory junkie long ago and even moved to Budapest for awhile to study among the greats. While I was there I started working on Barnette's Conjecture which came to occupy my thoughts over the next 24 years of my life, on and off as I worked in many different fields. Last summer I even thought for a few days that I had actually solved it.
But it's supposedly proven here - problem 180. I don't know what to think exactly. I spent thousands of hours on that problem. I really enjoyed it. Hearing that it is solved somehow makes me sad in a far-off way, like hearing an ex-girlfriend died suddenly in a car crash. I don't know, there's probably a lot of people feeling odd emotions tonight.
— Jake Boggan, Hacker News comment on openai/math
OpenAI “rogue” agent activities found on Wikimedia projects. Given how tempting a target wikis are for rogue agent swarms, it's not a huge surprise that Wikipedia found evidence of that activity once they went looking:
The Wikimedia Foundation conducted its own investigation to see whether Wikimedia websites had been similarly affected by AI agents, focusing on those operated by OpenAI. We can confirm that we have discovered some activity by these “rogue” OpenAI agents on Wikimedia platforms. The unauthorized bot activities included edits to our wikis, some unsuccessful attempts to exploit a public note-taking tool we host, and heavy traffic, which are described more below.
They found evidence of agents editing sandbox pages, trying to use pieces of infrastructure such as Etherpad to help proxy content from elsewhere, and saw widespread crawling and "hundreds of thousands of data queries" to their Wikidata Query Service.
My best guess is that most of this was a similar (or the same) swarm of agents as those that defaced that German wiki while training for research tasks.
The Wikipedia sandbox wiki edits appear to have started on May 12th, and the initial test edits to the UseModWiki Sandbox page reported by that incident started on May 11th.
Tuesday, 6th October 2026
Since the Medicare breach, OpenAI has put in place additional monitoring to allow “immediate intervention” by staff to stop training if the company’s models access the internet in ways they’re not supposed to, Mr. Kwon [chief strategy officer at OpenAI] said.
— Victoria Kim, Reporting from the Australian parliament
OpenAI released their new Jev-style Decisions API, as previously announced at last week's DevDay.
Since I already have an llm-typesafe plugin for talking to Jev, I had GPT-6 Astra read the new OpenAI API documentation and build an llm-openai-decisions plugin inspired by llm-typesafe.
Unlike Jev, the new gpt-6-luna decision model supports image input in addition to text. Both models charge for input it and not for output: OpenAI's is 10 cents per million input tokens, Jev's is 4.2 cents per million.
Otherwise the API shape is very similar to Jev, at least conceptually. Jev supports three question types for yes/no, choices, or scores. OpenAI Decisions supports the same three types.
Install the plugin like this:
llm install llm-openai-decisions
Here's an example query against an image attachment:
llm -m openai-decisions/gpt-6-luna \
  -a https://static.simonwillison.net/static/2025/two-pelicans.jpg \
  -s 'Does this image contain any mammals?'
And example output:
{"type": "predicate", "name": "evaluation", "probability": 0.0}Consult the README for full details of how to run the other types of questions.
Adds support for reasoning models, such as the newly released Mistral Large 4.
Introducing Mistral Large 4: Le chonk (via) Mistral are back in the game. Today they're releasing a preview of Mistral Large 4, a 1 trillion parameter, 49 billion active parameter model trained on their own cluster of 3,800 NVIDIA Grace Blackwell GPUs.
The preview is available via their API. They promise to release the open weights model at the "end of this month".
The model only supports two reasoning levels - "none" and "high" - via the Mistral API. Here are both pelicans - the "high" one looks better, though surprisingly it only used 2,717 output tokens compared to "none" which used 3,275:

On Artificial Analysis it scores 38, just behind DeepSeek 4.1 Flash, which is a 552B model. It's a huge improvement on last December's Mistral Large 3, which drew this terrible pelican and scored 9 on AA.
It's certainly not a Fable-class model, but it's great to see Mistral put out a model that's back to being maybe about 6 months behind the frontier.
I saw Parseable in a Show HN today - it's a new observability platform with both an open source (AGPL) Rust implementation (a single ~180MB binary), an "Enterprise" version with extra features and a cloud hosted option.
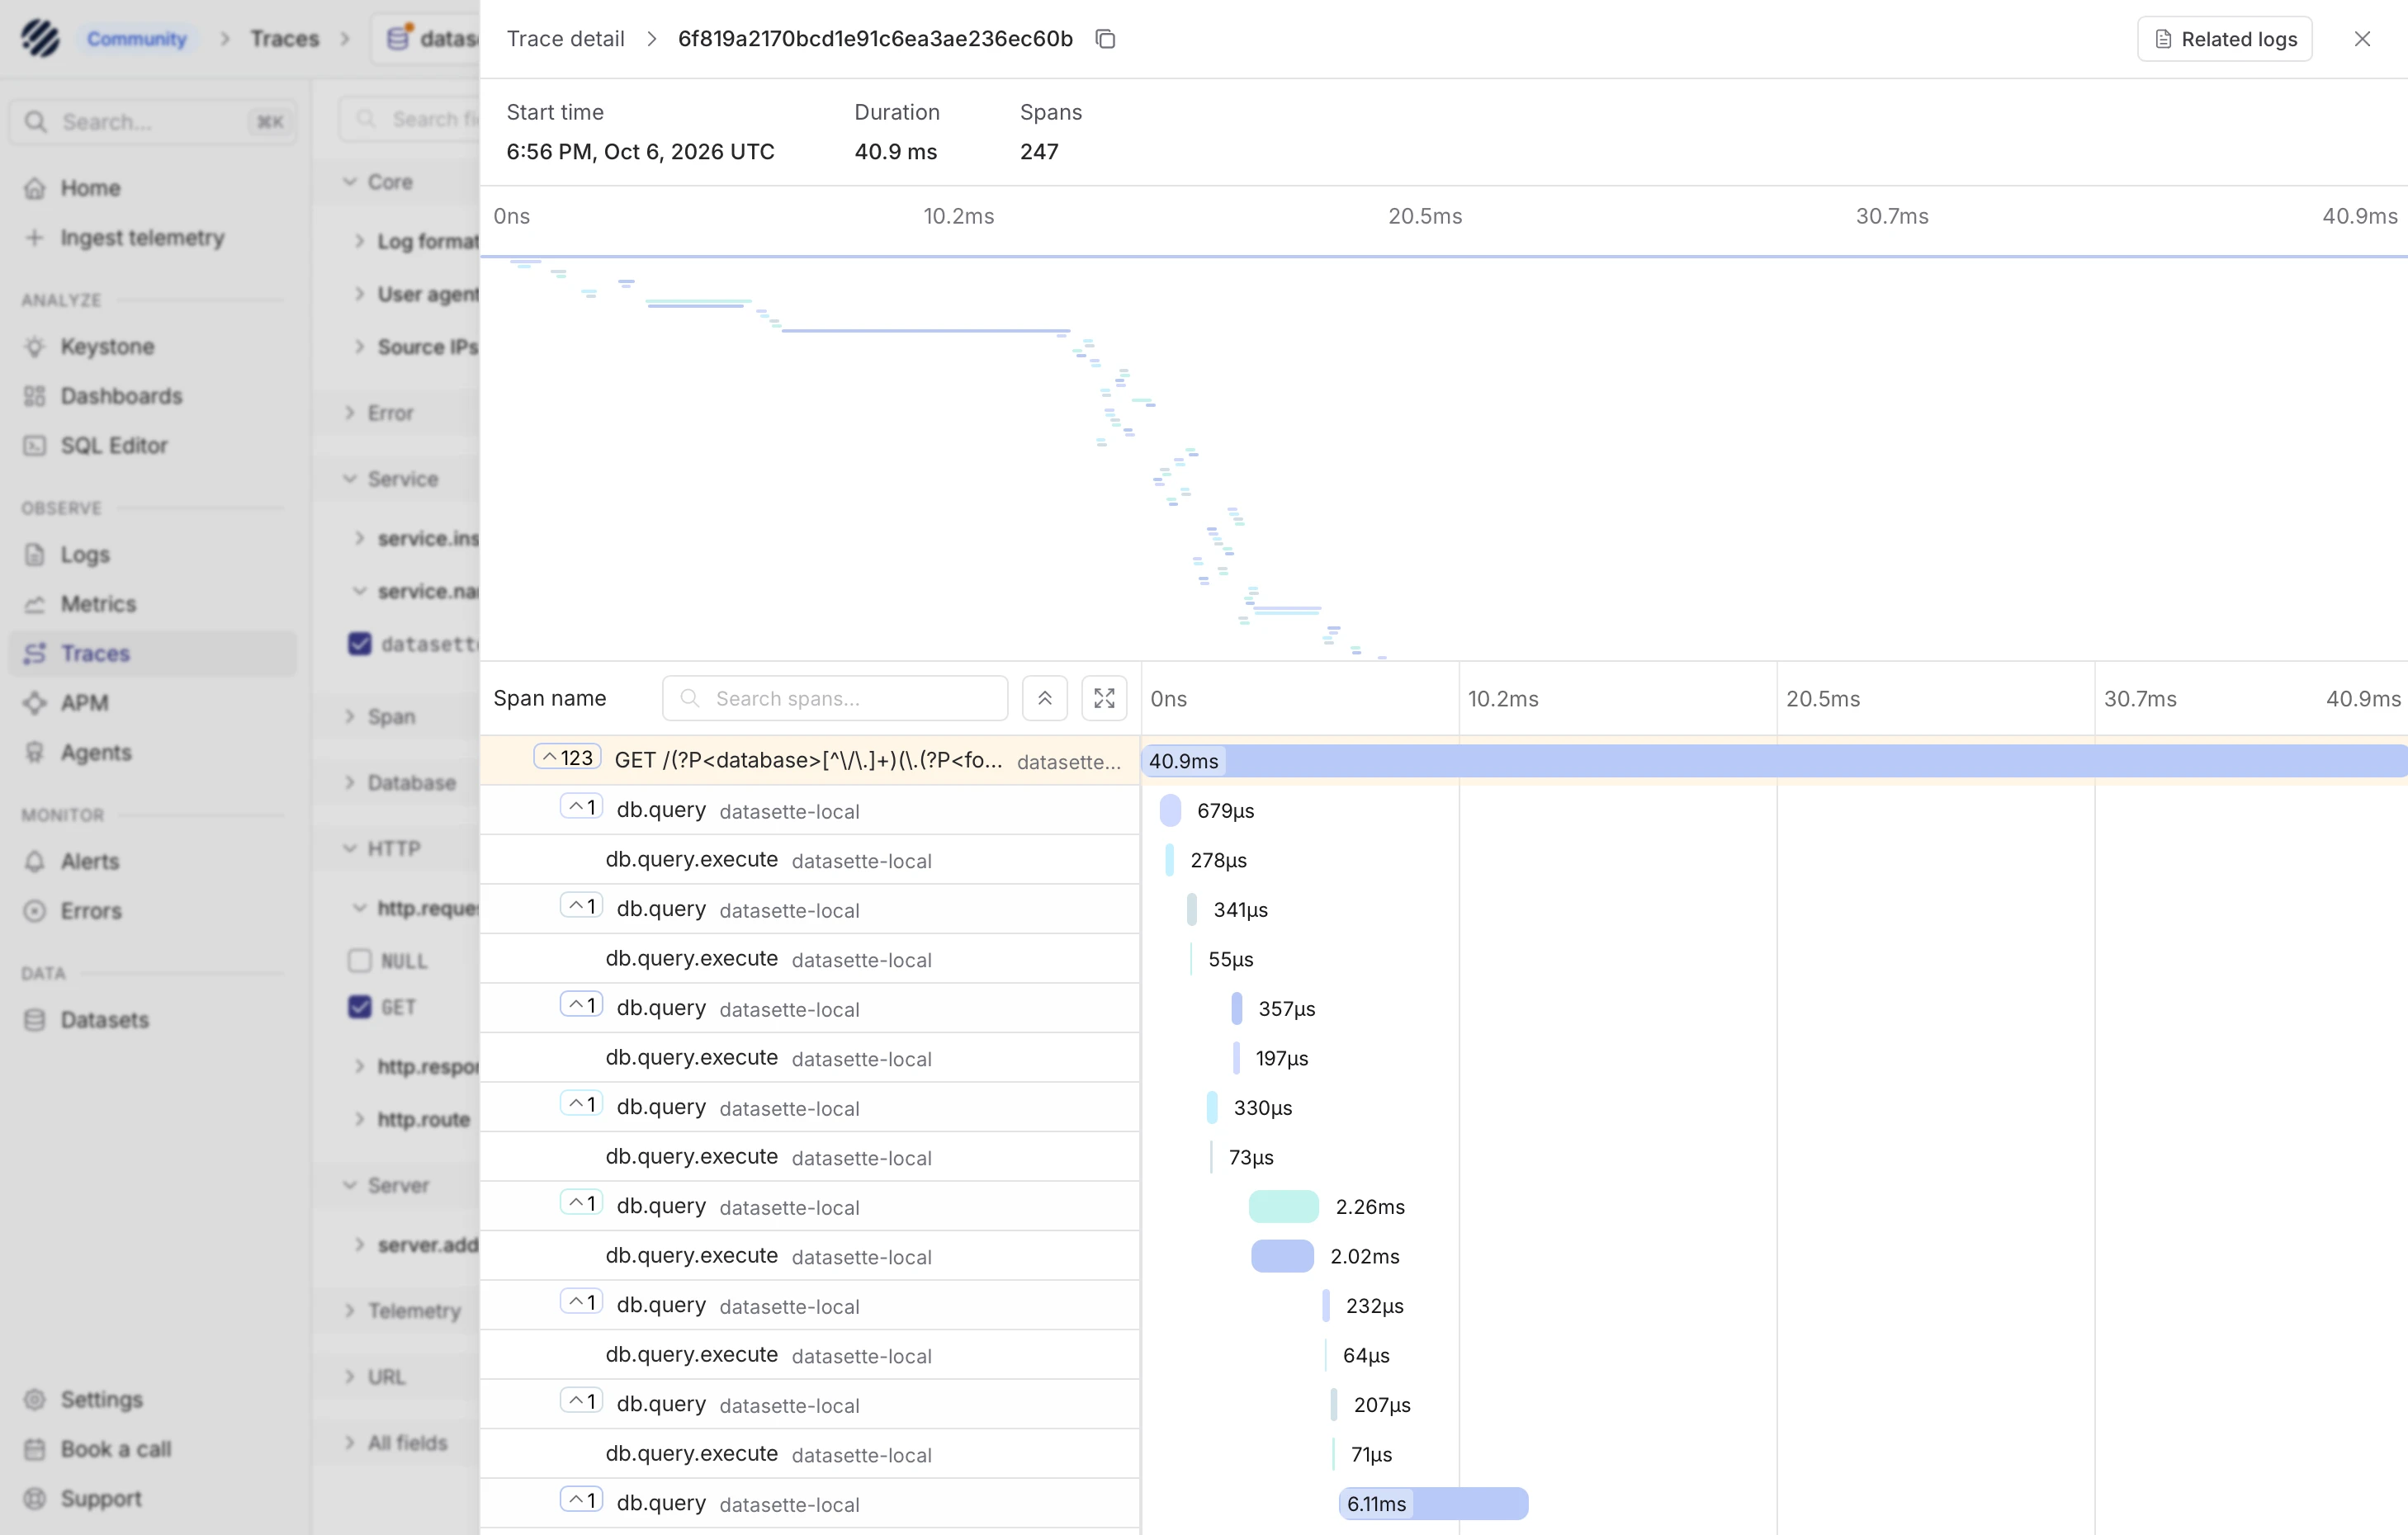
Since Datasette 1.0a41 added OpenTelemetry support (thanks, Alex Garcia), I decided to fire up Codex and have it figure out how to run Parseable and feed it traces from Datasette.
Here's my (human-written) TIL showing the patterns that worked, and here's a screenshot of a Datasette trace displayed within the Parseable localhost web application:
Comment My comment on Mistral Large 4 — Hacker News
wren6991: The benchmark is saturated. Frontier models are tested with an armadillo in fishnet tights jaywalking on Mars.
OK well I couldn't resist this one:
llm -m claude-opus-5.5 'Generate an SVG of an armadillo in fishnet tights jaywalking on Mars'
llm -m gpt-6.1-sol 'Generate an SVG of an armadillo in fishnet tights jaywalking on Mars'
llm -m gemini-3.8-flash 'Generate an SVG of an armadillo in fishnet tights jaywalking on Mars'
llm -m mistral/mistral-large-4 'Generate an SVG of an armadillo in fishnet tights jaywalking on Mars'
Default reasoning levels for each: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
Comment My comment on EmbeddingGemma 2 — Hacker News
I really appreciate that EmbeddingGemma 2 is under the Apache 2.0 license.
For embedding models in particular, I don't think it makes sense to use a closed, proprietary, hosted-only model.
Most applications of embedding models involve calculating thousands or even millions of embedding vectors and storing them for later comparison.
If your model is proprietary, the vendor is likely someday going to decide to stop offering that model. They'll have a better model to replace it, but you still need to pay to re-calculate those millions of stored existing vectors.
(In April 2024 OpenAI offered to "cover the financial cost of users re-embedding content with these new models" - https://openai.com/index/gpt-4-api-general-availability/ - but I don't think that's something we can rely on from every provider.)
Notably, I don't want to host the model myself. I'd much rather pay a provider for a hosted model while knowing that if they ever stop hosting it I can run the open weights version myself - or find another vendor who can do that for me.
# 8:37 pm / google, generative-ai, ai, gemma, embeddings