5 posts tagged “mistral” and “pelican-riding-a-bicycle”
Mistral AI release both openly licensed and API-hosted Language Models.
2026
Introducing Mistral Small 4. Big new release from Mistral today (despite the name) - a new Apache 2 licensed 119B parameter (Mixture-of-Experts, 6B active) model which they describe like this:
Mistral Small 4 is the first Mistral model to unify the capabilities of our flagship models, Magistral for reasoning, Pixtral for multimodal, and Devstral for agentic coding, into a single, versatile model.
It supports reasoning_effort="none" or reasoning_effort="high", with the latter providing "equivalent verbosity to previous Magistral models".
The new model is 242GB on Hugging Face.
I tried it out via the Mistral API using llm-mistral:
llm install llm-mistral
llm mistral refresh
llm -m mistral/mistral-small-2603 "Generate an SVG of a pelican riding a bicycle"
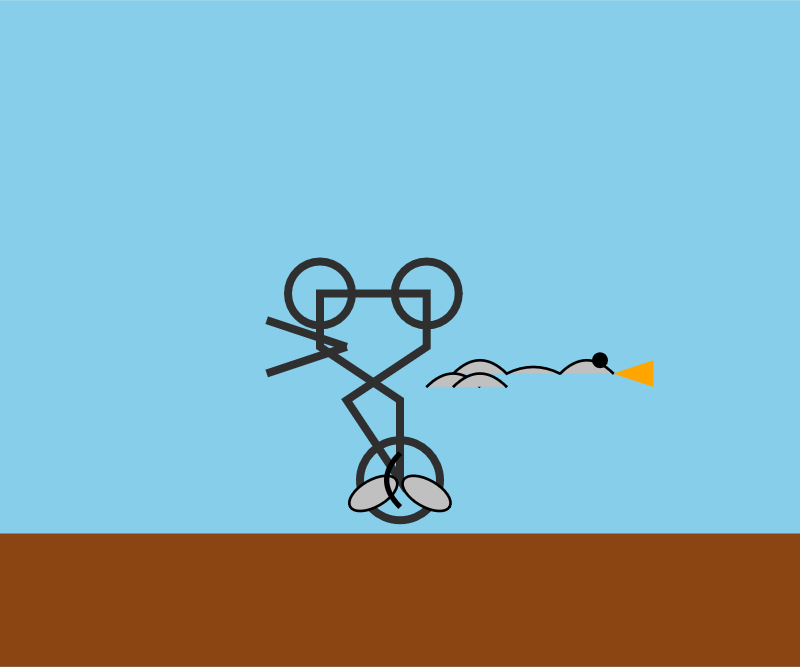
I couldn't find a way to set the reasoning effort in their API documentation, so hopefully that's a feature which will land soon.
Update 23rd March: Here's new documentation for the reasoning_effort parameter.
Also from Mistral today and fitting their -stral naming convention is Leanstral, an open weight model that is specifically tuned to help output the Lean 4 formally verifiable coding language. I haven't explored Lean at all so I have no way to credibly evaluate this, but it's interesting to see them target one specific language in this way.
2025
Devstral 2. Two new models from Mistral today: Devstral 2 and Devstral Small 2 - both focused on powering coding agents such as Mistral's newly released Mistral Vibe which I wrote about earlier today.
- Devstral 2: SOTA open model for code agents with a fraction of the parameters of its competitors and achieving 72.2% on SWE-bench Verified.
- Up to 7x more cost-efficient than Claude Sonnet at real-world tasks.
Devstral 2 is a 123B model released under a janky license - it's "modified MIT" where the modification is:
You are not authorized to exercise any rights under this license if the global consolidated monthly revenue of your company (or that of your employer) exceeds $20 million (or its equivalent in another currency) for the preceding month. This restriction in (b) applies to the Model and any derivatives, modifications, or combined works based on it, whether provided by Mistral AI or by a third party. [...]
Mistral Small 2 is under a proper Apache 2 license with no weird strings attached. It's a 24B model which is 51.6GB on Hugging Face and should quantize to significantly less.
I tried out the larger model via my llm-mistral plugin like this:
llm install llm-mistral
llm mistral refresh
llm -m mistral/devstral-2512 "Generate an SVG of a pelican riding a bicycle"
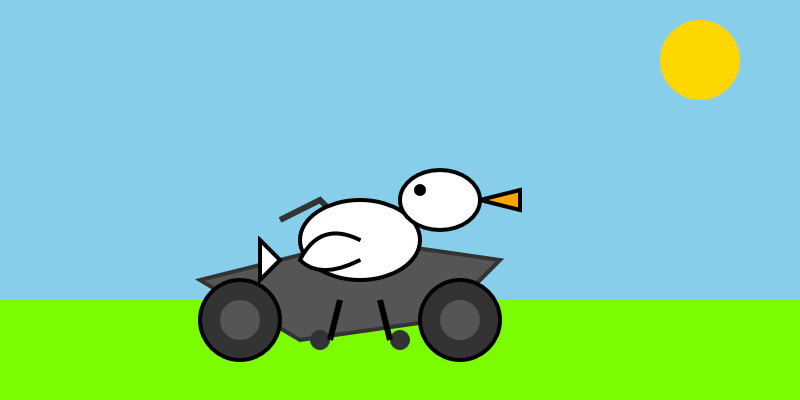
For a ~120B model that one is pretty good!
Here's the same prompt with -m mistral/labs-devstral-small-2512 for the API hosted version of Devstral Small 2:
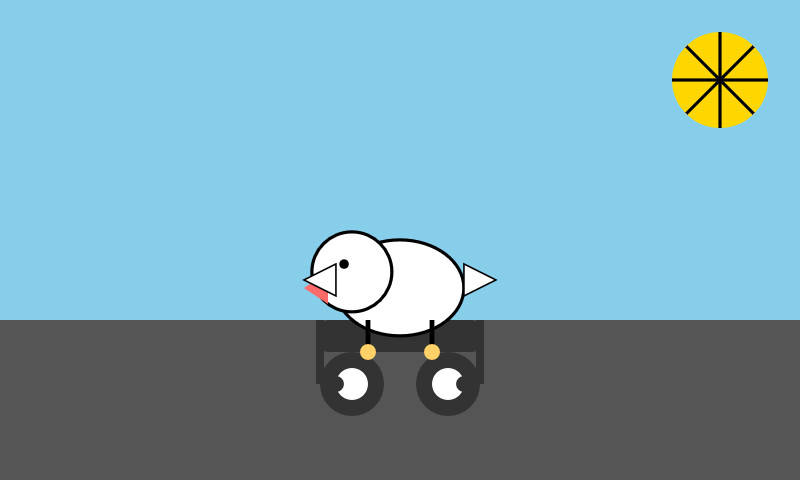
Again, a decent result given the small parameter size. For comparison, here's what I got for the 24B Mistral Small 3.2 earlier this year.
Mistral-Small 3.2. Released on Hugging Face a couple of hours ago, so far there aren't any quantizations to run it on a Mac but I'm sure those will emerge pretty quickly.
This is a minor bump to Mistral Small 3.1, one of my favorite local models. I've been running Small 3.1 via Ollama where it's a 15GB download - these 24 billion parameter models are a great balance between capabilities and not using up all of the available RAM on my laptop. I expect Ollama will add 3.2 imminently.
According to Mistral:
Small-3.2 improves in the following categories:
Interestingly they recommend running it with a temperature of 0.15 - many models recommend a default of 0.7. They also provide a suggested system prompt which includes a note that "Your knowledge base was last updated on 2023-10-01".
It's not currently available via Mistral's API, or through any of the third-party LLM hosting vendors that I've checked, so I've not been able to run a prompt through the model myself yet.
Update: I downloaded one of first GGUF quantizations to show up on Hugging Face, gabriellarson/Mistral-Small-3.2-24B-Instruct-2506-GGUF by Gabriel Larson. I ran it using Ollama and llm-ollama like this:
ollama pull hf.co/gabriellarson/Mistral-Small-3.2-24B-Instruct-2506-GGUF:Q4_K_M
llm install llm-ollama
llm -m hf.co/gabriellarson/Mistral-Small-3.2-24B-Instruct-2506-GGUF:Q4_K_M \
  "Generate an SVG of a pelican riding a bicycle"
This one is pretty good for a 15GB model!
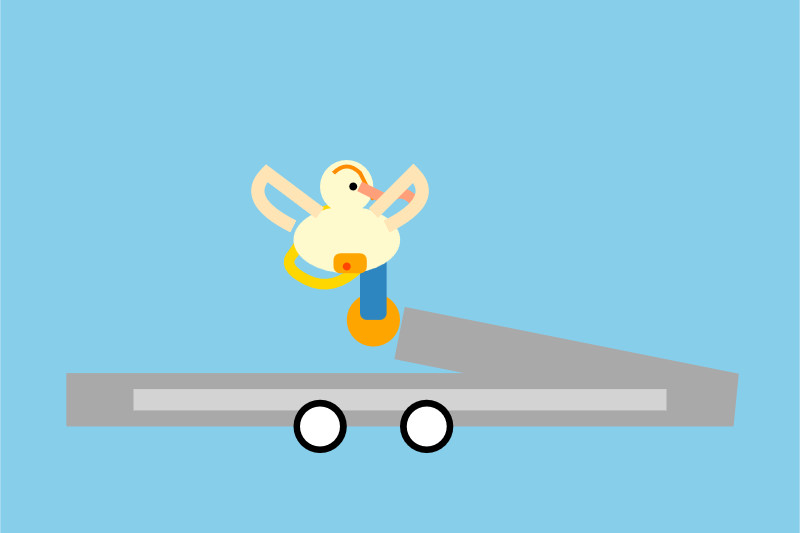
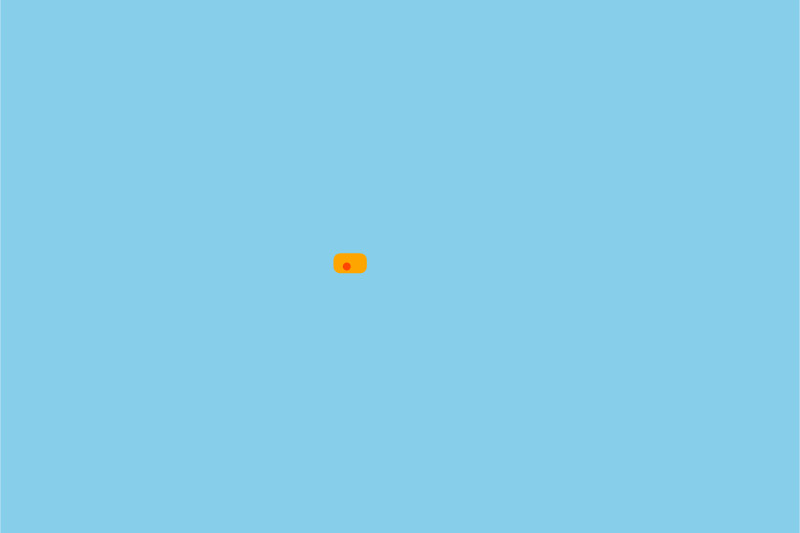
Here's the full transcript - it doesn't quite work in the actual image but I was delighted to see the model attempt to add this detail:
<!-- Basket with fish -->
<rect x="250" y="190" width="25" height="15" rx="5" fill="#FFA500"/>
<circle cx="260" cy="200" r="3" fill="#FF4500"/> <!-- Fish -->
Here's what you get if you isolate just that part of the generated SVG:
I had Mistral Small 3.2 describe the full image to me, since it's a vision-LLM:
llm -m hf.co/gabriellarson/Mistral-Small-3.2-24B-Instruct-2506-GGUF:Q4_K_M \
  'describe image' \
  -a https://static.simonwillison.net/static/2025/mistral-3.2-pelican.jpg
And it gave me the following:
The image depicts a cartoonish illustration of a duck that is being lifted off the ground by a hook. The duck appears to be in mid-air, with its wings spread slightly as if it's surprised or reacting to being picked up. The hook is attached to an arm or a mechanism and seems to be connected to a vehicle below—perhaps a truck or a platform with wheels. The background of the image is light blue, indicating an outdoor setting. Overall, the scene is whimsical and playful, possibly suggesting a humorous or unusual situation where the duck is being transported in this manner.
Update 2: It's now available as an official Ollama model:
ollama pull mistral-small3.2
LM Studio has a community quantization too: lmstudio-community/Mistral-Small-3.2-24B-Instruct-2506-GGUF.
Magistral — the first reasoning model by Mistral AI. Mistral's first reasoning model is out today, in two sizes. There's a 24B Apache 2 licensed open-weights model called Magistral Small (actually Magistral-Small-2506), and a larger API-only model called Magistral Medium.
Magistral Small is available as mistralai/Magistral-Small-2506 on Hugging Face. From that model card:
Context Window: A 128k context window, but performance might degrade past 40k. Hence we recommend setting the maximum model length to 40k.
Mistral also released an official GGUF version, Magistral-Small-2506_gguf, which I ran successfully using Ollama like this:
ollama pull hf.co/mistralai/Magistral-Small-2506_gguf:Q8_0
That fetched a 25GB file. I ran prompts using a chat session with llm-ollama like this:
llm chat -m hf.co/mistralai/Magistral-Small-2506_gguf:Q8_0
Here's what I got for "Generate an SVG of a pelican riding a bicycle" (transcript here):
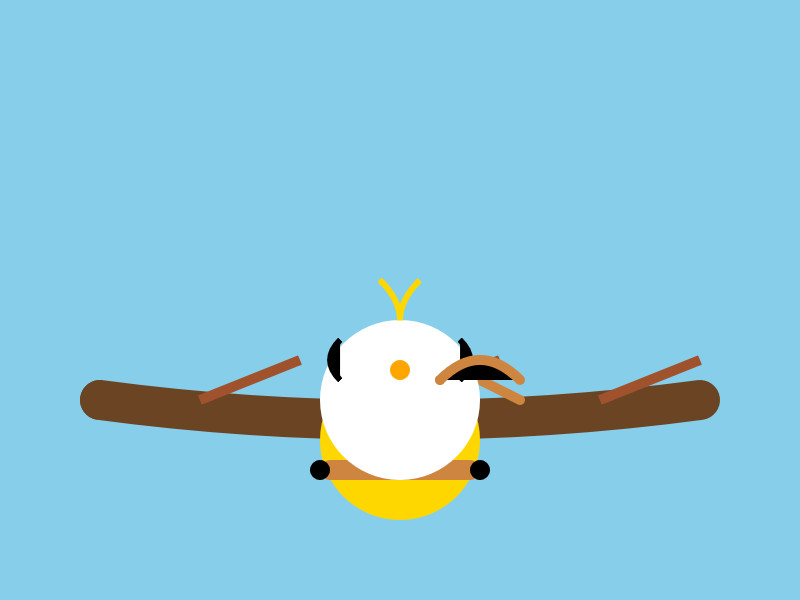
It's disappointing that the GGUF doesn't support function calling yet - hopefully a community variant can add that, it's one of the best ways I know of to unlock the potential of these reasoning models.
I just noticed that Ollama have their own Magistral model too, which can be accessed using:
ollama pull magistral:latest
That gets you a 14GB q4_K_M quantization - other options can be found in the full list of Ollama magistral tags.
One thing that caught my eye in the Magistral announcement:
Legal, finance, healthcare, and government professionals get traceable reasoning that meets compliance requirements. Every conclusion can be traced back through its logical steps, providing auditability for high-stakes environments with domain-specialized AI.
I guess this means the reasoning traces are fully visible and not redacted in any way - interesting to see Mistral trying to turn that into a feature that's attractive to the business clients they are most interested in appealing to.
Also from that announcement:
Our early tests indicated that Magistral is an excellent creative companion. We highly recommend it for creative writing and storytelling, with the model capable of producing coherent or — if needed — delightfully eccentric copy.
I haven't seen a reasoning model promoted for creative writing in this way before.
You can try out Magistral Medium by selecting the new "Thinking" option in Mistral's Le Chat.
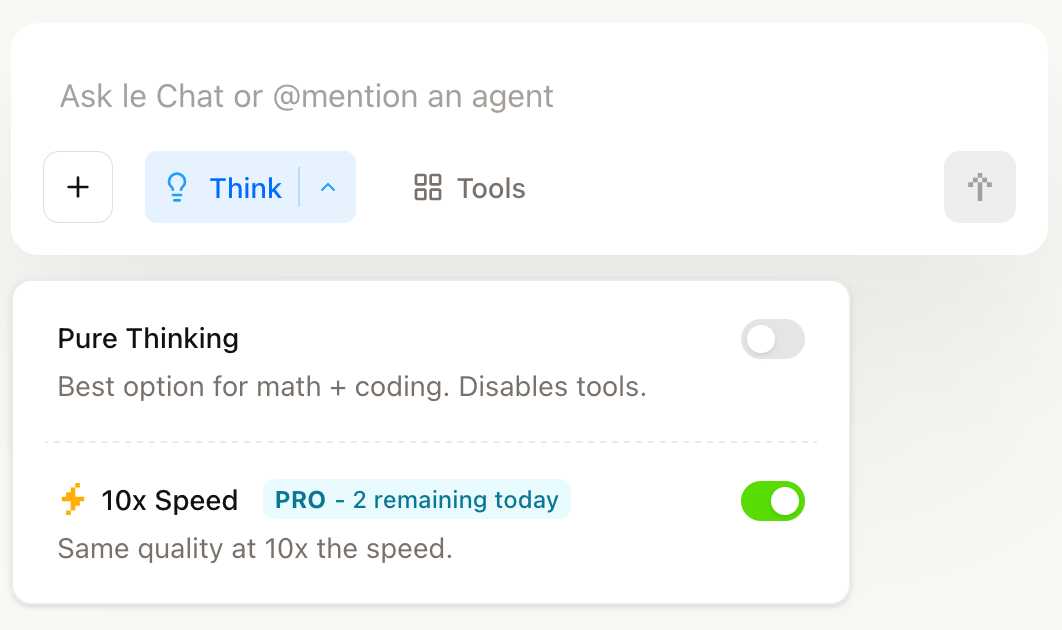
They have options for "Pure Thinking" and a separate option for "10x speed", which runs Magistral Medium at 10x the speed using Cerebras.
The new models are also available through the Mistral API. You can access them by installing llm-mistral and running llm mistral refresh to refresh the list of available models, then:
llm -m mistral/magistral-medium-latest \
  'Generate an SVG of a pelican riding a bicycle'
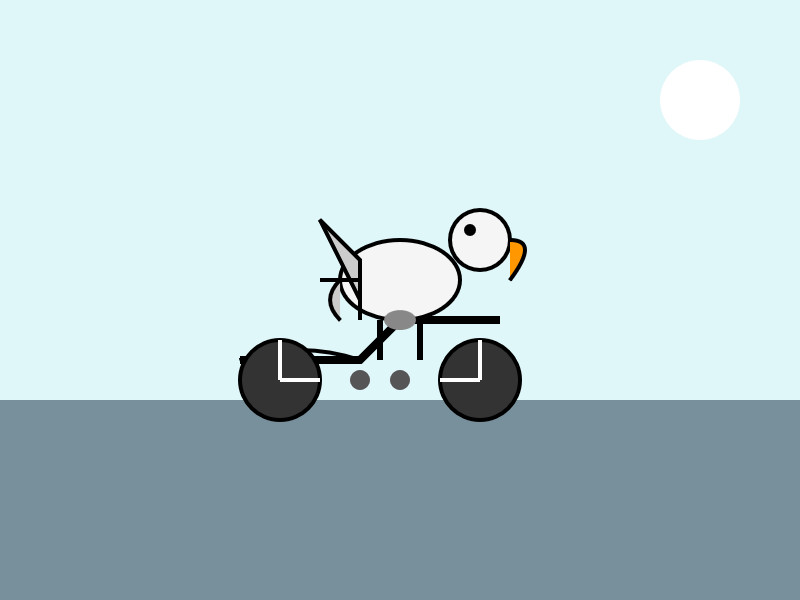
Here's that transcript. At 13 input and 1,236 output tokens that cost me 0.62 cents - just over half a cent.
The last six months in LLMs, illustrated by pelicans on bicycles
I presented an invited keynote at the AI Engineer World’s Fair in San Francisco this week. This is my third time speaking at the event—here are my talks from October 2023 and June 2024. My topic this time was “The last six months in LLMs”—originally planned as the last year, but so much has happened that I had to reduce my scope!
[... 6,077 words]