16th March 2025 - Link Blog
mlx-community/OLMo-2-0325-32B-Instruct-4bit (via) OLMo 2 32B claims to be "the first fully-open model (all data, code, weights, and details are freely available) to outperform GPT3.5-Turbo and GPT-4o mini". Thanks to the MLX project here's a recipe that worked for me to run it on my Mac, via my llm-mlx plugin.
To install the model:
llm install llm-mlx
llm mlx download-model mlx-community/OLMo-2-0325-32B-Instruct-4bit
That downloads 17GB to ~/.cache/huggingface/hub/models--mlx-community--OLMo-2-0325-32B-Instruct-4bit.
To start an interactive chat with OLMo 2:
llm chat -m mlx-community/OLMo-2-0325-32B-Instruct-4bit
Or to run a prompt:
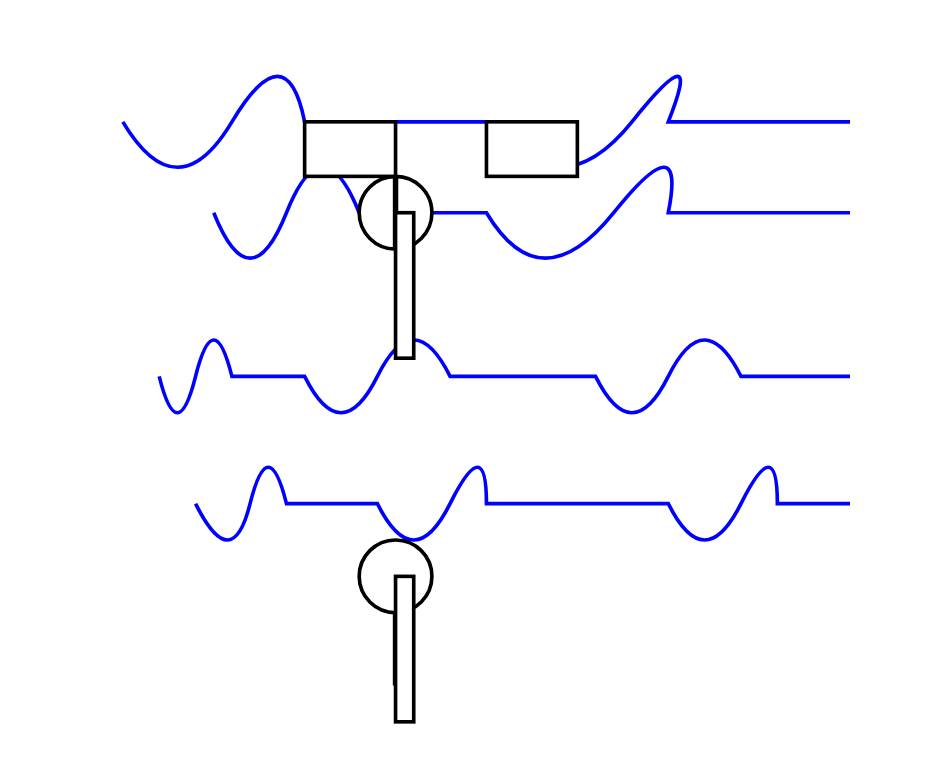
llm -m mlx-community/OLMo-2-0325-32B-Instruct-4bit 'Generate an SVG of a pelican riding a bicycle' -o unlimited 1
The -o unlimited 1 removes the cap on the number of output tokens - the default for llm-mlx is 1024 which isn't enough to attempt to draw a pelican.
The pelican it drew is refreshingly abstract:
Recent articles
- Running the full server-side Datasette Python app in the browser with service workers and Pyodide - 17th November 2026
- Locating the source of a mysterious beep with Claude - 9th November 2026
- Hide your slop PR descriptions behind <details><summary> - 9th November 2026
- Qwen 3.8 27B on my laptop can interpret model weights, too - 3rd November 2026