| Gemini Decisions API |
https://blog.google/innovation-and-ai/technology/developers-tools/gemini-decisions-api/ |
Google join [Jev](https://simonwillison.net/2026/Sep/21/jev/) and [OpenAI](https://simonwillison.net/2026/Oct/6/llm-openai-decisions/) in the decision model category with "Gemini Decision 1". This new model API is almost identical to Jev: it supports the same three types of questions (yes/no, choice, and rubric-scoring) and even reuses Jev's term "Noul" for a yes/no question.
It's priced the same as the GPT-6 Luna decision model: 10 cents per million input tokens, and output is free. Jev remains the cheapest of the three, at 4.2 cents per million.
Jev is text (and JSON) only. OpenAI can handle text and images. Gemini Decision 1 is fully multi-model: it covers text, images, audio, video, and PDFs.
I tested it against video by passing these questions to it along with my [Yonkers stomping robot](https://simonwillison.net/2026/Nov/10/yonkers-rises/) video file:
dragon: Does this video have a dragon in it?
robot: Does this video have a robot in it?
france: Is this video set in France?
usa: Is this video set in the USA?
Jev and OpenAI both return 1.0 or 0.0 for yes/no questions, but Gemini insists on being a little less confident than that:
<div class="highlight highlight-source-json"><pre>{
<span class="pl-ent">"dragon"</span>: {
<span class="pl-ent">"type"</span>: <span class="pl-s"><span class="pl-pds">"</span>yes_no<span class="pl-pds">"</span></span>,
<span class="pl-ent">"probability"</span>: <span class="pl-c1">0.04976021841520312</span>
},
<span class="pl-ent">"robot"</span>: {
<span class="pl-ent">"type"</span>: <span class="pl-s"><span class="pl-pds">"</span>yes_no<span class="pl-pds">"</span></span>,
<span class="pl-ent">"probability"</span>: <span class="pl-c1">0.9234055387792485</span>
},
<span class="pl-ent">"france"</span>: {
<span class="pl-ent">"type"</span>: <span class="pl-s"><span class="pl-pds">"</span>yes_no<span class="pl-pds">"</span></span>,
<span class="pl-ent">"probability"</span>: <span class="pl-c1">0.08329171353166241</span>
},
<span class="pl-ent">"usa"</span>: {
<span class="pl-ent">"type"</span>: <span class="pl-s"><span class="pl-pds">"</span>yes_no<span class="pl-pds">"</span></span>,
<span class="pl-ent">"probability"</span>: <span class="pl-c1">0.9230459995157706</span>
}
}</pre></div> |
2026-11-11 22:03:25+00:00 |
| aws-emulator |
https://github.com/aws/aws-emulator |
Finally, an official emulator from AWS to run tests against a local clone of their many different services without having to provision a paid API key to do so.
It's written in Rust by a huge swarm of agents - 29,684 commits in the first three weeks of the project. Swaminathan (Swami) Sivasubramanian wrote about [how it came to be](https://www.allthingsdistributed.com/2026/11/aws-emulator-and-the-engineers-job-when-agents-write-the-code.html) in a guest post on Werner Vogels' blog.
It currently requires Docker to run on macOS or Windows. I'm hoping they fix that in the future - it would be great if you could download a single binary and use that as part of a standard test suite in other languages and on other platforms. |
2026-11-11 21:18:30+00:00 |
| Browse tools.simonwillison.net by tag |
https://tools.simonwillison.net/#tags |
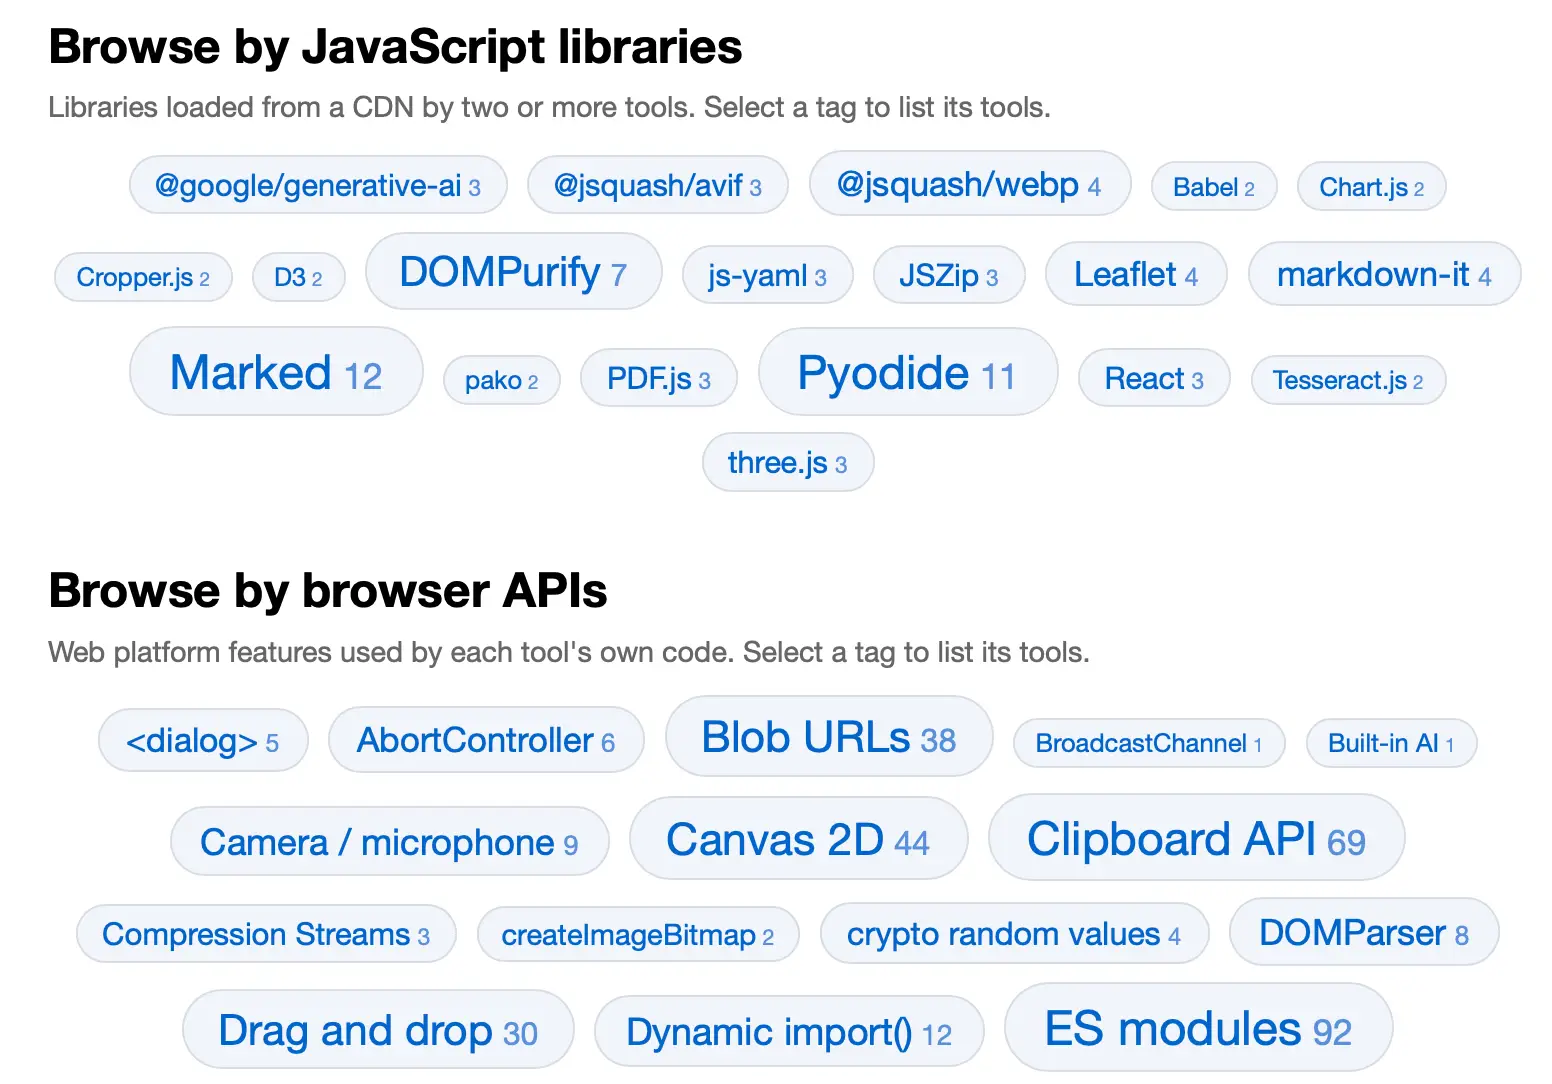
I've been wanting a better way to browse my [collection of vibe-coded tools]() (244 and counting) for a while. I had a few Fable 5.2 credits left over before my weekly reset so I set it to work using [tree-sitter](https://github.com/tree-sitter/py-tree-sitter) to analyze the code for JavaScript APIs, libraries, and web API hosts used by each tool.
The homepage now features tag clouds for browsing by each of those categories of tag:
[](https://tools.simonwillison.net/#tags) |
2026-11-11 18:42:50+00:00 |
| Anthropic's IPO roadshow video |
https://ipo.anthropic.com/us/#roadshow-video |
Anthropic kicked off their IPO roadshow yesterday, and their roadshow video has some previously unreleased information about how their business works.
The section on "Approach to compute" with co-founder Tom Brown is particularly interesting, describing how Anthropic train and serve Claude across AWS Trainium, Google TPUs, NVIDIA GPUs, and AMD GPUs.
I'm not sure why there's no official video transcript, but here's [one that I extracted](https://gist.github.com/simonw/9806757fe8acec6221cb0a5cce4d720d) using MacWhisper. Highlights below:
> We train and serve Claude now across all four major chip families. That's only possible because early on we made an unconventional bet on a multi-chip strategy. At the time, many people thought that running AI models on different chips wasn't worth the effort. Each chip needs its own tailored software stack and inference stack, which is expensive and difficult to build. We've now been doing it for years, and we've gotten incredibly good at it. [...]
>
> As an example, this year, we started working with AMD GPUs for the first time. In the past, bringing on a new chip platform took dozens of engineers months of work **This time, we had Mythos try it out. It got Claude running on AMD in just three days, with basically no human intervention**. Claude ported or wrote almost 100% of the kernels. [...]
>
> The second driver of our compute advantage is our rate of discovery of compute multipliers. We focus on total effective compute, which is the multiplicative product of physical capacity times the compute multipliers that we discover. Each one we discover makes our pool of total effective compute bigger. For example, say you need 100 units of compute to train a model of a certain intelligence. A 4x compute multiplier means you can use 25 units of compute to train the exact same model. Or you can use those hundred physical units to train an even more intelligent model that would have previously required 400 units.
>
> Compute multipliers create a competitive advantage for us that's hard to replicate. They build on each other. Each new multiplier we discover has a positive effect on the multipliers before it. They stack. **We believe that this can accelerate even further as we approach recursive self-improvement. Claude will be able to discover compute multipliers entirely by itself**, allowing the number of compute multipliers to grow faster and faster.
We got a hint at Anthropic's multi-chip strategy last September in their [postmortem of three recent issues](https://www.anthropic.com/research/a-postmortem-of-three-recent-issues), where they described bugs that affected just their TPU deployments. |
2026-11-11 15:11:59+00:00 |
| Introducing Our Smallest, Most Efficient Model: Muse Ember |
https://research.meta.ai/blog/muse-ember |
Meta AI just launched their entry in the Claude Haiku/GPT Luna category: Muse Ember, which they describe as:
> [...] our smallest and most efficient model designed for complex reasoning execution and the work agents repeat all day: tool calls, coding subtasks, routing, extraction, and long document parsing.
For shorter prompts it's priced the same as GPT-6 Luna and Claude Haiku 5.5 - both are $0.10/million input tokens and $0.50/million output. Today's other big model release, Claude Fable 5.2, is *80x that price* at $8/$40.
The pricing is a little less straightforward as prompts get longer, though. Luna, Ember, and Haiku all support up to a million input tokens, but they also all have a threshold after which the price goes up. Taking *that* threshold into account Ember is priced between the two others:
<center><table>
<thead>
<tr>
<th>Model</th>
<th>Prompt size</th>
<th>Input ($/M)</th>
<th>Cached input</th>
<th>Output</th>
</tr>
</thead>
<tbody>
<tr>
<td rowspan="2">GPT-6 Luna</td>
<td>≤272k</td>
<td>$0.10</td>
<td>$0.01</td>
<td>$0.50</td>
</tr>
<tr>
<td>>272k</td>
<td>$0.20</td>
<td>$0.02</td>
<td>$0.75</td>
</tr>
<tr>
<td rowspan="2">Muse Ember 1.0</td>
<td>≤200k</td>
<td>$0.10</td>
<td>$0.004</td>
<td>$0.50</td>
</tr>
<tr>
<td>>200k</td>
<td>$0.30</td>
<td>$0.012</td>
<td>$1.50</td>
</tr>
<tr>
<td rowspan="2">Claude Haiku 5.5</td>
<td>≤100k</td>
<td>$0.10</td>
<td>$0.01</td>
<td>$0.50</td>
</tr>
<tr>
<td>>100k</td>
<td>$0.50</td>
<td>$0.05</td>
<td>$2.50</td>
</tr>
</tbody>
</table></center>
But comparing price-per-token doesn't really make sense these days, when reasoning tokens mean that different models might use dramatically different numbers of tokens to solve the same problem.
For that, one measure that's useful is the Artificial Analysis.
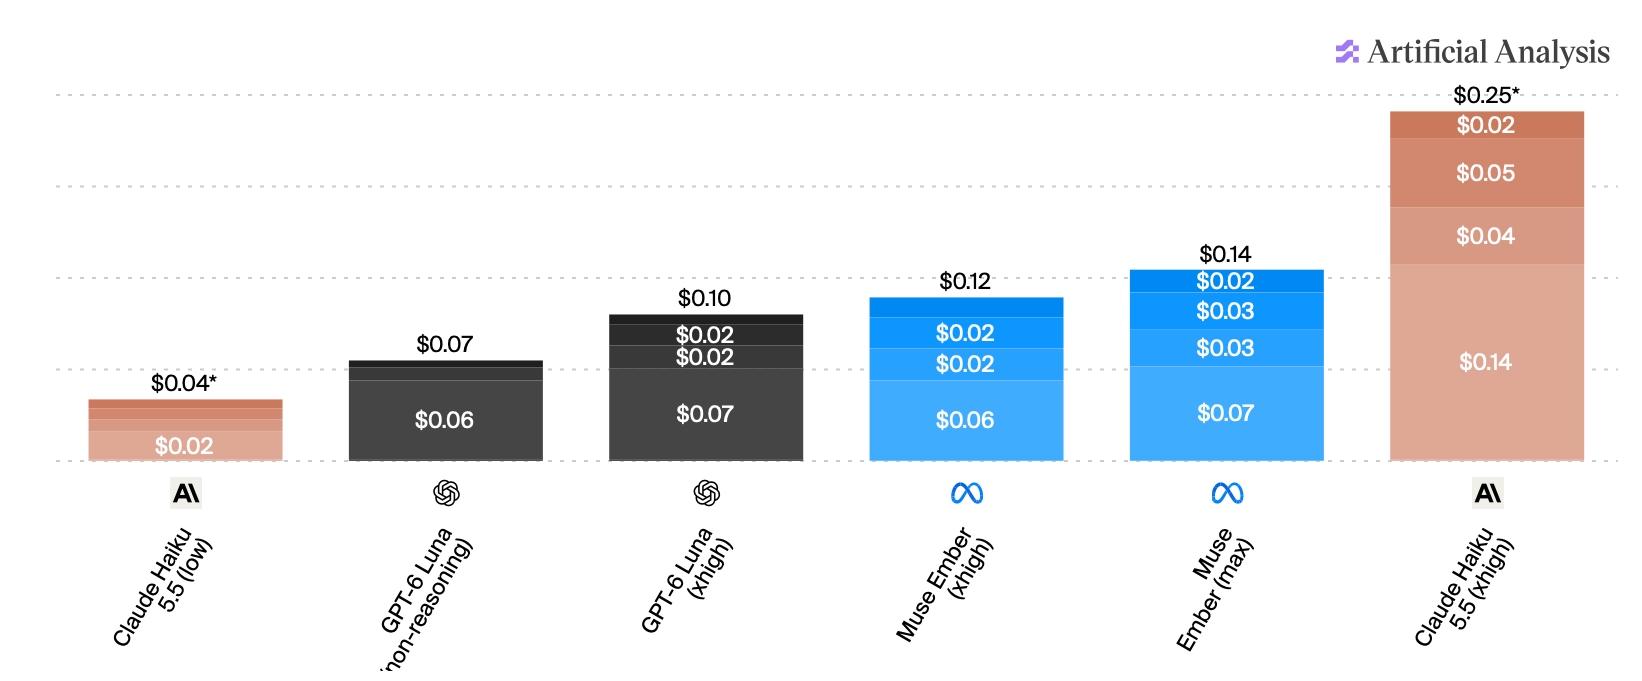
And even more useful than that is their Intelligence Index vs. Cost per Task chart, which shows the following for those three models:
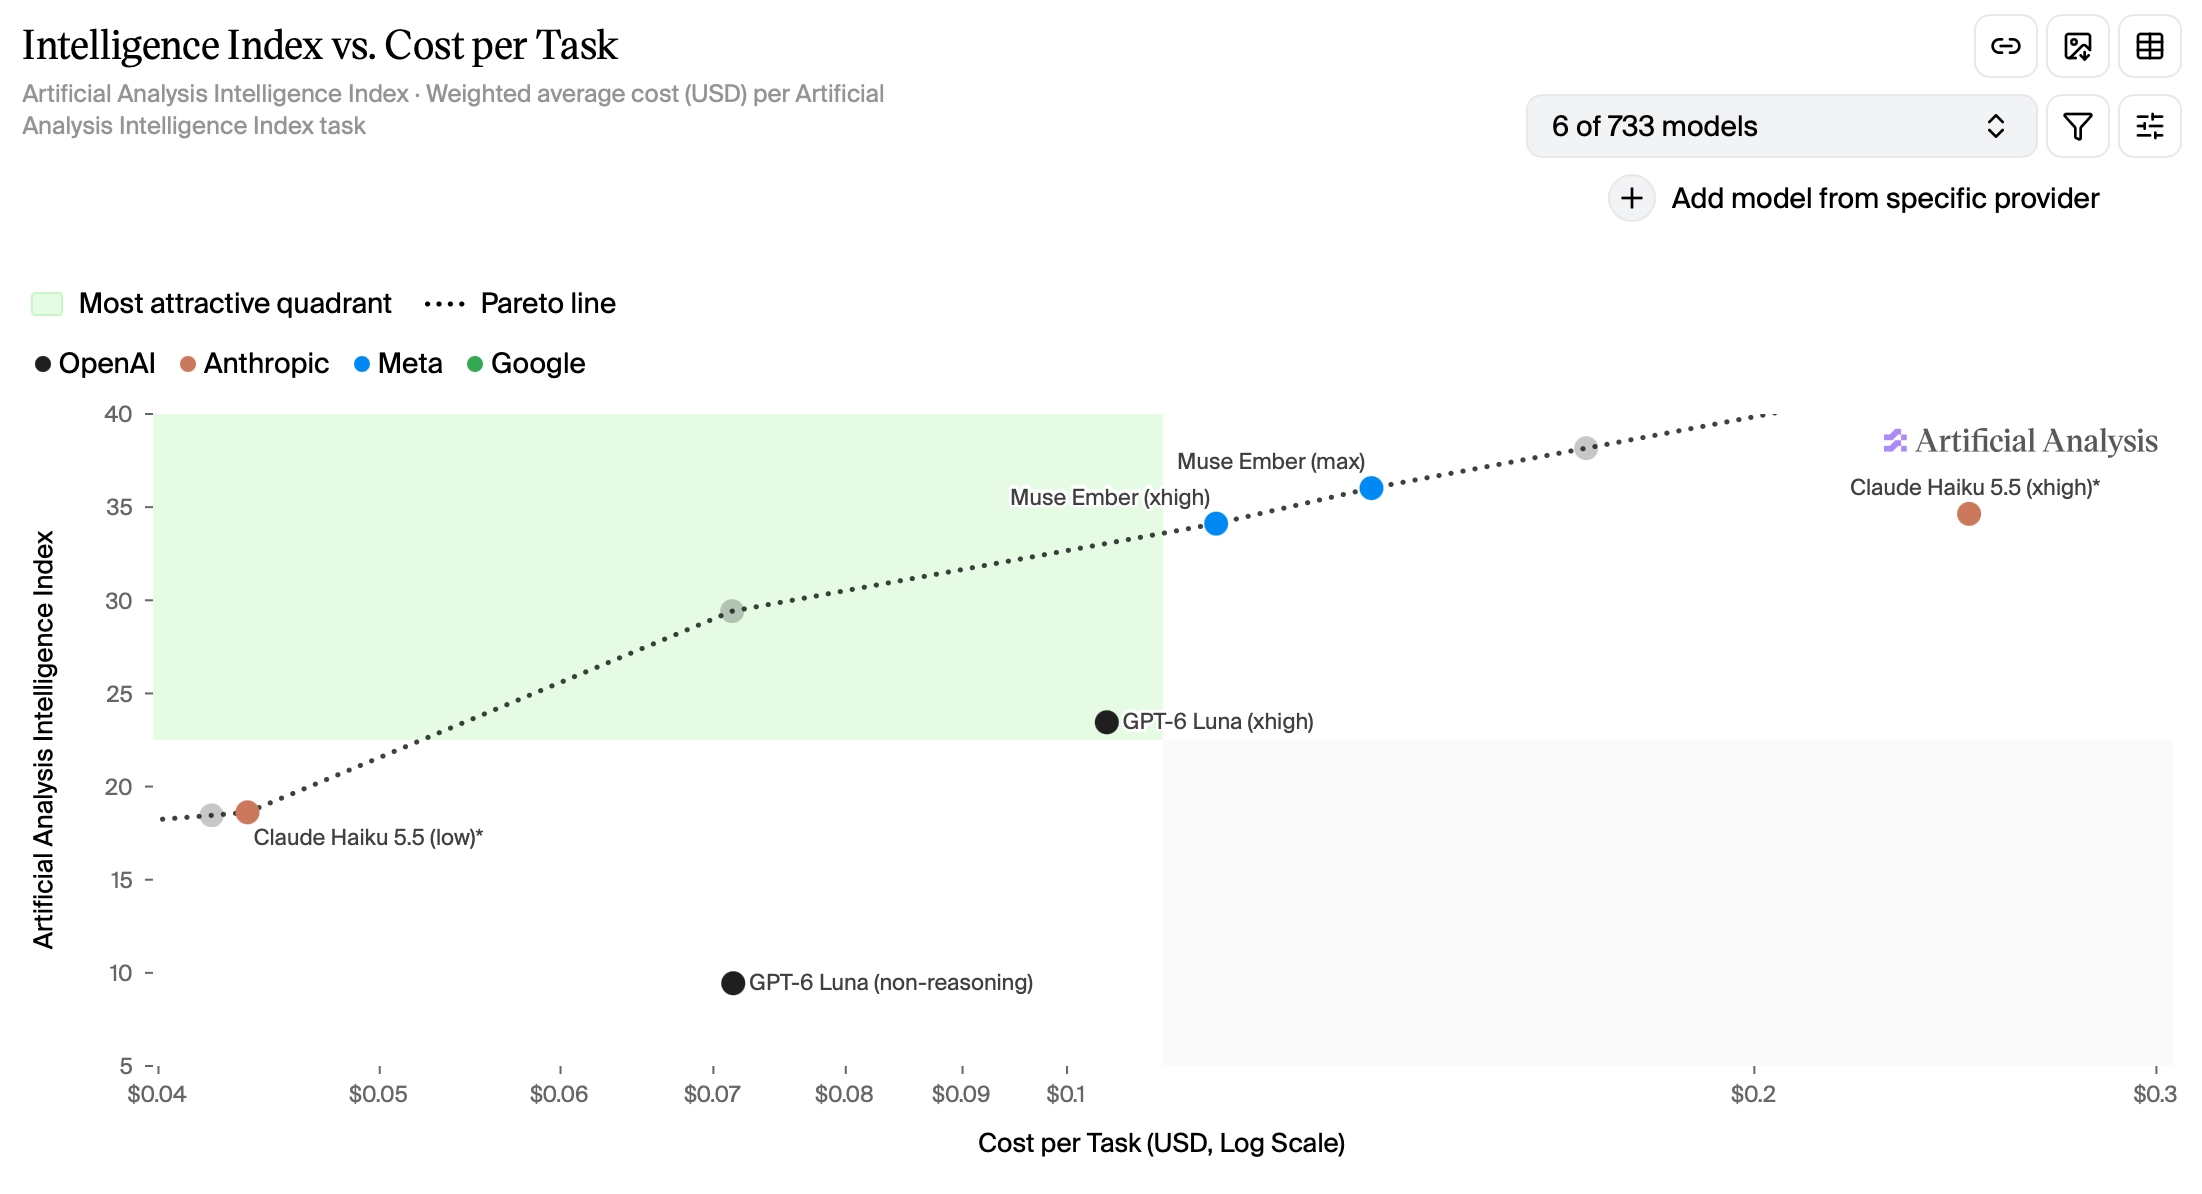
The Muse Ember models sit right on that Pareto line - the line at which you can only improve one dimension by giving up another. Meta call this out in their announcement:
> It also sits on the efficiency frontier of the full Artificial Analysis leaderboard: no model scores higher for less per task.
(That grey dot on the Pareto line in the middle of the green area is GPT-6.1 Terra (low) - clearly I should be paying more attention to the Terra family!)
Muse Ember has six reasoning levels - minimal, low, medium, high, xhigh, and max - so I [rendered six pelicans riding bicycles](https://tools.simonwillison.net/markdown-svg-renderer?url=https%3A%2F%2Fgist.github.com%2Fsimonw%2Fc7666e8a54d84f724ac8121f9fa6cc4d). The "high" reasoning level failed to return a full SVG, and the other SVGs were surprising in that the reasoning level didn't cleanly map to the visual quality of the response.
Here's the "max" one, but the others are worth a look too:
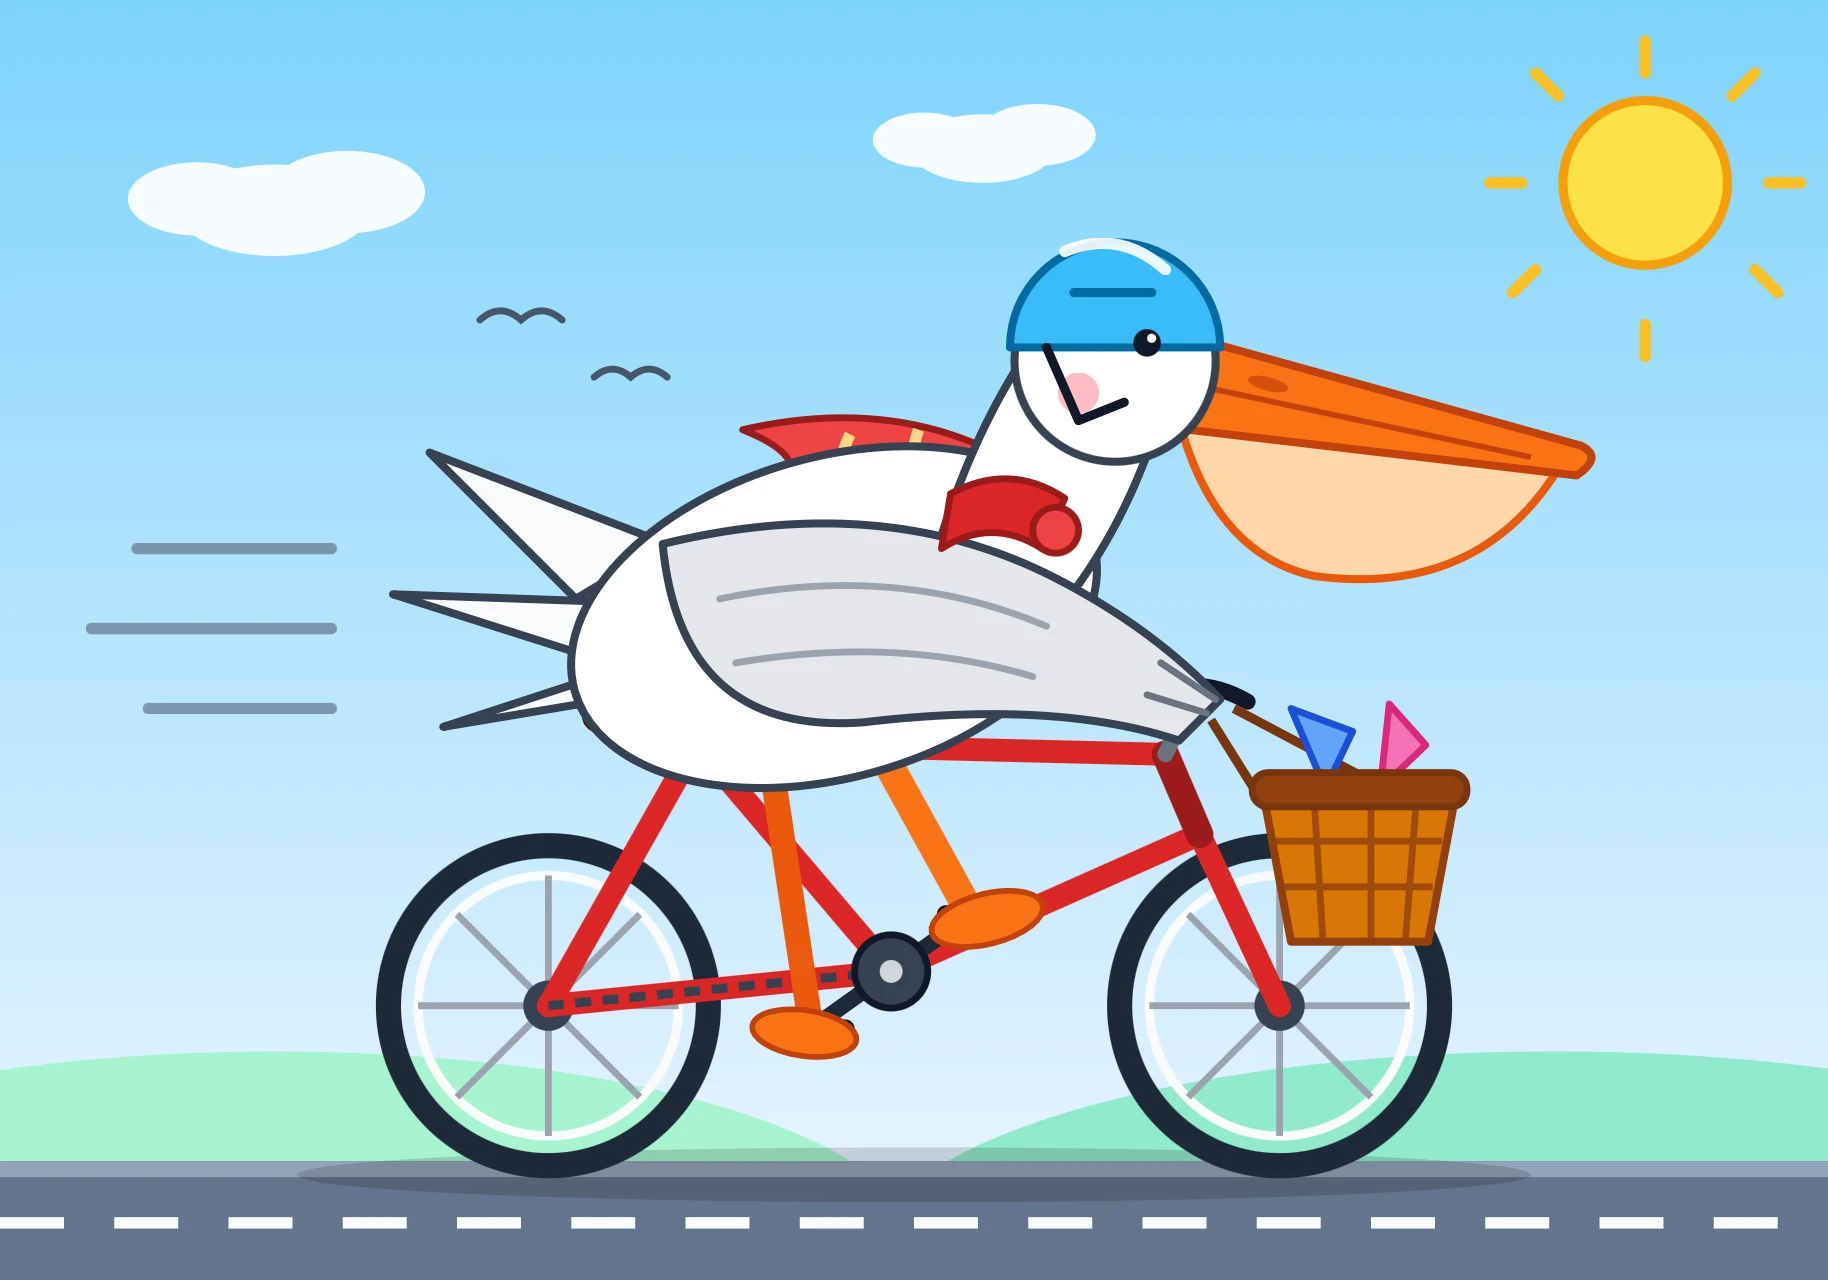
The Ember pelicans are comparable in quality to those [I got from Muse Wonder](https://tools.simonwillison.net/markdown-svg-renderer?url=https://gist.github.com/simonw/185cff7ff0b11379725abf7f78d5d2b2), which is [40x the price](https://www.llm-prices.com/#sel=muse-ember-1.0%2Cmuse-ember-1.0-200k%2Cmuse-wonder-1.0) of Muse Ember. |
2026-11-10 07:28:21+00:00 |
| datasette #3046: Don't serve link: rel=next HTTP headers to Firefox for HTML pages |
https://github.com/simonw/datasette/issues/3046 |
I was looking at the Firefox network panel today when I noticed that requests to a Datasette table page were triggering an [HTTP prefetch](https://developer.mozilla.org/en-US/docs/Glossary/Prefetch) to the next page of rows in that table.
This was happening because Datasette pages serve an HTTP `link` header like this:
`link: <https://latest.datasette.io/fixtures/compound_three_primary_keys?_next=a%2Cd%2Cv>; rel="next"`
This is bad. A tiny fraction of the visitors to one of those pages will click the "next" link, which means for everyone else their browser is fetching unnecessary data and the Datasette server is having to render an entire page that then gets thrown away.
I dug in and learned that Firefox has [an issue](https://bugzilla.mozilla.org/show_bug.cgi?id=175418) that has been open for 24 years about this behavior...
And one of the early comments on that issue links to [my blog post from 2002](https://simonwillison.net/2002/Oct/17/mozillaPrefetching/) complaining about this feature. I hadn't just forgotten that I had written about it, I had forgotten the feature entirely! |
2026-11-07 23:57:46+00:00 |
| Independent Assessment of AI R&D Acceleration at Anthropic in October 2026 |
https://metr.org/blog/2026-11-05-anthropic-ai-rd-acceleration-assessment/ |
... |
2026-11-06 21:43:36+00:00 |
| I discovered a sound that leaks your exact location (and it's everywhere) - YouTube |
https://www.youtube.com/watch?v=UytYrhYLOKI |
Genius piece of OSINT by Colsto, who demonstrates how you can take almost imperceptible background noise of planes from a video soundtrack, figure out their Doppler curves, then cross reference them against ADS-B data to find the exact location of the video based on their speed, distance, and gaps between different flights.
<p><lite-youtube videoid="UytYrhYLOKI" js-api="js-api"
title="I discovered a sound that leaks your exact location (and it's everywhere)"
playlabel="Play: I discovered a sound that leaks your exact location (and it's everywhere)"
> </lite-youtube></p> |
2026-11-03 05:32:25+00:00 |
| How We Took Over ChatGPT Accounts |
https://www.parameter.ai/labs/we-found-a-gap-at-openai |
Parameter Labs describe an exploit they found against ChatGPT's implementation of the artifacts pattern (OpenAI used to call this "Canvas" but it looks like the latest revision is called [HTML previews](https://help.openai.com/en/articles/20001246-working-with-writing-blocks-and-code-blocks-in-chatgpt)), where interactive custom HTML apps are displayed in a sandboxed iframe.
It's important that HTML in these stays tightly sandboxed to avoid untrusted code interacting with OpenAI APIs and accessing private data.
Parameter found quite a complex attack chain. OpenAI use the MathLive JavaScript library as part of their graph support, and that library includes [its own virtual keyboard](https://mathlive.io/mathfield/virtual-keyboard/), which can be triggered in the parent page via `postMessage()` from the sandboxed iframe.
That message receiving code uses `innerHTML`, so anything that sends a message can add custom HTML to the parent - and there was no mechanism to prevent other sandboxed frames, including HTML preview frames, from calling that method.
This meant untrusted code in an iframe could insert HTML, and while `innerHTML` doesn't directly execute script elements it could be used to inject a new iframe *without* sandbox restrictions.
OpenAI’s CSP rules blocked inline scripts entirely, and only allowed script loading from a handful of domains, but one of those was YouTube - and the YouTube oEmbed endpoint could be used to reflect JavaScript back in a way that executed it.
Once the attack had JavaScript execution on ChatGPT, it was trivial to fetch private user data from APIs and exfiltrate it via an image reference.
The end result: you could create a ChatGPT share URL which, when visited by another signed-in user, could exfiltrate their private data or take actions on their behalf.
OpenAI closed the hole and paid out a $5,000 bug bounty, which I think was a bit cheap for a vulnerability this serious. |
2026-10-31 23:15:22+00:00 |
| dbreunig/nesformer |
https://github.com/dbreunig/nesformer |
Inspired by [qwenputer](https://divagr.com/blog/qwenputer) by Divyansh Agrawal, Drew Breunig baked a working emulator for a Nintendo Entertainment System 6502 CPU into the weights of Qwen3.5-4B. You can now play NES ROMs such as Super Mario Bros (very slowly) running inside Qwen!
In [a comment on Hacker News](https://news.ycombinator.com/item?id=50306442#50307402) Drew reveals the Opus 5.5 prompts he used to build this system:
> `Read this article and any relevant source code: https://divagr.com/blog/qwenputer. Then explore if you could emulate the chip and ram in a Nintendo Entertainment System (as people do today with FPGAs in MISTRs) using this technique. If so, what size model would you have to build and if you could use smaller faster ones, could you get it to be at the standard clockspeed.`
Followed by:
> `I think we should build it! Just for fun. It's okay if it's not fast. We want to be able to have the weights, and a cli to run them that we can point at a ROM.`
Apparently Opus found and then used [this collection of conformance tests](https://github.com/christopherpow/nes-test-roms/blob/master/other/nestest.txt) for the NES CPU released 15 years ago by Christopher Pow. |
2026-10-30 21:59:22+00:00 |